# Coder Eval — full documentation
> The complete text of every page published under https://coder-eval.com/docs,
> concatenated in navigation order for LLM consumption. This is the llms-full.txt
> companion to the link index at https://coder-eval.com/llms.txt.
Source: https://github.com/UiPath/coder_eval @ v0.11.5 — 25 pages.
Each section below is preceded by an HTML comment naming its source file and canonical URL.
---
# Evaluate AI coding agents & Claude Code skills — Coder Eval
**Coder Eval** (`pip install coder-eval` / `uv tool install coder-eval`) is an open-source framework for
**evaluating AI coding agents and their skills** — built for CLI and skill
builders — with sandboxing, reproducibility, and data-driven analysis. It is not
an "agentic coding" benchmark: it measures how effective *your* CLI and skills
are when used by coding agents such as **Claude Code**, **Codex**, **Google
Antigravity (Gemini)**, and **OpenCode**.
If you have ever asked *"how do I test whether my Claude Code skill actually
triggers?"*, *"how do I benchmark Claude Code vs. Codex on my own tasks?"*, or
*"how do I gate CI on coding-agent quality?"* — this is the framework for that.
## What Coder Eval does
- **Declarative YAML tasks** with pinned dependencies and clear success criteria
- **Sandboxed execution** in isolated environments with resource limits
- **Weighted, continuous scoring** (0.0–1.0) with fractional credit and thresholds
- **Many criterion types** — from file checks to code similarity and LLM-graded rubrics
- **Agent abstraction** — Claude Code, Codex, Antigravity (Gemini), and OpenCode today, extensible via a plugin SPI
- **Experiment layer** — A/B agent configs (models, tools, prompts) side-by-side
- **Full telemetry** — every tool call, token counts, and cost, with real-time streaming
## Use cases
- **Benchmark coding agents** — score an agent across a suite of tasks with weighted pass/fail thresholds
- **Compare models & configs** — A/B-test Claude Code vs. Codex vs. Gemini vs. OpenCode, model vs. model, tool-on vs. tool-off, prompt vs. prompt
- **Test whether a Claude Code skill triggers** — verify an agent actually engages a
target skill (`skill_triggered`) and score skill-driven suites (SkillsBench-style)
- **Keep skills fresh in CI** — re-validate skills on every change or on a schedule; catch silent regressions when models, prompts, or the skills themselves drift
- **Gate CI on agent quality** — run the suite in GitHub Actions and fail the build on regressions
- **Bring your own dataset** — fan one task out over many rows for larger benchmark suites
## Quick start
```bash
# 1. Install the coder-eval CLI on your PATH (isolated environment)
uv tool install coder-eval
# 2. Grab the runnable example tasks
git clone https://github.com/UiPath/coder_eval.git
cd coder_eval
# 3. Credentials — optional if you're already logged in to Claude Code
# (`claude login`, reused automatically); otherwise set ANTHROPIC_API_KEY
cp .env.example .env
# 4. Validate, run, and read your first evaluation
coder-eval plan tasks/hello_date.yaml # validate (no tokens spent)
coder-eval run tasks/hello_date.yaml # run your first evaluation
coder-eval report runs/latest # view the result
```
Prefer Coder Eval as a project dependency instead of a CLI tool? `uv add
coder-eval` or `pip install coder-eval`. Hacking on Coder Eval itself? Clone,
`uv sync --extra dev`, and prefix commands with `uv run`.
New here? Start with **[Tutorial 01 — Your First Evaluation](https://coder-eval.com/docs/tutorials/01-first-evaluation)**.
## Where to go next
| Guide | What's in it |
| --- | --- |
| [Tutorials](https://coder-eval.com/docs/tutorials) | Step-by-step walkthroughs — start here |
| [User Guide](https://coder-eval.com/docs/user-guide) | Full CLI, configuration, output, and environment-variable reference |
| [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) | The task-file schema — all criterion types, scoring, templates |
| [Claude Code](https://coder-eval.com/docs/agents/claude-code) | Configuring and running the default Claude Code agent |
| [Codex](https://coder-eval.com/docs/agents/codex) | Running the OpenAI Codex agent |
| [Antigravity (Gemini)](https://coder-eval.com/docs/agents/antigravity) | Running the Google Antigravity / Gemini agent |
| [OpenCode](https://coder-eval.com/docs/agents/opencode) | Running the OpenCode agent on open-weight models |
| [Run-Limit Parity](https://coder-eval.com/docs/agents/harness-parity) | What each run_limits field means on every harness |
| [A/B Experiments](https://coder-eval.com/docs/ab-experiments) | Compare models / tools / prompts across the same tasks |
| [Bring Your Own Dataset](https://coder-eval.com/docs/datasets) | Fan a single task out over a dataset |
| [Dialog Mode](https://coder-eval.com/docs/dialog-mode) | Evaluate agents in multi-turn conversation via a simulated user |
| [Docker Isolation](https://coder-eval.com/docs/docker-isolation) | The container sandbox driver, with custom images |
| [CI Gate & GitHub Action](https://coder-eval.com/docs/ci-gate) | Run Coder Eval as a CI gate — the Marketplace Action, JUnit output, score floor |
| [Claude Code Plugin](https://coder-eval.com/docs/plugin) | Install the Claude Code plugin — author, run, and analyze suites from inside the agent |
| [Extending Coder Eval](https://coder-eval.com/docs/extending) | Author a custom agent, criterion, or model pricing via the plugin SPI |
| [Report Schema](https://coder-eval.com/docs/report-schema) | Field-level reference for run.json / variant.json / task.json |
| [How It Compares](https://coder-eval.com/docs/comparison) | vs. SWE-bench, SkillsBench, Harbor, OpenAI Evals, hand-rolled scripts |
## How Coder Eval compares
- **vs. SWE-bench and fixed benchmarks** — SWE-bench is a fixed dataset; Coder Eval
is a *framework* for authoring your own tasks in YAML, so you evaluate the skills
and workflows you care about (and can still wrap a fixed dataset via
[Bring Your Own Dataset](https://coder-eval.com/docs/datasets)).
- **vs. other agent-eval frameworks (e.g. Harbor) and LLM-eval tools (OpenAI Evals)** —
OpenAI Evals grades model text; Harbor targets large-scale agent eval and RL
optimization. Coder Eval is purpose-built for coding-agent/skill suites — weighted
0.0–1.0 file/command scoring, a `skill_triggered` activation check, an experiment
layer for A/Bs, and evalboard. See the full comparison.
- **vs. hand-rolled scripts** — reproducible sandboxes, weighted criteria,
cost/token telemetry, A/B experiments, and CI-ready pass/fail gates out of the box.
See the full [comparison](https://coder-eval.com/docs/comparison) for details.
---
# Tutorials
Step-by-step, task-oriented walkthroughs. Start here if you're new; for the
complete command/config reference see the [User Guide](https://coder-eval.com/docs/user-guide), and for
the task-file schema see the [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide).
| # | Tutorial | You'll learn |
| - | --- | --- |
| 01 | [Your first evaluation](https://coder-eval.com/docs/tutorials/01-first-evaluation) | Install, configure a key, and run + read your first eval |
| 02 | [Running Coder Eval in CI](https://coder-eval.com/docs/tutorials/02-ci-pipeline) | Wire the suite into GitHub Actions with a pass/fail gate |
| 03 | [Browsing results with evalboard](https://coder-eval.com/docs/tutorials/03-evalboard-local) | Explore runs in a local web UI — pass rates, timelines, artifacts |
| 04 | [Writing a task](https://coder-eval.com/docs/tutorials/04-writing-a-task) | Author a task YAML with success criteria from scratch |
| 05 | [Comparing two models](https://coder-eval.com/docs/tutorials/05-comparing-models) | Use the experiment layer to A/B two configurations |
| 06 | [Running tasks in Docker isolation](https://coder-eval.com/docs/tutorials/06-use-docker-isolation) | Run each task in a fresh container; add task-specific dependencies |
| 07 | [Driving Coder Eval from Claude Code](https://coder-eval.com/docs/tutorials/07-plugin-in-claude-code) | Install the plugin and drive the whole loop — scaffold, author, review, run, analyze — from slash commands |
> Contributions welcome — add a numbered `NN-title.md` file and link it in the
> table above. Keep tutorials short, copy-pasteable, and outcome-focused.
---
# Tutorial 01 — Your First Evaluation
By the end you'll have installed `coder-eval`, pointed it at an API key, run a
built-in task, and read the result. ~5 minutes.
## Prerequisites
- **Python 3.13+**
- **[uv](https://docs.astral.sh/uv/)** — `brew install uv` (macOS) or `pip install uv`
- **Claude CLI** — `brew install claude` ([install guide](https://docs.anthropic.com/claude/docs/claude-code))
- An **Anthropic API key**
## 1. Install
```bash
git clone https://github.com/UiPath/coder_eval.git
cd coder_eval
uv sync --extra dev
```
> **Just want the CLI?** `uv tool install coder-eval` installs the released
> `coder-eval` command on your PATH in its own isolated environment — then run
> every command below without the `uv run` prefix. Keep the clone anyway: the
> example `tasks/` used in this tutorial live in the repo.
`uv sync` creates a `.venv/`. **Activate it** to run `coder-eval` directly and
drop the `uv run` prefix used throughout this tutorial:
```bash
source .venv/bin/activate
# now `coder-eval ...` works on its own; e.g. `coder-eval run tasks/hello_date.yaml`
```
The `uv run coder-eval ...` form below works with or without activating — `uv run`
resolves the same `.venv` — so use whichever you prefer.
## 2. Configure your API key
```bash
cp .env.example .env
# Edit .env and set ANTHROPIC_API_KEY=sk-ant-...
```
> **Heads up:** usage telemetry is **on by default**. To turn it off, add
> `TELEMETRY_ENABLED=false` to your `.env`. See the
> [User Guide](https://coder-eval.com/docs/user-guide#usage-telemetry).
## 3. Validate before running
```bash
uv run coder-eval plan tasks/hello_date.yaml
```
`plan` checks the task's syntax, required tools, and API keys without spending any
tokens — a good habit before every run.
## 4. Run your first task
```bash
uv run coder-eval run tasks/hello_date.yaml
```
This spins up an isolated sandbox, sends the task prompt to the agent, records
every tool call, and scores the result against the task's success criteria.
Add `--stream full` to watch the agent work in real time:
```bash
uv run coder-eval run tasks/hello_date.yaml --stream full
```
## 5. Read the result
```bash
uv run coder-eval report runs/latest
```
`runs/latest` is a symlink to the newest `runs//`. The per-task result lives at
`runs/latest////task.json` (with `task.log` and `artifacts/` beside
it); the run-level `run.json`/`run.md` sit at the run root. See the
[Output Structure](https://coder-eval.com/docs/user-guide#output-structure) reference for the full layout.
## Next steps
- **Write your own task** → [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide)
- **Compare configurations** → [A/B Experiments](https://coder-eval.com/docs/ab-experiments)
- **Full CLI & config reference** → [User Guide](https://coder-eval.com/docs/user-guide)
---
# Tutorial 02 — Running Coder Eval in CI
Run your evaluation suite automatically in GitHub Actions: on demand, on a
schedule, or as a merge gate. By the end you'll have a workflow that installs
`coder-eval`, runs a set of tasks, turns the results into a pass/fail verdict, and
uploads the reports as artifacts.
This mirrors how the [UiPath skills repo](https://github.com/UiPath/skills)
drives its task tree under
[`tests/tasks/`](https://github.com/UiPath/skills/tree/main/tests/tasks) — a task
directory checked into the repo, a pinned `coder-eval` version, and a
`task.json`-based verdict — distilled to the parts that transfer to any project.
## The shape of a Coder Eval CI job
Every CI setup, however elaborate, is the same five steps:
1. **Install** a pinned `coder-eval` and set up Python/uv.
2. **Provide credentials** via repository secrets (never hard-code keys).
3. **Run** `coder-eval` over a glob of task files into a known run directory.
4. **Gate** — parse the per-task `task.json` files into a pass/fail exit code.
5. **Upload** the run directory as an artifact for later inspection.
## 1. Lay out your tasks
Keep your task YAMLs in the repo — e.g. a `tests/tasks/` tree grouped by area:
```
tests/
└── tasks/
├── group-a/
│ ├── task-one.yaml
│ └── task-two.yaml
└── group-b/
└── task-three.yaml
```
## 2. Add the workflow
Create `.github/workflows/coder-eval.yml`:
```yaml
name: Coder Eval
on:
workflow_dispatch:
inputs:
task_globs:
description: 'Space-separated globs, e.g. tests/tasks/group-a/**/*.yaml'
type: string
required: true
default: 'tests/tasks/**/*.yaml'
parallelism:
description: 'Parallel tasks (-j). Keep ≤ runner vCPUs (ubuntu-latest = 4).'
type: string
default: '4'
# Or run on a schedule to keep skills up to date as models change — a skill
# that quietly stops triggering shows up as a failing task before users hit it:
# schedule:
# - cron: '0 6 * * *' # 06:00 UTC daily
# Or gate merges:
# pull_request:
# paths: ['tests/tasks/**']
concurrency:
group: coder-eval-${{ github.ref }}
cancel-in-progress: false
jobs:
eval:
runs-on: ubuntu-latest
timeout-minutes: 120
env:
# Usage telemetry is on by default — turn it off in CI.
TELEMETRY_ENABLED: 'false'
steps:
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
with:
python-version: '3.13'
- uses: astral-sh/setup-uv@v4
- name: Install coder-eval
# Install the published package. In a real gate, pin an exact released
# version (coder-eval==X.Y.Z) so a harness upgrade can't move your results.
run: uv pip install --system coder-eval
- name: Run evaluations
env:
# Provide exactly the credentials your tasks need.
ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
TASK_GLOBS: ${{ inputs.task_globs }}
PARALLELISM: ${{ inputs.parallelism }}
run: |
# TASK_GLOBS is intentionally unquoted so the shell expands the globs.
coder-eval run $TASK_GLOBS -j "${PARALLELISM:-4}" -v
- name: Verdict (fail the job if any task didn't pass)
if: always()
run: |
set -uo pipefail
run_dir=$(ls -td runs/*/ 2>/dev/null | head -n 1 || true)
if [ -z "$run_dir" ]; then
echo "FAIL — no run directory produced" | tee -a "$GITHUB_STEP_SUMMARY"
exit 1
fi
python - "$run_dir" <<'PY' | tee -a "$GITHUB_STEP_SUMMARY"
import json, pathlib, sys
rows = [json.loads(p.read_text(encoding="utf-8"))
for p in sorted(pathlib.Path(sys.argv[1]).rglob("task.json"))]
for r in rows:
print(f"- {r.get('task_id','?')}: {r.get('final_status','?')}")
ok = sum(1 for r in rows if r.get("final_status") == "SUCCESS")
print(f"\n**{ok}/{len(rows)} PASS**")
sys.exit(0 if rows and ok == len(rows) else 1)
PY
- name: Upload run reports
if: always()
uses: actions/upload-artifact@v4
with:
name: coder-eval-${{ github.run_id }}
# `**` matches the replicate-index segment coder_eval adds
# (runs/////).
path: |
runs/*/run.json
runs/*/run.md
runs/**/task.json
runs/**/task.log
if-no-files-found: warn
retention-days: 14
```
## How the pieces work
- **Telemetry off in CI.** `TELEMETRY_ENABLED: 'false'` at the job level keeps CI
runs out of the usage stream. (See the [User Guide](https://coder-eval.com/docs/user-guide#usage-telemetry).)
- **Pin the version.** Pinning an exact release (`coder-eval==X.Y.Z`) makes runs
reproducible; bump it deliberately. A single source of truth (a
`tests/.coder-eval-version` file read in a resolve step) scales better than
hard-coding it in the YAML.
- **Run directory.** Omitting `--run-dir` lets the harness create `runs//` (and a
`runs/latest` symlink); the verdict step finds the newest via `ls -td runs/*/` and the
upload globs match `runs/*/run.json`. The per-task result is
`runs/////task.json` — see [Output Structure](https://coder-eval.com/docs/user-guide#output-structure).
- **The verdict is just `task.json` parsing.** `final_status == "SUCCESS"` is the
pass condition. `sys.exit(1)` on any non-pass fails the job; writing to
`$GITHUB_STEP_SUMMARY` puts the table on the run's summary page.
- **`if: always()`** on the verdict and upload steps means you still get results
even when a task fails.
## Shortcut: the packaged action
The five steps above spell out the mechanics, but Coder Eval also ships a
composite action — on the Marketplace as
[**coder_eval**](https://github.com/marketplace/actions/coder_eval) — that
bundles install + run + JUnit report + job-summary + fail-on-failure into one
step:
```yaml
- uses: actions/setup-node@v4 # the claude-code agent needs the Claude CLI…
with: { node-version: '20' }
- run: npm install -g @anthropic-ai/claude-code
- uses: UiPath/coder_eval@v0 # …then run the gate (pin @vX.Y.Z in production)
with:
tasks: tests/tasks/*.yaml tests/tasks/*/*.yaml
model: claude-sonnet-5
env: |
ANTHROPIC_API_KEY=${{ secrets.ANTHROPIC_API_KEY }}
```
The action is agent-agnostic — it installs `coder-eval` but not the agent
runtime, so provide the `claude` CLI (or your agent's runtime) in the job first.
See the [CI Gate reference](https://coder-eval.com/docs/ci-gate) for the full inputs table, JUnit
output, the score-floor gate, and the fork/`pull_request_target` security caveat.
The rest of this tutorial's hand-rolled workflow is still useful when you need
finer control than the action's inputs expose.
## Publishing test results (JUnit)
The verdict step above parses `task.json` by hand. If your CI already ingests
JUnit XML — for the per-test annotations, history, and flake tracking most CI
systems render from it — let `coder-eval` emit it directly instead. Add
`--junit-xml` to the run:
```yaml
- name: Run evaluations
run: coder-eval run $TASK_GLOBS -j 4 --junit-xml coder-eval-junit.xml
```
The file is written **before** the exit-code decision, so a failing run still
produces a report. You can also regenerate it from any existing run directory
without re-running the suite:
```bash
coder-eval report runs/latest -f junit # writes runs/latest/junit.xml
coder-eval report runs/latest -f junit -o out.xml # custom path
```
The mapping: one `` per task row (grouped into a `` per
variant), failed/errored rows carry a ``/`` with the per-criterion
breakdown, skipped tasks and failing suite gates get their own synthetic suites.
Feed the file to whatever your platform uses to render test results. On GitHub
Actions, [`mikepenz/action-junit-report`](https://github.com/mikepenz/action-junit-report):
```yaml
- name: Publish test report
if: always()
uses: mikepenz/action-junit-report@v5
with:
report_paths: coder-eval-junit.xml
```
On Azure DevOps, `PublishTestResults@2`:
```yaml
- task: PublishTestResults@2
condition: always()
inputs:
testResultsFormat: 'JUnit'
testResultsFiles: 'coder-eval-junit.xml'
```
## Secrets
Add these under **Settings → Secrets and variables → Actions**:
| Secret | For |
| --- | --- |
| `ANTHROPIC_API_KEY` | Direct Anthropic API (default backend) |
| `AWS_BEARER_TOKEN_BEDROCK`, `AWS_REGION`, `BEDROCK_MODEL` | Only if you run `--backend bedrock` |
## Next steps
The five steps above are the whole core. As a suite grows you'll layer on cost
guardrails, matrix partitioning, scheduled sweeps, and artifact hygiene — the
`coder-eval run` call stays the same, only the wrapper grows:
- **Full CLI & config reference** → [User Guide](https://coder-eval.com/docs/user-guide)
- **Pin CI agent/model via an experiment** → [A/B Experiments](https://coder-eval.com/docs/ab-experiments)
- **A worked, scaled-up pipeline** → the [UiPath skills repo](https://github.com/UiPath/skills)
workflow (cost guardrail, matrix partitioning, nightly schedule).
---
# Tutorial 03 — Browsing Results Locally with evalboard
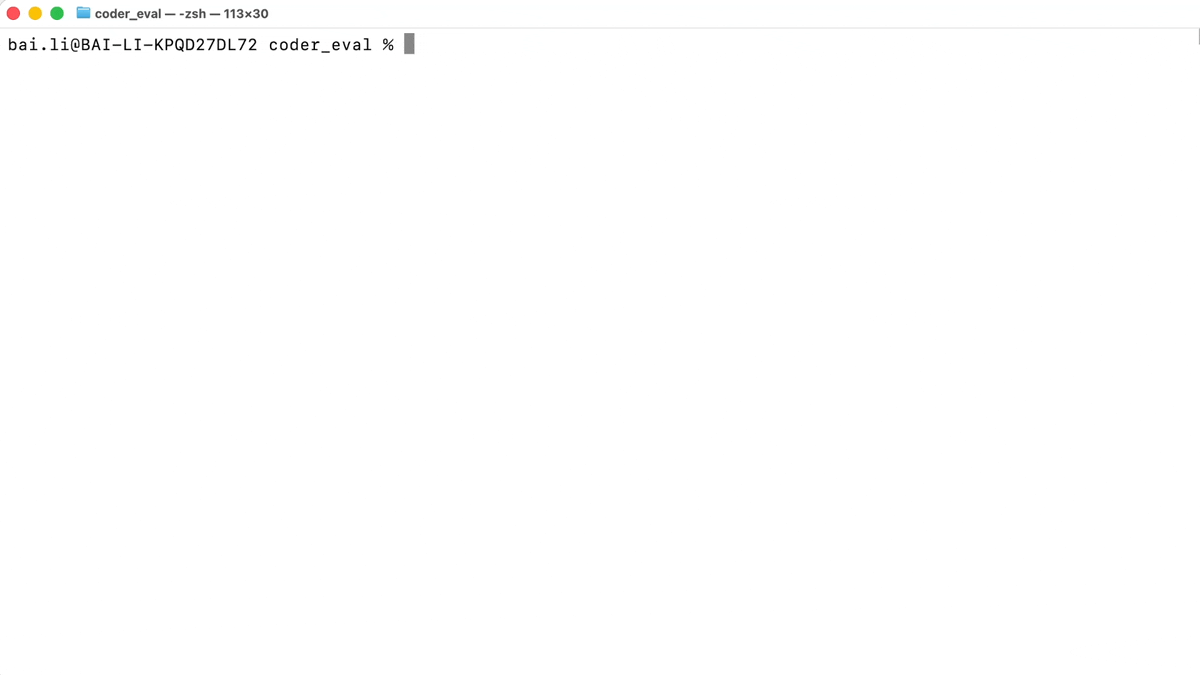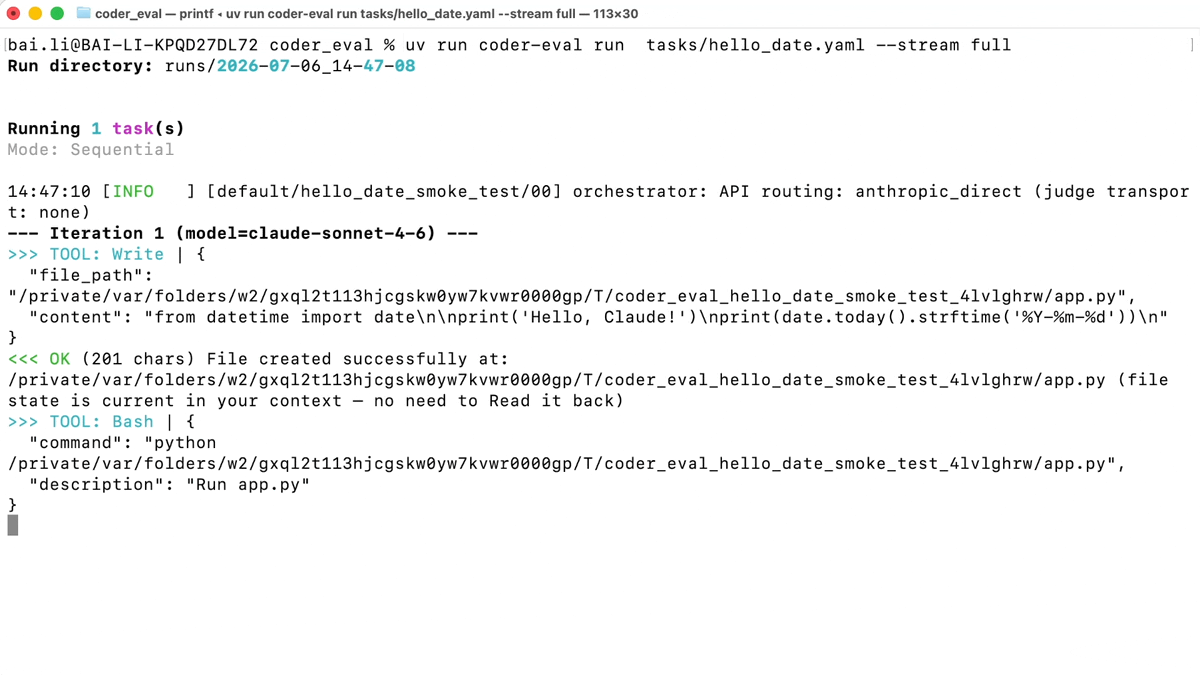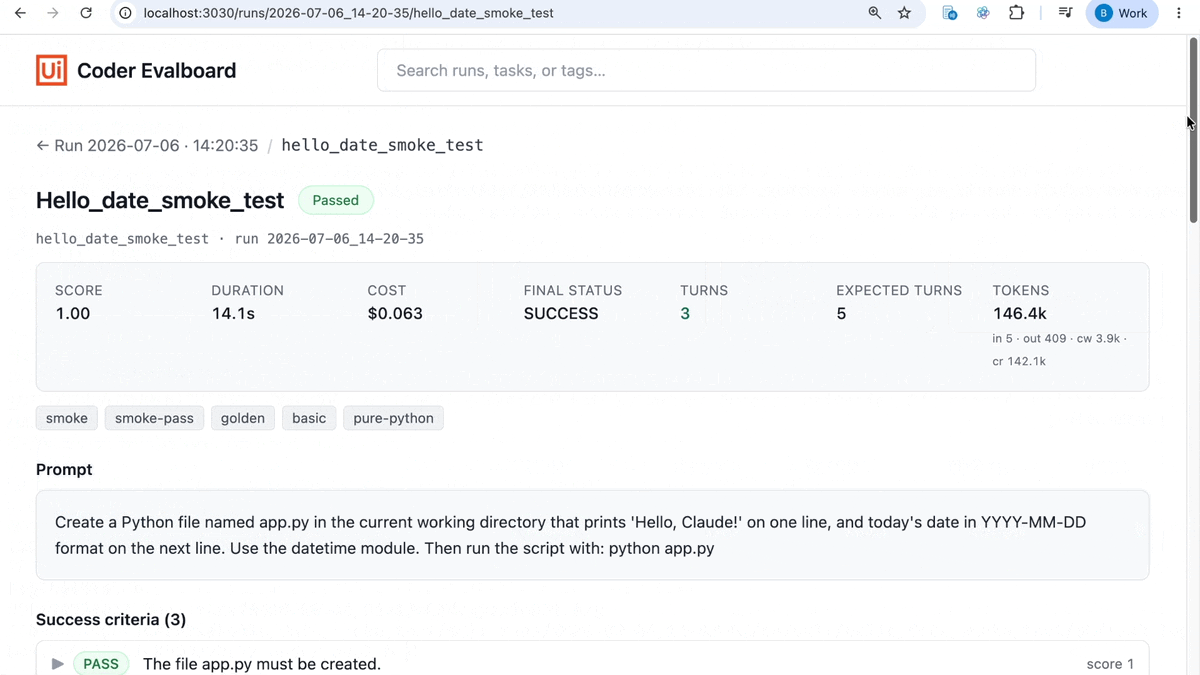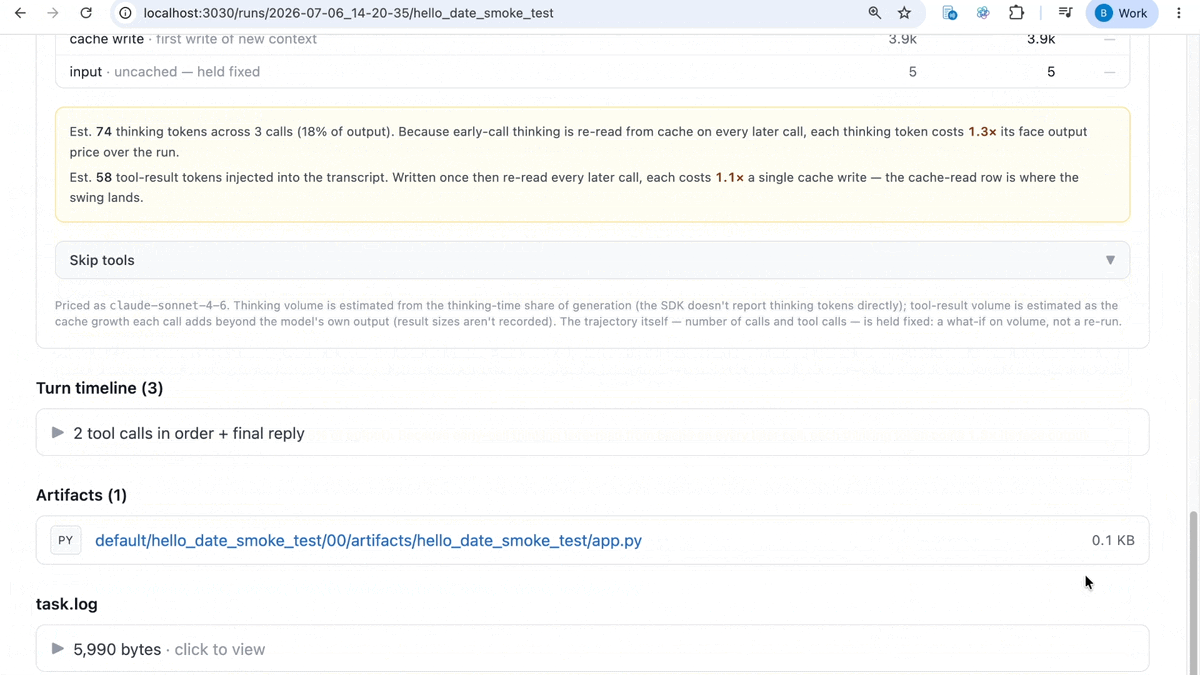
`coder-eval` writes results as JSON, markdown, and logs under `runs/`. **evalboard**
is a small local web UI that renders those runs — pass rates, per-task detail,
tool and message timelines, artifact downloads — so you can explore a run in a
browser instead of reading raw files. It reads straight from your filesystem: no
database, no backend, nothing leaves your machine.
## Prerequisites
- A completed run (do [Tutorial 01](https://coder-eval.com/docs/tutorials/01-first-evaluation) first — you need a
`runs//` directory with a `run.json`).
- **Node.js 20+** and **pnpm**. The repo pins pnpm via `packageManager`, so the
simplest way is Corepack:
```bash
corepack enable # provides the pinned pnpm
```
## 1. Install dependencies
```bash
cd evalboard
pnpm install
```
## 2. Point evalboard at your runs and start it
```bash
# Use coder_eval's own ./runs directory (shortcut):
pnpm dev:local
# ...or point at any runs directory (absolute path):
EVALBOARD_LOCAL_RUNS_DIR=/absolute/path/to/runs pnpm dev
```
Then open **http://localhost:3030**.
> Only directories that contain a `run.json` appear in the index — empty shells
> and the `latest` symlink are filtered out. If your run list is empty, confirm
> the run actually completed and that `EVALBOARD_LOCAL_RUNS_DIR` points at the
> parent `runs/` folder (not a single run).
## 3. Explore
| Page | What it shows |
| --- | --- |
| `/` | The 20 most recent runs, one clickable row each |
| `/runs/latest` | Redirects to the newest run |
| `/runs/` | Run summary — pass rate, cost, duration — plus one row per task (green = pass, red = fail). "Download run (.zip)" bundles the whole folder |
| `/runs//` | Per-task detail: success-criteria cards, the tool timeline, the message timeline (per-message tokens, expandable into thinking/tool/text), artifact downloads, and the tail of `task.log` |
| `/trends` | Per-task pass rate and average duration/cost/turns across recent runs |
`` matches the `task_id` in the results and the subdirectory name under
`//` — the same layout described in the
[Output Structure](https://coder-eval.com/docs/user-guide#output-structure) reference.
## How it works (and why it's safe to run locally)
- **Filesystem-only in local mode.** Setting `EVALBOARD_LOCAL_RUNS_DIR` makes
evalboard read runs from that directory and never reach out to any remote
storage.
- **OSS edition by default.** evalboard runs in its open-source edition with no
configuration; UiPath-internal surfaces are opt-in via `EVALBOARD_EDITION=internal`.
- **No database.** Run listings and detail pages are rendered on the fly from the
files Coder Eval already wrote.
## Next steps
- **Produce more runs to compare** → [A/B Experiments](https://coder-eval.com/docs/ab-experiments)
- **Automate runs in CI, then download the artifact and open it here** →
[Running Coder Eval in CI](https://coder-eval.com/docs/tutorials/02-ci-pipeline)
---
# Tutorial 04 — Writing a Task
By the end you'll have authored a task YAML from scratch — a prompt, an isolated
sandbox, a soft turn budget, and three success criteria — validated it without
spending tokens, run it, and read the score. ~10 minutes.
## Prerequisites
- A working `coder-eval` checkout with an API key configured — see
[Tutorial 01](https://coder-eval.com/docs/tutorials/01-first-evaluation).
## 1. Create the task file
A task is a single YAML file: the prompt sent to the agent, the agent
configuration, and the criteria that score whatever the agent leaves behind in
the sandbox. Create `tasks/fizzbuzz.yaml`:
```yaml
task_id: "fizzbuzz"
description: "Write and run a classic FizzBuzz script."
initial_prompt: >
Create a Python file named fizzbuzz.py in the current working directory that
prints the numbers 1 to 15, one per line, replacing multiples of 3 with
'Fizz', multiples of 5 with 'Buzz', and multiples of both with 'FizzBuzz'.
Then run it with: python fizzbuzz.py
agent:
type: "claude-code"
model: "claude-sonnet-5"
permission_mode: "acceptEdits"
setting_sources: [] # isolate the sandbox from your own CLAUDE.md/settings
run_limits:
expected_turns: 5 # soft target — warns when exceeded, never aborts
success_criteria:
- type: "file_exists"
path: "fizzbuzz.py"
description: "The script must be created."
- type: "file_contains"
path: "fizzbuzz.py"
includes: ["FizzBuzz"]
description: "The script must produce the combined FizzBuzz case."
- type: "run_command"
command: "python fizzbuzz.py"
timeout: 10
description: "The script must run successfully."
```
What each block does:
- **`initial_prompt`** — delivered to the agent inside a fresh sandbox
directory; all file paths in the criteria are relative to that sandbox.
- **`agent.setting_sources: []`** — keeps your own `CLAUDE.md` and local
settings out of the sandbox. Without it, a large host `CLAUDE.md` is injected
into every API call, inflating cache-creation tokens and cost. Leave it out
only when the task needs your MCP servers.
- **`run_limits.expected_turns`** — an efficiency target, not a cap: exceeding
it logs a warning and adds a report badge but never aborts (use
`run_limits.max_turns` for a hard cap).
- **`success_criteria`** — each criterion scores 0.0–1.0 and supports `weight`
(default 1.0) and `pass_threshold` (default 0.9). `run_command` here only
checks the exit code; it can also match stdout (`expected_stdout`) or read a
continuous score from stdout — see the
[Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) for all 14 criterion
types and every field.
## 2. Validate without spending tokens
```bash
uv run coder-eval plan tasks/fizzbuzz.yaml
```
`plan` checks the YAML schema, required tools, and API keys without calling the
model. Typos in criterion fields fail here (task models reject unknown keys)
instead of after a paid run.
## 3. Run it
```bash
uv run coder-eval run tasks/fizzbuzz.yaml
```
## 4. Read the result
```bash
uv run coder-eval report runs/latest
```
The report shows one row per criterion — score, pass/fail against its
threshold, and the weighted total. The agent's full transcript and the files it
created are preserved under `runs/latest////` (`task.json`,
`task.log`, `artifacts/`).
## Where to go deeper
- **All 14 criterion types, weights, thresholds** → [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide)
- **Stop a run early once the key criteria are decided** (an opt-in `stop_early:` block on a criterion; `run_limits.stop_early: false` is the run-level kill switch) → [Task Definition Guide → `stop_early`](https://coder-eval.com/docs/task-definition-guide#stop_early-opt-in-early-stop)
- **Fan one task out over a dataset of rows** → [Bring Your Own Dataset](https://coder-eval.com/docs/datasets)
- **Full CLI & config reference** → [User Guide](https://coder-eval.com/docs/user-guide)
- **Compare two configurations on this task** → [Tutorial 05](https://coder-eval.com/docs/tutorials/05-comparing-models)
---
# Tutorial 05 — Comparing Two Models
By the end you'll have A/B-tested two Claude models on the same task through the
experiment layer and read the cross-variant comparison report. Agents are
stochastic, so eyeballing two separate runs is noise — the experiment layer runs
both arms under identical conditions and scores them side by side. ~10 minutes.
## Prerequisites
- A working `coder-eval` checkout with an API key configured — see
[Tutorial 01](https://coder-eval.com/docs/tutorials/01-first-evaluation). This tutorial uses the built-in
`tasks/hello_date.yaml`.
## 1. Define the experiment
An experiment runs the same task once per **variant** and reports the arms side
by side — one config file, no copy-pasted tasks. Create
`experiments/haiku-vs-sonnet.yaml`:
```yaml
experiment_id: haiku-vs-sonnet
description: "Compare Haiku vs Sonnet on the same task"
defaults:
agent:
type: claude-code
permission_mode: bypassPermissions
variants:
- variant_id: haiku
agent:
model: claude-haiku-4-5-20251001
- variant_id: sonnet
agent:
model: claude-sonnet-5
```
A variant declares only what differs — here just `agent.model`. Everything else
merges in from `defaults` and the task itself, so both arms are identical except
for the model. (The repo ships `experiments/model-comparison.yaml` as a
Sonnet-vs-Opus version of the same shape.)
## 2. Run both arms
```bash
uv run coder-eval run tasks/hello_date.yaml -e experiments/haiku-vs-sonnet.yaml
```
Bare names resolve too: `-e haiku-vs-sonnet` finds
`experiments/haiku-vs-sonnet.yaml`.
## 3. Read the comparison
The run writes the cross-variant report automatically when it finishes — there's
no separate report command for experiments:
```bash
cat runs/latest/experiment.md
```
It ranks the variants by weighted score and shows per-task results, durations,
and token usage side by side. Drill down from there:
- `runs/latest/experiment.json` — the full result data.
- `runs/latest//variant.md` (e.g. `runs/latest/haiku/variant.md`) —
per-variant aggregate detail.
## 4. Add statistical power (optional)
Agents are stochastic — one run per arm is noise, not signal. Repeat each arm to
see variance instead of a point estimate:
```bash
uv run coder-eval run tasks/hello_date.yaml -e haiku-vs-sonnet --repeats 5
```
(or set `repeats: 5` under `defaults:` in the experiment file). The report then
aggregates per-replicate scores per variant.
## Where to go deeper
- **Variants, prompt mutations, replicates, skill on/off comparisons** →
[A/B Experiments](https://coder-eval.com/docs/ab-experiments)
- **Write the task you're comparing on** → [Tutorial 04](https://coder-eval.com/docs/tutorials/04-writing-a-task)
- **Full CLI & config reference** → [User Guide](https://coder-eval.com/docs/user-guide)
---
# Tutorial 06 — Running Tasks in Docker Isolation
By default a task runs in a temp-dir sandbox on your host. This tutorial switches
that to a fresh **Docker container per task** — strong host isolation and a
pinned, reproducible toolchain — then shows how to add task-specific
dependencies. ~10 minutes.
For the complete reference, see [Docker Isolation](https://coder-eval.com/docs/docker-isolation).
## Why
- **Isolation** — agent-generated code can't touch files or the network outside
the sandbox.
- **Reproducibility** — the image bakes in Python 3.13, Node 22 LTS, the Claude
CLI, `uv`, and the matching `coder_eval` version, so results don't drift with
host upgrades.
Aggregation (scores, reports, evalboard) still happens on the host — each
container is a sealed "run one task → emit one `task.json`" worker.
## Prerequisites
- You've done [Tutorial 01](https://coder-eval.com/docs/tutorials/01-first-evaluation) (installed + ran a task).
- **Docker** installed and the daemon running — check with `docker info`. If that
command errors, install Docker first (next section).
## Installing Docker
Pick your OS. After installing, verify with:
```bash
docker info # daemon reachable? (no error = good)
docker run --rm hello-world # pulls a tiny image and runs it
```
### Linux
Install **Docker Engine** (the daemon runs natively — no VM needed). The official
convenience script covers most distros (Ubuntu, Debian, Fedora, …):
```bash
curl -fsSL https://get.docker.com | sh
```
Or use your distro's packages directly — e.g. Ubuntu/Debian:
```bash
sudo apt-get update
sudo apt-get install -y docker.io
```
Then start the daemon and allow your user to run Docker without `sudo`:
```bash
sudo systemctl enable --now docker # start now + on boot
sudo usermod -aG docker "$USER" # add yourself to the docker group
newgrp docker # apply the group in this shell (or log out/in)
```
For the packaged Docker Engine (Docker CE with Compose/Buildx), follow the
distro-specific apt/dnf repo steps at
` (also tagged `:latest`) with both
built-in agents (claude-code + Codex) and **needs no credentials**. ``
is your installed `coder_eval` version (find it with `coder-eval --version`).
Rebuild only when you upgrade `coder_eval` or the pinned toolchain. It's all you
need for the common case (steps 2–5 below).
Related build targets:
| Target | Builds | When you need it |
| --- | --- | --- |
| `make docker-image` | `coder-eval-agent` (rebase base) | The default — the base image from which task Dockerfile should inherit `FROM coder-eval-agent` (step 5). |
| `make docker-images` | **both** `coder-eval-agent` **and** `coder-eval-runtime` | coder-eval-runtime is used when a task Dockerfile brings its own base image.|
| `make docker-image-full` | `coder-eval-agent` **+ the `uipath` extra** | Tasks that shell out to the `uipath` CLI. The `uipath` SDK resolves from public PyPI — no credentials needed. |
> `make docker-images` is just `make docker-image` + `make coder-eval-runtime`.
> Both base images are independent and persistent — build once, run any mix of
> rebase and inject tasks. See
> [Docker Isolation](https://coder-eval.com/docs/docker-isolation#tasks-that-bring-their-own-base-image-the-runtime-kit-coder-eval-runtime)
> for inject-mode details.
## 2. Run any task in a container
Add `--driver docker` to the `run` command from Tutorial 01:
```bash
uv run coder-eval run tasks/hello_date.yaml --driver docker
```
`--driver docker` is a thin alias for `-D sandbox.driver=docker`. Everything else
(streaming, reports, exit codes) works exactly as before.
## 3. Confirm it ran in Docker
The tell-tale sign is a **`docker.log`** in the task dir (the container's
stdout/stderr) — the tempdir driver never produces one:
```bash
find runs/latest -name docker.log
```
And if you `docker ps` *during* a run you'll see one `coder-eval--…`
container per in-flight task; they're removed (`--rm`) when the task finishes.
Scores and reports are still read the usual way (`coder-eval report runs/latest`)
— the driver doesn't change how results are aggregated.
## 4. Make a task always use Docker
Rather than passing the flag every time, set it in the task YAML:
```yaml
sandbox:
driver: docker
docker:
network: bridge # or "none" for a fully sealed run (no network)
image: my-custom:tag # optional: override the default framework image
```
## 5. Add task-specific dependencies with a Dockerfile
When a task needs extra system packages or Python libs, ship a Dockerfile and
have coder-eval build it before the run:
```yaml
sandbox:
driver: docker
docker:
dockerfile_path: ./environment/Dockerfile # relative to the task YAML
```
```dockerfile
# environment/Dockerfile
FROM coder-eval-agent:latest # REQUIRED — inherits the runtime + entrypoint
RUN apt-get update && apt-get install -y --no-install-recommends poppler-utils
RUN pip install --no-cache-dir PyMuPDF==1.24.10
COPY input/ /root/input/ # build context = this Dockerfile's parent dir
```
- The built image is cached as `coder-eval-task-:built`, so repeat runs
reuse Docker's layer cache — edit the Dockerfile and only changed layers
rebuild.
- `dockerfile_path` takes precedence over any `image:` value.
> **⚠️ The `FROM coder-eval-agent:` line is mandatory.** The container
> runs the coder-eval orchestrator via the framework image's `ENTRYPOINT`; a bare
> base (e.g. `FROM ubuntu:24.04`) has no entrypoint and the run fails with
> `exec: "--output": executable file not found in $PATH`. coder-eval detects this
> after the build and aborts with a hint. (`:latest` and `:` are both
> tagged by `make docker-image`, so either works in the `FROM`.) Tasks whose
> Dockerfile brings its own base — e.g. Fedora/`dnf` — use
> inject-mode instead; see
> [Docker Isolation](https://coder-eval.com/docs/docker-isolation#tasks-that-bring-their-own-base-image-the-runtime-kit-coder-eval-runtime).
## Next steps
- **Full Docker reference** (network modes, runtime kit, cleanup) →
[Docker Isolation](https://coder-eval.com/docs/docker-isolation)
- **Task-file schema** → [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide)
- **Full CLI & config reference** → [User Guide](https://coder-eval.com/docs/user-guide)
---
# Tutorial 07 — Driving Coder Eval from Claude Code
By the end you'll have installed the Coder Eval plugin and driven a full loop from
slash commands: scaffold, author, review, run, analyze. ~15 minutes.
**Cost:** steps 1–2 are free; budget **one paid agent run** for steps 3–4. The
optional step 5 is one run *per row* — 16 for an 8/8 suite — so budget it
separately.
## Prerequisites
- Claude Code installed and working.
- The `coder-eval` CLI. **Installing the plugin does not install it** — a plugin
ships skills, not packages. You can let the skills handle it (`init`, `task` and
`check-skill` check for it and offer to install it, asking first), or do it now:
```bash
uv tool install coder-eval # or: pip install coder-eval
coder-eval --version
```
- An API key for whichever agent your tasks use (`ANTHROPIC_API_KEY` for the
default `claude-code` agent).
Steps 2 onward assume you are in **your own repository** — not the `coder_eval`
clone used by Tutorials 01 and 04.
## 1. Install the plugin
This repository is itself the marketplace. Both of these are typed at the Claude
Code prompt, not in your shell:
```
/plugin marketplace add UiPath/coder_eval
/plugin install coder-eval@coder-eval
```
Verify by typing `/coder-eval:`. You should see six commands: `init`,
`check-skill`, `task`, `lint-tasks`, `analyze`, `ci`. Three of them — `init`,
`check-skill` and `task` — drive the same `coder-eval` CLI you would type by hand,
so what they write is a normal file you can commit, diff and run in CI. The other
three never invoke it: `analyze` reads a finished run directory, `ci` writes a
workflow, and `lint-tasks` only reads task files and reports.
## 2. Scaffold a suite
```
/coder-eval:init
```
It scans for what is worth evaluating (Claude Code skills, an MCP server, a CLI),
reports what it found, then scaffolds a task directory with one runnable task.
**Note the directory it reports** — the layout varies by repository (`tasks/`,
`tests/tasks/`, …) and later steps need that path:
```bash
ls tasks/ # or whichever path init reported
cat tasks/*.yaml | head -40
```
Read that task before moving on. It is the shape every later task here gets
modeled on, and step 3 is easier to follow once you have seen one.
## 3. Author a task, then review it
```
/coder-eval:task a task that checks the CLI can list processes as JSON
```
It designs criteria against the bundled
[task-quality rubric](https://github.com/UiPath/coder_eval/blob/main/plugins/coder-eval/reference/task-rubric.md),
then re-checks the files it wrote against the rubric's framing question: *what is
the cheapest thing an agent could do that scores full marks?*
Then it validates with `coder-eval plan` and **offers to run the task, asking
first**. Take the offer — step 4 needs a run. Read the score the way the skill
does: a **1.000 on a first attempt means re-read the criteria**, not celebrate, and
a failure is a question about *which layer* is wrong (the prompt, or the skill or
tool it depends on) before it is a prompt edit.
Now review what you already have. Point the read-only linter at the directory from
step 2:
```
/coder-eval:lint-tasks tasks/
```
Same rubric, applied to files on disk. Per task you get a severity, a line
reference and a concrete fix, covering criteria that cannot fail, prompts that give
away the answer, fixtures with no cleanup and near-duplicates. Gameability findings
name the weight at risk, e.g. *"A single `--file` call satisfies 14.0 of 33.0
weight"*. It never edits a file, and it scores test design only, so it closes by
suggesting `coder-eval plan` for the schema half. Watch for `⚠` notices there: an
unknown top-level key warns rather than fails.
## 4. Read the result
If you accepted the run in step 3, you already have a run directory: the skill
invoked the CLI through Bash on your behalf. By hand it is the same command, which
is the whole point of the plugin being a driver rather than a separate product:
```bash
coder-eval run # discovers tasks recursively; or pass explicit paths
ls runs/latest/ # the run that was just written
```
Hand it back to the agent:
```
/coder-eval:analyze runs/latest
```
It writes `analysis.md` **into** the run directory, containing:
- a TL;DR and a score breakdown,
- per-task findings with concrete fixes, ranked by estimated score recovery,
- on suites over 20 tasks, failures clustered into systemic patterns instead of
repeated per task.
## 5. Check whether your own skill triggers (optional)
If this repository has Claude Code skills, the plugin can measure whether the model
reaches for one at the right moment.
**Export the skill location first** — the evaluated agent runs in a fresh sandbox
holding none of your files, so it is offered no skills unless the task says where
they live. Point at a **plugin root**: a directory holding a `skills/` subdirectory,
so the skill sits at `/skills//SKILL.md`. For
`.claude/skills/pdf-forms/SKILL.md` that root is `.claude`, not `.claude/skills` —
one level too deep loads nothing at all:
```bash
export SKILL_SOURCE_PATH="$(pwd)/.claude"
```
```
/coder-eval:check-skill pdf-forms
```
You get recall, precision and F1 over a labeled suite of requests the skill should
win plus distractors it should decline, gated by `suite_thresholds` on
`recall.yes` / `precision.yes`. Each row is a full agent run, so the skill states
the count and asks before starting.
Low recall has three possible causes, not one: truncation and listing-budget
eviction look identical to bad wording.
[The plugin page](https://coder-eval.com/docs/plugin#a-low-recall-result-has-three-causes-not-one)
covers telling them apart with `/doctor` and `/context`.
## If something goes wrong
| Symptom | Cause |
| --- | --- |
| No `/coder-eval:` commands after installing | Check `/plugin`; re-run the install |
| A skill offers to install the CLI, or Bash reports `command not found` | The CLI isn't installed or isn't on `PATH` — accept the offer, or install it yourself |
| `coder-eval run` matches nothing | Wrong directory — use the path `init` reported in step 2 |
| Every positive row in step 5 scores 0 | `SKILL_SOURCE_PATH` is unset, or points one level too deep (`.claude/skills` rather than the `.claude` plugin root), so the skill was never offered |
To update after the marketplace moves, `/plugin marketplace update coder-eval`; to
remove it, `/plugin uninstall`.
## Next steps
- `/coder-eval:ci` emits the CI workflow from [Tutorial 02](https://coder-eval.com/docs/tutorials/02-ci-pipeline) for
you — least-privilege by default, and it provides the agent runtime (Node plus
the Claude CLI) that the Action deliberately does not install.
- [Claude Code plugin](https://coder-eval.com/docs/plugin) — the reference page: every skill, what ships
in the plugin, and the activation-budget mechanics in full.
- [Writing a task](https://coder-eval.com/docs/tutorials/04-writing-a-task) — the same authoring loop by hand, worth
doing once to see what the skill is producing.
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) — the complete task schema.
---
# Coder Eval User Guide
The full command, configuration, and output reference. For a gentle introduction
start with the [tutorials](https://coder-eval.com/docs/tutorials); for the task-file schema see the
[Task Definition Guide](https://coder-eval.com/docs/task-definition-guide).
## Table of Contents
- [CLI Commands](#cli-commands)
- [API Routing & Benchmarking](#api-routing--benchmarking)
- [Output Structure](#output-structure)
- [Suite Thresholds & Classification Metrics](#suite-thresholds--classification-metrics)
- [Environment Variables](#environment-variables)
- [Troubleshooting](#troubleshooting)
## CLI Commands
### `coder-eval run` — execute evaluations
```bash
coder-eval run # all tasks (discovers tasks/ recursively)
coder-eval run tasks/hello_date.yaml # a single task
coder-eval run tasks/*.yaml --max-parallel 3 # multiple, 3 concurrent
coder-eval run tasks/hello_date.yaml --stream full # live LLM output
```
| Flag | Description |
| --- | --- |
| `--max-parallel, -j` | Concurrent tasks (default: 1) |
| `--preservation-mode` | Sandbox persistence: `NONE` / `MOVE_ON_WRITE` / `DIRECT_WRITE`. Default is driver-derived (docker → `DIRECT_WRITE`, else `MOVE_ON_WRITE`); explicit value always wins. |
| `--run-dir` | Custom run directory (default: timestamped in `runs/`) |
| `-D path=value` / `--set` | Override any resolved task-config field (`agent`/`run_limits`/`sandbox` roots), e.g. `-D run_limits.max_turns=30 -D agent.permission_mode=plan -D agent.sdk_options.effort=high`. Repeatable; schema-validated. This is the way to set permission mode, turn/timeout limits, token/USD budget caps, tools, plugins, and SDK options. |
| `--model, -m` | Shorthand alias for `-D agent.model=…` (e.g., `claude-sonnet-5`) |
| `--driver` | Shorthand alias for `-D sandbox.driver=…` (`tempdir` or `docker`) |
| `--type, -T` | Override agent type for all tasks (`claude-code`, `codex`, `antigravity`, `opencode`, or a plugin kind). |
| `--repeats` | Run each `(task, variant)` N times (≥1); overrides experiment/variant `repeats:`. See [Replicates](#replicates). |
| `--resume` | Resume an interrupted run: skip tasks already finalized in `--run-dir` and run the rest, folding prior results into `run.json`. Requires `--run-dir`. A task with *any* final status (incl. FAILED/ERROR) counts as finalized, so resume does **not** retry failures — delete a task's `task.json` to force a re-run. A config mismatch is warned, not refused. |
| `--sample N` | For dataset-backed tasks, run a fixed-seed random N-row sample (reproducible; cheap smoke test). See [Bring Your Own Dataset](https://coder-eval.com/docs/datasets). |
| `--sample-per-stratum N` | For dataset-backed tasks, keep up to N rows per stratum (`stratify_field`). Overridden by `--sample`. Nondeterministic unless `dataset.sample_seed` is set — see [Bring Your Own Dataset](https://coder-eval.com/docs/datasets). |
| `--include-skipped` | Also run tasks marked `skip: true` in their YAML (off by default so CI keeps excluding them). |
| `--exclude-tags` | Skip tasks matching any of these tags (comma-separated) |
| `--tags, -t` | Only run tasks matching any of these tags (comma-separated) |
| `--experiment, -e` | Experiment definition YAML for multi-variant comparison (default: `experiments/default.yaml`) |
| `--log-file` | Write logs to file |
| `--backend, -b` | API backend: `direct` or `bedrock` (default: from `API_BACKEND` env var) |
| `--stream, -s` | Stream LLM events to terminal: `full` or `minimal` (disables progress bar) |
| `--verbose, -v` | DEBUG-level logging |
**Run-time caps** — turns, wall-clock timeouts, and cumulative token / USD budgets — are not CLI
flags of their own. They live under `run_limits:` in the task YAML, or on the command line as
`-D run_limits.=` (e.g. `-D run_limits.max_usd=2.50`). The complete field reference is
in the [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide#run-limits).
### `coder-eval plan` — validate tasks
```bash
coder-eval plan # validate all tasks
coder-eval plan tasks/*.yaml # validate specific tasks
```
Checks task syntax, required CLI tools, API keys, and schema validity without executing.
| Flag | Description |
| --- | --- |
| `--experiment, -e` | Experiment definition YAML to resolve variants against (default: `experiments/default.yaml`). |
### `coder-eval evaluate` — test criteria without an agent
```bash
coder-eval evaluate tasks/hello_date.yaml ./my_solution # evaluate a directory
coder-eval evaluate tasks/hello_date.yaml ./my_solution --preserve # keep the sandbox
```
Runs a task's success criteria against a directory without an agent — useful for
testing criterion definitions, validating task configs, or scoring code that was
already written.
| Flag | Description |
| --- | --- |
| `--preserve / --no-preserve` | Preserve sandbox after evaluation (default: preserve) |
| `--run-dir` | Custom run directory (default: auto-generated timestamped dir in `runs/`). |
| `--verbose, -v` | DEBUG-level logging |
### `coder-eval report` — view results
```bash
coder-eval report runs/latest # view latest run (markdown to stdout)
coder-eval report runs/latest -o summary.md # export markdown to a file
coder-eval report runs/latest --format html # (re)render every task.json as task.html
```
The `run` command already writes reports during execution; `report` re-displays or
re-exports them later. For the on-disk layout and field-level schema of the JSON it
reads, see [Output Structure](#output-structure) and the
[Report Schema](https://coder-eval.com/docs/report-schema).
| Flag | Description |
| --- | --- |
| `--output, -o` | Write to a file instead of stdout (markdown). |
| `--format, -f` | `md` (default) or `html`. `html` re-renders each `task.json` under the run dir to a `task.html` beside it (or to `-o` when exactly one task is found). |
### `coder-eval aggregate` — rebuild `run.json` from task results
```bash
coder-eval aggregate runs/2026-06-22_14-32-27 # rebuild the summary in place
coder-eval aggregate runs/combined -o runs/combined # aggregate a merged dir
```
Re-derives the run-level `run.json` + `run.md` from the finalized `task.json` files
already on disk, using the same builder a live run uses. Use it when a run dir's
top-level summary is missing or stale — e.g. after recovering an interrupted run or
combining several run directories. It rebuilds the **run-level summary only**;
per-suite rollups (`suite.json`/`suite.md`) and experiment reports
(`experiment.json`/`experiment.md`) are *not* rebuilt, because the per-row
suite/variant grouping they need is not recoverable from `task.json` alone.
| Flag | Description |
| --- | --- |
| `--output, -o` | Write `run.json`/`run.md` into this directory instead of the run dir (e.g. a merged output dir). |
### Claude Code slash commands
Authoring and analysis commands ship in the [Claude Code plugin](https://coder-eval.com/docs/plugin), so they work
in **any** repository rather than only this one:
```
/plugin marketplace add UiPath/coder_eval
```
| Command | Description |
| --- | --- |
| `/coder-eval:task` | Create evaluation task YAML files from a natural language description. |
| `/coder-eval:analyze ` | Analyze evaluation runs and suggest improvements to tasks, config, and prompts. Works at task, variant, or run scope. |
See [Claude Code Plugin](https://coder-eval.com/docs/plugin) for the full set of six skills. The
`.claude/commands/` directory in this repository holds contributor-only tooling
(code review, planning) that is deliberately not shipped.
/ # Per-variant directory
│ │ ├── variant.md / variant.json # Variant aggregate report + data
│ │ └── /
│ │ └── 00/ # Replicate index — one dir per replicate
│ │ ├── task.json # Evaluation result
│ │ ├── task.log # Execution log
│ │ └── artifacts/ # Preserved sandbox (unless --preservation-mode NONE)
│ └── ...
└── latest -> 2026-02-26_14-30-00/ # Symlink to most recent run
```
### Replicates
Run the same (task, variant) N times via `repeats:` in an experiment YAML or
`--repeats N` on the CLI. Per-replicate results live in separate `NN/` directories;
reports aggregate them with bootstrap confidence intervals and (for 2-variant
experiments) a paired mean-difference test. Defaults to 1 (no repetition).
For a field-level reference to `run.json`, `variant.json`, `task.json`, and the
suite/experiment rollups, see the [Report Schema](https://coder-eval.com/docs/report-schema).
` / `recall.` / `f1.`. This makes
Coder Eval usable as a SkillsBench-style activation harness. Full details and the
suite-rollup outputs live in [A/B Experiments](https://coder-eval.com/docs/ab-experiments#measuring-the-difference)
and the [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide).
## Environment Variables
Set these in `.env` (copy from `.env.example`).
| Variable | Required | Description |
| --- | --- | --- |
| `ANTHROPIC_API_KEY` | Yes (for Claude Code) | Anthropic API key |
| `API_BACKEND` | No | API backend: `direct` or `bedrock` (default: `direct`). Overridden by `--backend`. |
| `AWS_BEARER_TOKEN_BEDROCK` | For Bedrock | AWS Bedrock bearer token for authentication |
| `AWS_REGION` | For Bedrock | AWS region for Bedrock endpoint (e.g., `eu-north-1`) |
| `BEDROCK_MODEL` | No | Cross-region Bedrock model ID (e.g., `eu.anthropic.claude-sonnet-5`) |
| `BEDROCK_SMALL_MODEL` | No | Cross-region Bedrock small/fast model ID |
| `CODEX_API_KEY` / `CODEX_BASE_URL` / `CODEX_MODEL` / `CODEX_API_VERSION` | For Codex | Codex agent auth & endpoint routing — see [Codex Agent Guide](https://coder-eval.com/docs/agents/codex#endpoint-routing). |
| `GEMINI_API_KEY` / `ANTIGRAVITY_MODEL` | For Antigravity | Antigravity (Gemini) agent auth & model — see [Antigravity Agent Guide](https://coder-eval.com/docs/agents/antigravity#setup). |
| `UIPATH_PLUGIN_MARKETPLACE_DIR` | No | Conventional base directory for local plugins. Not special-cased by the framework: **any** `$VAR` / `${VAR}` referenced in a plugin `path` is expanded from the environment, so a plugin path like `$UIPATH_PLUGIN_MARKETPLACE_DIR/my-plugin` resolves against this variable. (An undefined variable in a plugin path logs a warning.) |
| `PLUGIN_TOOLS_DIR` | No | A *separate* mechanism from the above: the canonical `node_modules/@uipath` directory used to pin UiPath CLI plugin discovery (not path substitution). When unset, the sandbox auto-derives it from the resolved `uip` binary. |
| `CODER_EVAL_REMEDIATE_HOME_PLUGINS` | No | **DESTRUCTIVE.** Truthy deletes `$HOME/node_modules/@uipath` at sandbox setup to clear sibling-task pollution on dedicated eval hosts. Off by default; do **not** enable on developer workstations. |
| `LOG_LEVEL` | No | Logging level (default: INFO) |
| `LOG_TO_FILE` | No | Enable file logging (default: false) |
| `TELEMETRY_ENABLED` | No | Anonymous usage telemetry, **on by default**. Set `false` to disable entirely — see [Usage Telemetry](#usage-telemetry). |
| `TELEMETRY_CONNECTION_STRING` | No | Route telemetry to your own App Insights resource instead of the shared default (aliases: `APPLICATIONINSIGHTS_CONNECTION_STRING`, `UIPATH_AI_CONNECTION_STRING`) |
| `TELEMETRY_SOURCE` | No | Origin stamp emitted as the `Source` dimension (default: `coder-eval`) |
### Usage Telemetry
`coder-eval` collects **anonymous usage telemetry** (command names, outcomes, counts,
durations, an anonymous per-install id, and platform info) to help improve the tool.
It **never** captures prompts, file contents, or repo paths. Telemetry is **on by
default** and the first run prints a one-time notice to stderr disclosing this.
- **Disable it entirely:** set `TELEMETRY_ENABLED=false` (in `.env` or the environment).
- **Send it to your own resource:** set `TELEMETRY_CONNECTION_STRING` to your Azure
Application Insights connection string.
## Troubleshooting
| Problem | Solution |
| --- | --- |
| `ANTHROPIC_API_KEY is required` | Create `.env` from `.env.example` and add your key |
| `claude command not found` | `brew install claude` |
| `uv command not found` | `brew install uv` or `pip install uv` |
| Tests failing | `source .venv/bin/activate && uv pip install -e ".[dev]"` |
| Pre-commit hooks failing | `pre-commit autoupdate && pre-commit run --all-files` |
---
# Task Definition Guide
Complete reference for defining evaluation tasks in Coder Eval.
## Table of Contents
- [Task YAML Structure](#task-yaml-structure)
- [dataset](#dataset)
- [skip](#skip)
- [Agent Configuration](#agent-configuration)
- [Run Limits](#run-limits)
- [Sandbox Configuration](#sandbox-configuration)
- [Recording CLI Invocations](#recording-cli-invocations)
- [Template Sources](#template-sources)
- [Success Criteria](#success-criteria)
- [Continuous Scoring](#continuous-scoring)
- [Glob patterns in path](#glob-patterns-in-path)
- [file_exists](#file_exists)
- [file_contains](#file_contains)
- [file_check](#file_check)
- [json_check](#json_check)
- [run_command](#run_command)
- [file_matches_regex](#file_matches_regex)
- [reference_comparison](#reference_comparison)
- [command_executed](#command_executed)
- [cli_called](#cli_called)
- [uipath_eval](#uipath_eval)
- [llm_judge](#llm_judge)
- [agent_judge](#agent_judge)
- [skill_triggered](#skill_triggered)
- [Checker Context](#checker-context)
- [Reference Solutions](#reference-solutions)
- [Pre-Run Commands](#pre-run-commands)
- [Post-Run Commands](#post-run-commands)
- [Simulation (Multi-Turn User Dialog)](#simulation-multi-turn-user-dialog)
- [Command Telemetry](#command-telemetry)
- [Complete Example](#complete-example)
## Task YAML Structure
Every task is a YAML file with this top-level structure:
```yaml
task_id: "my_task" # Unique identifier (required)
description: "What this task tests" # Human-readable description (required)
initial_prompt: "Instructions..." # Prompt sent to the agent (required)
tags: [smoke, golden, pure-python] # Optional tags for filtering (kebab-case)
skip: false # Optional: quarantine this task (see below)
agent: { ... } # Agent configuration (optional, resolved from experiment)
sandbox: { ... } # Sandbox configuration (optional, defaults to tempdir)
run_limits: { ... } # Optional run-time caps (turns, wall-clock, tokens, USD)
success_criteria: [ ... ] # List of criteria (required, at least 1)
reference: { ... } # Optional reference solution (a directory; never readable by the agent)
pre_run: [ ... ] # Optional pre-run commands (before agent starts)
post_run: [ ... ] # Optional post-run commands
dataset: { ... } # Optional dataset fan-out (one task -> N row-tasks)
checker_context: { ... } # Optional: backend/model for the judge side (llm_judge/agent_judge)
```
### `dataset`
An optional `dataset:` block fans this single task out into **one sub-task per row**. Each row-task
gets its own sandbox, run directory, and `task.json`; its `task_id` becomes `/`.
Row values substitute into `initial_prompt` and into the string leaves of `success_criteria` via
`${row.}`. Expansion happens at load time, **before** experiment-variant resolution, so a
variant can never override the dataset.
```yaml
dataset:
rows: # inline rows — mutually exclusive with `paths`
- id: alpha
expected: "alpha"
# paths: ["datasets/rows.jsonl"] # or JSONL files, relative to this task YAML
id_field: "id" # which row field is the row identifier
sample_per_stratum: 5 # optional: keep up to N rows per stratum
stratify_field: "expected_skill" # which row field defines the stratum
sample_seed: 1234 # optional: pin the stratified draw
```
| Field | Default | Description |
|-------|---------|-------------|
| `rows` | `null` | Inline list of row dicts. Mutually exclusive with `paths`; exactly one is required. |
| `paths` | `null` | JSONL file paths **relative to the task YAML**, concatenated in declared order. |
| `id_field` | `"id"` | Row field used as the row identifier. Must be present, unique, and match `^[A-Za-z0-9_][A-Za-z0-9_.\-]*$` (it becomes a directory name). |
| `sample_per_stratum` | `null` | Stratified random sample: keep up to N rows per stratum. Overridden by CLI `--sample`. |
| `stratify_field` | `"expected_skill"` | Row field whose value defines the stratum for `sample_per_stratum`. |
| `sample_seed` | `null` | Seed for the stratified draw. Unset means the sample is **re-drawn every run**; set an integer to pin it. CLI `--sample` is separately fixed-seed and always reproducible. |
Full guide — row sources, substitution rules, sampling precedence, suite-level scoring, and worked
examples: **[Bring Your Own Dataset](https://coder-eval.com/docs/datasets)**.
### `skip`
`skip: true` quarantines a task. The runner records it in `RunSummary.skipped_tasks` at resolution
time and it **never reaches the orchestrator** — no dataset fan-out, no variant resolution, no
sandbox, no API call. Use it to park a task that is blocked on something outside your control
(an upstream bug, a missing service) without deleting the YAML and losing its history.
```yaml
task_id: "codex_disallowed_tools_test"
# Blocked: the Codex SDK doesn't enforce disallowed_tools via config. Re-enable
# once upstream ships the fix.
skip: true
```
Pair it with a comment naming the blocker — a ticket link, an upstream issue — so the next reader
knows what has to change before it can come back. Run quarantined tasks on demand with
`coder-eval run --include-skipped`; CI leaves the flag off, so they stay excluded there.
## Tags
The `tags` list categorizes tasks for selective execution. Each tag is lowercase kebab-case and may
optionally be namespaced as `key:value` where both sides are kebab-case.
```yaml
tags: [smoke, golden, uipath-python, lifecycle:generate, connector:google-tasks]
```
Namespaced tags let downstream tools slice on a single dimension (e.g. queries
filtering on `connector:*`). Bare tags continue to work with existing
`--tags` filters.
**Well-known tags:**
| Tag | Purpose |
|-----|---------|
| `smoke` | Quick sanity check, should always pass |
| `golden` | High-confidence reference tasks for framework validation |
| `basic` | Simple tasks testing core functionality |
| `integration` | Requires external services or network |
| `example` | Demonstration/tutorial tasks, not for CI |
| `uipath-python` | Uses UiPath Python SDK |
| `uipath-langchain` | Uses UiPath + LangChain integration |
| `pure-python` | No external SDK dependencies |
| `template` | Uses template sources |
| `network` | Requires network access |
**CLI filtering:**
```bash
coder-eval run tasks/*.yaml --tags smoke-pass # Smoke tasks expected to succeed
coder-eval run tasks/*.yaml --tags smoke-fail # Smoke tasks expected to fail (failure-detection sentinels)
coder-eval run tasks/*.yaml --tags smoke # Umbrella tag: all smoke tasks (pass + fail buckets)
coder-eval run tasks/*.yaml --tags golden,basic # Run golden OR basic tasks
coder-eval run tasks/*.yaml --exclude-tags example # Skip example tasks
```
## Agent Configuration
Run-time caps (turns, wall-clock, tokens, USD) are **not** part of this block — they live under
[`run_limits`](#run-limits).
```yaml
agent:
type: "claude-code" # Agent type — optional if supplied via experiment / --type
permission_mode: "acceptEdits" # Permission mode (see below)
allowed_tools: # Tools the agent can use
- "Read"
- "Write"
- "Bash"
model: "claude-sonnet-5" # Optional: specific model
sdk_options: # Optional: Claude Code SDK pass-through
effort: high # any non-framework-managed ClaudeAgentOptions field
```
**`sdk_options`** is a typed pass-through dict for Claude Code SDK
`ClaudeAgentOptions` fields that Coder Eval doesn't own directly. Keys are
validated against the SDK's dataclass at YAML load; framework-managed keys
(`model`, `allowed_tools`, `permission_mode`, `hooks`, `mcp_servers`, …)
are rejected. Deep-merged across the 5-layer config chain. Override via
CLI with the repeatable `-D agent.sdk_options.KEY=VALUE`.
**Requires `type: "claude-code"`** to function; on other agent types it raises
an error.
**Permission Modes:**
- `default` — Default permission handling
- `acceptEdits` — Auto-accept file edits (recommended for evaluations)
- `plan` — Agent proposes changes, waits for approval
- `bypassPermissions` — No permission checks (use with caution)
> **Codex note:** `permission_mode` confines the **`claude-code`** agent only. The **`codex`** agent always runs full-access regardless of the mode — its in-process OS sandbox is redundant given Coder Eval's docker/tempdir isolation and unusable on our CI hosts (and on Windows). Run adversarial or untrusted Codex evals under the **docker driver**, which is the OS-level write boundary; the tempdir/host driver is a working directory, not a confinement boundary.
**Agent Types:**
- `claude-code` (default) — Claude Code SDK agent. Supports `sdk_options`, `claude_settings`, and all permission modes.
- `codex` — OpenAI Codex agent (requires `[codex]` extra; set `CODEX_API_KEY` and optional `CODEX_BASE_URL` environment variables).
- `none` — No-op agent: no coding agent runs and no model API call is made. See [No-op / System Tasks](#no-op--system-tasks-type-none) below.
); <= N turn(s) avoided …` |
| `task.html` | header badge `stopped early ()` + `advisory — not gated` markers |
| Telemetry | `EarlyStopped` / `EarlyStopReason` dimensions on `CoderEval.Task.End` |
## Sandbox Configuration
The `sandbox` block is optional. When omitted, it defaults to `driver: "tempdir"` with standard Python environment.
```yaml
sandbox:
driver: "tempdir" # Sandbox type ("tempdir" or "docker"); default: "tempdir"
python: # Python env config (null to skip venv)
env_packages: # Packages to install in sandbox venv
- pytest
- pylint>=3.0
template_sources: [ ... ] # Optional: preset files (see below)
ignore_patterns: # Optional: overrides for template-copy filtering
- "!dist" # `!`-prefix un-ignores a default pattern
- "!node_modules"
- "*.bak" # bare entry adds an extra pattern
limits: # Optional: resource limits
timeout: 300 # Enforced via subprocess timeout (both drivers)
max_memory_mb: 512 # driver:docker -> `--memory`; ignored under tempdir
max_cpus: 2 # driver:docker -> `--cpus`; ignored under tempdir
max_pids: 512 # driver:docker -> `--pids-limit`; ignored under tempdir
max_disk_mb: 1024 # NOT enforced (reserved: no portable docker knob)
```
Under `driver: tempdir` only `timeout` is enforced — the agent can consume
arbitrary host memory, CPU, and PIDs. Use `driver: docker` when you need the
container limits above to actually bind.
### Recording CLI Invocations
`record_cli` shadows executables with generated recording shims, so a task can assert on **what the agent actually ran** without hand-writing a mock:
```yaml
sandbox:
record_cli:
- tool: uip
exit_code: 1
stderr: "uip: not connected to a tenant in this sandbox.\n"
- tool: curl # so a disobedient agent cannot reach the network
```
Each shim records the invocation, writes the configured `stdout`/`stderr`, and exits with `exit_code` — which **defaults to 1**, so a bare `- tool: curl` makes the shadowed tool look like it failed. Set `exit_code: 0` when the agent should see success. Values outside 0-255 are rejected, since `sys.exit` truncates mod 256.
`tool` must be a bare executable name, and a small reserved set (`python`, `python3`, `env`, `sh`, `bash`, `node`, `git`, `uv`, `cmd`) is refused: shadowing those breaks the harness itself rather than the tool under test — the shim's own interpreter, or the shell that `run_command` criteria use.
The sandbox writes the shims into `cli_mocks/` and PATH-prepends that directory, then appends one JSON record per invocation to `cli_mocks/calls.jsonl` — the log [`cli_called`](#cli_called) reads by default. Nothing else to wire: no `mock_path_dirs`, no `template_sources`, no `log:` on the criterion.
Notes:
- **A `.cmd` twin** is generated beside each shim so a bare `uip` also resolves through Windows PATHEXT lookup.
- **The log is seeded empty**, so a correct run that legitimately calls nothing still satisfies a `max_count: 0` guard — while a *missing* log (mock never ran, or wrote elsewhere) still fails.
- **stdin is never read** by the shim: reading it would block whenever the sandbox leaves stdin attached to an open pipe, hanging the task.
- **Collisions are rejected.** If a `mock_path_dirs` entry already provides an executable of the same name, setup raises rather than letting directory order decide which one runs.
- **It stubs a tool; it does not proxy one, and it does not serve per-invocation responses.** Recording a *real* executable on the way through, or returning different output per invocation, stays a hand-written mock under `mock_path_dirs` — both depend on state the harness cannot guarantee (the tool being installed, PATH order, live credentials, a fixture set).
## Template Sources
Tasks can start with preset files instead of an empty sandbox. Multiple sources are applied sequentially (last wins for conflicts).
### Git Repository
```yaml
template_sources:
- type: "repo"
url: "https://github.com/user/repo.git"
commit: "abc123" # Optional: pin to specific commit
```
**Note:** If using `repo` source, it must be first in the list.
### Template Directory
Copy a local directory into the sandbox:
```yaml
template_sources:
- type: "template_dir"
path: "../templates/python-starter" # Relative to task YAML file
mount_point: "." # Optional: subdir inside sandbox to copy into (default ".")
```
The framework automatically ignores `.venv`, `.git`, `__pycache__`, `node_modules`, `dist`, `build`, and other common build/cache artifacts (full list: `coder_eval/resources/default_ignore_patterns.yaml`).
Override the defaults via `sandbox.ignore_patterns` (or `agent.ignore_patterns` for judge-style sub-agents). Each entry is either:
- A bare pattern (e.g. `*.bak`) — added on top of the defaults.
- A `!`-prefixed pattern (gitignore-style negation, e.g. `!dist`) — removes that pattern from the defaults so the directory survives the template copy. Useful for tasks that ship a vendored toolchain under `dist/` or `node_modules/`. Surrounding whitespace is stripped; bare `!` and empty entries raise `ValueError` at YAML load.
`mount_point` controls where inside the sandbox the template contents land. With `mount_point: "."` (default) files are copied to the sandbox root. With `mount_point: "c"` everything from the source directory ends up under `/c/`. The mount point must be a relative path that stays within the sandbox.
### Inline Starter Files
Define files directly in YAML (ideal for 1–3 files):
```yaml
template_sources:
- type: "starter_files"
files:
- path: "README.md"
content: |
# My Project
Instructions for the agent...
- path: "src/main.py"
content: |
def main():
pass # TODO: Implement
```
### Combining Sources
```yaml
template_sources:
- type: "template_dir"
path: "../templates/python-base"
- type: "starter_files"
files:
- path: "requirements.txt"
content: "pytest>=8.0\npylint>=3.0"
```
### Template Sources in Experiment Variants
Experiment variants can add `template_sources` that are **appended after** the task's own template sources. This is useful for injecting variant-specific context (like a `CLAUDE.md` hint file) without duplicating the base task or creating separate template directories.
```yaml
# experiments/my-experiment.yaml
variants:
- variant_id: baseline
agent:
model: "claude-sonnet-5"
- variant_id: with-context-hint
agent:
model: "claude-sonnet-5"
template_sources:
- type: "starter_files"
files:
- path: "CLAUDE.md"
content: |
The UiPath flows are in folder ID abc-123-def.
Use this folder when interacting with the Orchestrator API.
```
In this example, the `with-context-hint` variant gets the same sandbox as `baseline`, plus a `CLAUDE.md` file written into the sandbox root. Since variant template sources are appended last, they can also overwrite files from earlier sources (last-wins).
This pattern is especially useful for A/B testing whether additional context improves agent performance.
## Success Criteria
Every task needs at least one success criterion. The framework supports 14 criterion types.
### Continuous Scoring
All criteria share these fields:
| Field | Default | Description |
|-------|---------|-------------|
| `description` | — | Human-readable description (required) |
| `weight` | 1.0 | Relative importance for weighted score. `0` = **informational**: excluded from both the score and the pass/fail gate |
| `pass_threshold` | 0.9 | Minimum score (0.0–1.0) to pass |
| `stop_early` | `null` | **Only on live-observable criteria** (`skill_triggered`, `command_executed`). Presence arms the criterion for early stop (no run-level switch needed): an effective fail may end the run (weighted ceiling rule, recall deferral). Keys: `on_pass: stop\|continue` (default `continue`), `decide_within: N` (timeout → effective fail, reported as `decision_budget_exceeded`). Inert triggers by design on instances that can't decide their polarity (dataset fan-out support). See [`stop_early`](#stop_early-opt-in-early-stop). |
**Scoring types:**
- **Binary** (1.0 or 0.0): `file_exists`, `run_command`, `file_matches_regex`, `cli_called`, `classification_match`, `skill_triggered`
- **Fractional** (0.0–1.0): `file_contains`, `file_check`, `json_check`, `command_executed`, `uipath_eval`
- **Continuous** (0.0–1.0): `reference_comparison`, `commands_efficiency`, `llm_judge`, `agent_judge`
**Task success:** all *gating* criteria must score >= their `pass_threshold`. A
criterion with `weight: 0` is informational — it is still checked, stored, and
rendered in reports, but it neither contributes to the score nor fails the task.
(A `weight: 0` criterion may not set a `stop_early` block or `suite_thresholds`: arming a
non-gating criterion for the early-stop or suite gate would let an
"informational" check flip a run to failure.)
Every surface labels it as such rather than as a failure: the terminal shows `○`
instead of `✓`/`✗`, the HTML report tags the row "informational — not gated" and
excludes it from the *n*/*m* passed header, the evalboard renders an `INFO` pill,
and a below-threshold informational criterion is never sampled as the reason a
suite row failed. The persisted `CriterionResult.gating` field carries this to
every consumer, so no reader needs the original criterion to know whether a low
score mattered.
**Weighted score:** `weighted_score = sum(score * weight) / sum(weight)` — calculated regardless for quality assessment.
### Glob patterns in `path`
Every sandbox-relative path field accepts a glob — `path` on `file_exists`, `file_contains`, `file_matches_regex`, `file_check`, `json_check` and `classification_match`, `json_schema` on `json_check`, and `agent_file` on `reference_comparison`. Use one when the prompt does not pin where the file lands — a scaffolding tool that creates a wrapper directory the agent names itself, for example.
```yaml
- type: "file_contains"
path: "**/*.flow" # matches any depth under the sandbox root
includes: ['"core.logic.decision"']
description: "flow wires a Decision node"
```
Rules:
- **A path that exists is never treated as a pattern.** A literal `path` behaves exactly as before, including one containing `*`, `?`, or `[` — a real file named `report[2024].json` is graded as itself, not as a character class that would match `report2.json`. Globbing only kicks in when the literal path does not exist.
- **Glob matches skip ignored directories.** Expansion runs over the live sandbox root, which also holds harness-created content the agent never wrote (`.venv` for any task with a `python:` block, `node_modules`, `dist`, `build`, `__pycache__`, …), so matches are filtered through the same [`ignore_patterns`](#sandbox-configuration) set used for template copying. A segment your pattern names *literally* is an opt-in and survives, so `dist/**/*.js` still grades `dist`; to un-ignore a directory a wildcard has to discover, use the negation escape hatch — `ignore_patterns: ["!dist"]`.
- Matches are sorted, and directories are skipped.
- `file_exists` passes when the glob matches **at least one** file.
- Content checks require the glob to match **exactly one** file. An ambiguous glob scores 0.0 and reports the matches (first 10, then `+N more`) rather than silently grading one of them — narrow the pattern.
- When a glob resolves, the file that was actually graded is echoed in the criterion's `details` as `resolved: `.
Prefer a glob over a hardcoded path whose leading directory the task prompt never specifies: a correct artifact in an unexpected directory otherwise scores 0.0 on the path alone. Glob away only the segment the prompt leaves free, though — if the free part is an unknown wrapper directory, `**/.flow` stays unique where a blanket `**/*.flow` turns exactly-one into a hard 0.0 the moment a second flow file exists.
> **Dataset note:** `${row.}` substitution runs over `success_criteria` string leaves, so a row value containing `*`, `?`, or `[` lands inside `path`. Literal-first resolution means such a path still grades the real file when it exists; it falls back to glob expansion only when it does not.
### `file_exists`
Checks if a file exists. **Binary scoring.**
```yaml
- type: "file_exists"
path: "app.py"
description: "app.py must be created"
```
### `file_contains`
Checks if a file contains (or doesn't contain) specific strings. **Fractional scoring:** average of (includes matched / total) and (excludes absent / total).
```yaml
- type: "file_contains"
path: "app.py"
includes: # Strings that must be present
- "Hello"
- "import datetime"
excludes: # Optional: strings that must NOT be present
- "TODO"
- "FIXME"
description: "File must contain required strings"
weight: 1.0
pass_threshold: 0.9
```
### `file_check`
Unified file check that combines existence, string includes/excludes, and regex patterns into a single criterion. **Fractional scoring:** average of active sub-check scores. Replaces common `file_exists` + `file_contains` + `file_matches_regex` combinations.
File existence is implicit — if the file doesn't exist, score is 0.0. If no sub-checks are specified, it behaves as a pure existence check.
```yaml
# Full example with all features
- type: "file_check"
path: "main.py"
includes: # Strings that must be present
- "from uipath import UiPath"
- "def main"
excludes: # Strings that must NOT be present
- "import os"
patterns: # Regex patterns to check
- pattern: "def main\\(.*\\):"
must_match: true # true = must match (default), false = must NOT match
flags: 0 # Regex flags (default: 0)
description: "main.py exists with correct imports and structure"
weight: 1.0
pass_threshold: 0.9
# Minimal: existence-only check (equivalent to file_exists)
- type: "file_check"
path: "app.py"
description: "app.py must be created"
```
| Field | Default | Description |
|-------|---------|-------------|
| `path` | *required* | Path to the file (relative to sandbox root) |
| `includes` | `[]` | Strings that must be present |
| `excludes` | `[]` | Strings that must NOT be present |
| `patterns` | `[]` | Regex pattern objects (`pattern`, `must_match`, `flags`) |
**Scoring:** Only active categories (non-empty lists) contribute to the average. For example, specifying only `includes` means the score equals the includes score alone — it is not inflated by absent categories.
### `json_check`
Validates a JSON file: existence, parse-ability, JSON Schema conformance, and JMESPath assertions. **Fractional scoring.**
File existence and valid JSON are implicit — if the file is missing or unparseable, score is 0.0. If no sub-checks are specified, it's a pure "is valid JSON" check.
```yaml
# Minimal: just validate JSON syntax
- type: "json_check"
path: "data.json"
description: "data.json is valid JSON"
# Schema validation only
- type: "json_check"
path: "output.json"
json_schema: "schemas/output_schema.json"
description: "Output conforms to expected schema"
# JMESPath assertions only
- type: "json_check"
path: "report.json"
assertions:
- expression: "status"
expected: "success"
- expression: "length(results)"
operator: "gte"
expected: 1
- expression: "metadata.version"
operator: "regex"
expected: "^\\d+\\.\\d+\\.\\d+$"
description: "Report has correct structure and values"
# Both schema + assertions
- type: "json_check"
path: "result.json"
json_schema: "schemas/result_schema.json"
assertions:
- expression: "status"
expected: "completed"
- expression: "items[?active].name"
operator: "exists"
description: "Result is valid and has expected values"
```
| Field | Default | Description |
|-------|---------|-------------|
| `path` | *required* | Path to the JSON file (relative to sandbox root) |
| `json_schema` | `null` | Path to a JSON Schema file (relative to sandbox root) |
| `assertions` | `[]` | List of JMESPath assertions (see below) |
**Assertion fields:**
| Field | Default | Description |
|-------|---------|-------------|
| `expression` | *required* | JMESPath expression to evaluate |
| `operator` | `"equals"` | One of: `equals`, `not_equals`, `contains`, `gt`, `gte`, `lt`, `lte`, `type`, `regex`, `exists` |
| `expected` | `null` | Expected value (required for all operators except `exists`) |
**Scoring:** Only active categories (schema, assertions) contribute. Schema scoring is binary (1.0/0.0). Assertions score = passed / total. When both are used, final score = average of the two category scores.
### `run_command`
Runs a command and checks the exit code, with optional stdout matching. **Binary scoring.**
```yaml
# Simple exit-code check
- type: "run_command"
command: "python app.py"
timeout: 30 # Timeout in seconds (default: 30)
expected_exit_code: 0 # Expected exit code (default: 0)
description: "Script must run successfully"
weight: 2.0
# With stdout matching (replaces former program_stdout_equals)
- type: "run_command"
command: "python hello.py"
expected_stdout: "Hello, World!" # Optional: check stdout content
stdout_match: "exact" # "exact" (default), "contains", or "regex"
description: "Script must output the correct text"
```
| Field | Default | Description |
|-------|---------|-------------|
| `command` | *required* | Command to execute |
| `timeout` | 30 | Timeout in seconds |
| `expected_exit_code` | 0 | Expected exit code |
| `expected_stdout` | `null` | When set, stdout is also checked |
| `stdout_match` | `"exact"` | Match mode: `exact` (stripped), `contains` (substring), `regex` (pattern) |
| `score_from_stdout` | `false` | Read a float score (0.0–1.0) from the first stdout line (remaining lines become details); a non-zero exit code or a parse failure scores 0.0. Mutually exclusive with `expected_stdout`. |
### `file_matches_regex`
Checks if file content matches a regular expression pattern. **Binary scoring.**
```yaml
- type: "file_matches_regex"
path: "config.py"
pattern: "^API_KEY = ['\"]\\w+['\"]$"
must_match: true # true = must match; false = must NOT match
flags: 0 # Regex flags (re.IGNORECASE=2, re.MULTILINE=8)
description: "Config must define API_KEY"
```
### `reference_comparison`
Compares agent's code with one file of the reference solution using similarity scoring. **Continuous scoring.** Requires a `reference` block at the task level (a task that declares this criterion without one is rejected at load time).
```yaml
- type: "reference_comparison"
agent_file: "solution.py" # Agent's output file (relative to sandbox)
reference_file: "solution.py" # File inside reference.directory to compare against
comparison_method: "ast" # Method: "ast", "token", or "complexity"
similarity_threshold: 0.8 # Minimum similarity (0.0-1.0)
description: "Solution must match reference structure"
weight: 2.0
```
| Field | Default | Description |
|-------|---------|-------------|
| `agent_file` | *required* | Path to the agent's generated file (relative to the sandbox root). |
| `reference_file` | *required* | Path to the reference file to compare against, relative to `reference.directory` (i.e. `$REFERENCE_DIR/`). Must stay inside that directory — `../` is rejected. |
| `comparison_method` | `"ast"` | `ast` (structure), `token` (text), or `complexity` (metrics). |
| `similarity_threshold` | 0.8 | Minimum similarity score to pass (0.0–1.0). |
**Comparison methods:**
- `ast` — Abstract Syntax Tree similarity (structure-based)
- `token` — Token-based similarity (implementation details)
- `complexity` — Cyclomatic complexity comparison
### `command_executed`
Checks whether the agent executed specific tools/commands during evaluation. Inspects `CommandTelemetry` records from agent turns. **Fractional scoring:** matched commands / `min_count`.
```yaml
- type: "command_executed"
tool_name: "Bash" # Tool name filter (null = any tool)
command_pattern: "curl.*wttr\\.in" # Regex to match command parameters (null = any)
min_count: 1 # Minimum matching commands required (default: 1)
require_success: true # Only count successful commands (default: false)
description: "Agent must use curl to fetch weather"
```
| Field | Default | Description |
|-------|---------|-------------|
| `tool_name` | `null` | Tool-name filter (e.g. `Bash`); `null` counts any tool. |
| `command_pattern` | `null` | Regex to match the command; `null` matches any command. Matched with shell normalization (see below). |
| `min_count` | 1 | Minimum matching commands required. `0` permits zero matches — combine with `max_count: 0` to assert a command must **NOT** run. |
| `max_count` | `null` | Optional inclusive upper bound. When set, the criterion passes iff `min_count <= matches <= max_count`. |
| `require_success` | `false` | Only count commands that completed successfully. |
| `exclude_pattern` | `null` | Regex that must NOT match; a command matching both `command_pattern` and `exclude_pattern` is skipped. Also matched with shell normalization (see below). |
**Shell normalization.** For a Bash command, both `command_pattern` and `exclude_pattern` are matched against the raw command text **and** its shell-normalized form — the `bash`/`sh`/`zsh -lc "..."` wrapper stripped and shell quoting resolved with `shlex` — and a hit on *either* form counts. So a pattern like `curated_channels` matches whether the agent wrote the argument bare, `'single'`-quoted, `"double"`-quoted, or `\"escaped\"`; you do **not** hand-encode shell quoting. Because the same haystacks also feed `exclude_pattern` and the `max_count` gate, normalization is **not** purely additive: a quote-obfuscated call can now be caught by an exclusion or a `max_count: 0` gate that the raw text alone would have missed — and, conversely, an unedited `exclude_pattern` may now exclude a call it previously let through. Cross-repo suites that hand-encoded quote tolerance in their patterns should re-baseline.
**Codex limitation.** Codex agents map `Read`, `Grep`, and `Glob` tools to `shell` commands (they execute via bash), so `tool_name: "Read"` on Codex returns no matches. Use `tool_name: "Bash"` or `tool_name: null` (any tool) for Codex-compatible checks. This criterion works correctly on Claude Code agents, which emit separate `Read`/`Grep`/`Glob` telemetry.
### `cli_called`
Checks whether a CLI invocation matching a **structured** pattern was recorded, by reading a JSON Lines invocation log the sandbox produced. **Binary scoring.**
Use this instead of `command_executed` or `file_matches_regex` when a test shadows a CLI with a recording mock and needs to assert on *what was actually executed*, field by field.
```yaml
- type: "cli_called"
description: "Switched the project to the capable model"
log: "mocks/calls.jsonl" # Invocation log; omit it to use the record_cli default
verb: "ixp projects configure-model" # Ordered prefix of the non-flag arguments
positional: ["my_invoices-ixp"] # Non-flag arguments following the verb, in order
flags:
model: "gemini_2_5_pro" # Bare scalar == {equals: ...}
tool: "uip" # Optional: match only records with this tool
min_count: 1 # Minimum matching invocations (default: 1)
max_count: null # Maximum; null = unbounded, 0 = forbidden
ignore_flags: ["output"] # Flags dropped before matching (default: ["output"])
```
**One operation, several verbs.** Use `verb_any_of` instead of `verb` (mutually exclusive); it matches if any entry does. Each entry is a *complete* verb in the form `verb` takes — not one token of a chain:
```yaml
- type: "cli_called"
description: "Read the project through the CLI"
verb_any_of: ["ixp projects list", "ixp projects get"]
```
Do **not** shorten the verb instead. `verb: "ixp projects"` matches all of its subcommands, so a positive assertion that the agent *read* a project is equally satisfied by `ixp projects delete`. Two entries are rejected when one prefixes the other, since the shorter already accepts everything the longer does.
**The argument tail stays open.** `positional` is a prefix too, so `verb: "ixp projects list"` with `positional: ["proj-1"]` also matches `ixp projects list proj-1 dummy`. To require a specific tail, name every argument in it. `positional: []` is rejected — it would assert nothing.
**Declare value-bearing flags when you use `positional`.** An undeclared flag is treated as a switch, so its value stays among the non-flag arguments and shifts the ones you named. `get proj-1 --folder Finance` matches `positional: ["proj-1"]`, but `get --folder Finance proj-1` does **not** — `Finance` takes the first slot. Add `folder` to `value_flags` (or name it in `flags`) to fix it. Resolving the ambiguity this way is deliberate: guessing that an unknown flag consumes the next token let `--yes proj-1` bind `yes=proj-1` and swallow the project name, which made a `max_count: 0` delete guard pass on the delete it forbade.
`log` defaults to `cli_mocks/calls.jsonl`, where [`sandbox.record_cli`](#recording-cli-invocations) writes — so a task using generated recorders never sets it. Point it elsewhere only when supplying your own mock.
**Log format.** One JSON object per line. Only `argv` is required; `tool` lets one log serve several shadowed executables, and `exit`/`ts` are recorded for reporting rather than matched. Unknown keys are ignored, so a mock may record more.
```json
{"ts": 1785416844.987, "tool": "uip", "argv": ["ixp", "projects", "get", "proj-1"], "exit": 1}
```
**Flag predicates.** Each entry under `flags:` takes **exactly one** of:
| Predicate | Matches when the flag value… |
|-----------|------------------------------|
| `equals` | equals the string exactly (the bare-scalar shorthand) |
| `contains` | contains the substring |
| `matches_regex` | matches the regex — scoped to one value, not the whole line |
| `any_of` | equals one of the listed strings |
| `present: true` | the flag was passed, whatever its value — the right predicate for a boolean switch |
| `absent: true` | the flag was **not** passed at all |
`matches_regex` also accepts `flags:` (the `re` module's integers, e.g. `2` = `IGNORECASE`, `8` = `MULTILINE`, `16` = `DOTALL`), mirroring [`file_matches_regex`](#file_matches_regex). Setting `flags` next to any other predicate is rejected rather than silently ignored.
Flags the criterion does not mention are ignored, so an extra `--output json` never breaks a match. Repeated flags (`--fields a --fields b`) are satisfied by any one value. A predicate on a flag also listed in `ignore_flags` is rejected at load time — the flag is dropped before predicates run, so it could never be evaluated.
**Which flags carry a value is declared, not guessed.** A flag consumes the following token only if it appears in `flags:`, in `value_flags:`, or in `ignore_flags:`. Everything else is a switch, and the token after it stays positional:
```yaml
# `uip ixp fields delete --yes proj-1`
- type: "cli_called"
description: "Did not delete proj-1"
verb: "ixp fields delete"
positional: ["proj-1"] # --yes is a switch, so proj-1 stays positional
min_count: 0
max_count: 0 # correctly FAILS -- the log proves the delete happened
# `uip ixp projects list --folder Finance proj-1`
- type: "cli_called"
description: "Listed proj-1"
verb: "ixp projects list"
positional: ["proj-1"]
value_flags: ["folder"] # without this, "Finance" would count as a positional
```
Defaulting to "switch" is deliberate: `--yes` / `--force` / `-y` before the target is how destructive CLIs are invoked, so guessing that the flag swallows its neighbour is precisely how a `max_count: 0` guard ends up passing on the call it exists to forbid. The equals form (`--offset=-1`) is unambiguous and always binds directly, and a declared value flag binds even a dash-leading value (`--limit -1`).
`ignore_flags` drops a flag from matching but does **not** make it value-bearing — an ignored flag that takes a value must also appear in `value_flags` (as `output` does by default). Otherwise `ignore_flags: ["verbose"]` on `delete --verbose proj-1` would let `--verbose` eat `proj-1`.
**Clustered short flags are split, and declarations win.** `-rf` matches predicates on `r` and `f` — so a `-yf` cannot escape an `aliases: ["y"]` guard. If your CLI has a genuine multi-character short flag, naming it (in `flags`, `value_flags`, or `ignore_flags`) keeps it whole; and `-fvalue` binds when `f` is value-bearing. A bare negative number stays positional (`seek -1`), unless you declare a flag by that name (`head -1`).
**Negative guards want the FEWEST facets that capture the forbidden act.** This is the opposite of a positive assertion, and it is easy to get backwards. `max_count: 0` passes when *nothing matches*, so every facet you add is another way for the real invocation to slip past the pattern and report a false PASS.
In the delete example above, it is tempting to also assert `--yes`. Don't:
- `--yes` is not the forbidden thing — the deletion is. The CLI *requires* a confirmation flag, so asserting it adds no discriminating power.
- It adds escape routes: `-y` instead of `--yes` (a different flag name) no longer matches, and the guard passes on a delete that did happen.
Use `present: true` — not `equals: ""` — when you do need to assert a switch. `present` needs no value, so it never makes the flag value-bearing; `equals: ""` depends on how the mock happens to record a switch and breaks if the CLI spells it `--force true`.
**Short and long spellings are one flag via `aliases`.** A predicate matches a flag *name*, so `--yes` and `-y` are otherwise unrelated flags:
```yaml
flags:
yes:
present: true
aliases: ["y"] # values gathered across --yes AND -y
```
`present` holds if any listed name appeared, `absent` only if none did, and a value predicate matches if any value under any name satisfies it — so `-f f-002` binds like `--fields f-002`. Splitting the spellings into one criterion each works for a *guard* (both forbidden, and criteria are ANDed) but cannot express "either spelling" positively, and makes `absent` flag **every** invocation, because whichever spelling was not used is always absent. A flag may belong to only one predicate: an alias that is also another key, or that appears in `ignore_flags`, is rejected at load time.
The mirror rule for positive assertions: add every facet that distinguishes the right call from a near-miss, because there a missing facet makes the assertion *too easy* to satisfy.
**Unusable records fail the criterion.** A line that is not JSON, not an object, or whose `argv` is not a list of strings scores 0.0 with an error, on the same footing as a missing log — a record that cannot be read might *be* the invocation a negative guard forbids.
**One predicate per flag** — so a conjunction on a single flag ("contains *both* A and B") is not expressible directly. Two ways to write it:
```yaml
# 1. One matches_regex spanning both. DOTALL (16) is usually needed: a payload
# built with a heredoc contains newlines, and without it `.` stops at the first.
flags:
updates:
matches_regex: '"name": "Invoice Number".*Do NOT use the Purchase Order'
flags: 16
# 2. Or two criteria over the same log, which scores and reports each part separately.
```
**Negative guards.** Set `min_count: 0` and `max_count: 0` to assert a call did **not** happen. A missing log file *fails* rather than counting as zero matches — otherwise a mock writing to the wrong path would make every negative guard pass vacuously.
**Why not a regex over a flattened log line.** A flat `cmd arg arg` string cannot express "verb X was called AND flag Y had value Z" without stacked lookaheads; cannot distinguish a quoted argument containing spaces from two arguments; and cannot stop a match from running across shell operators. Matching `argv` element-wise removes all three problems. `verb` is an **ordered prefix compared token by token**, so `ixp labellings confirm` is never satisfied by `ixp labellings unconfirm`, nor `ixp projects list` by `ixp projects lists`. What a prefix leaves open is the *tail*: `positional` constrains the arguments you name, and anything past them is unconstrained.
### `commands_efficiency`
Scores how economically the agent worked, relative to a budget of expected tool calls. **Continuous scoring:** `score = expected_commands / max(actual_commands, expected_commands)` — so a run at or under budget scores `1.0`, and the score decays as the agent takes more calls than expected (e.g. twice the budget → `0.5`).
```yaml
- type: "commands_efficiency"
expected_commands: 8 # budget of tool calls to complete the task (>= 1)
description: "Agent should solve this in ~8 tool calls"
```
| Field | Default | Description |
|-------|---------|-------------|
| `expected_commands` | *required* | Expected number of tool commands to complete the task (integer, `>= 1`). |
This criterion requires an agent run (it reads `CommandTelemetry`). Pair it with a low `weight` if you want efficiency to *inform* the score without gating pass/fail on its own.
### `uipath_eval`
Evaluates a UiPath agent against a named evaluation set. **Fractional scoring:** metrics passed / total metrics.
> The `uipath` CLI must be available **inside the sandbox** (typically declared in the task's own Python deps). This is independent of the host's optional `coder-eval[uipath]` extra — see the install matrix in [README.md](https://github.com/UiPath/coder_eval/blob/main/README.md#quick-start).
```yaml
- type: "uipath_eval"
agent_name: "my-agent"
eval_set: "regression-v1"
thresholds:
accuracy: 0.8
f1: 0.75
description: "Agent must meet accuracy and F1 thresholds"
```
| Field | Default | Description |
|-------|---------|-------------|
| `agent_name` | *required* | Name of the UiPath agent to evaluate |
| `eval_set` | *required* | Evaluation set identifier |
| `thresholds` | *required* | Minimum acceptable value per metric (metric passes if value >= threshold) |
### `llm_judge`
Have an LLM grade the task against a rubric written in the task YAML. **Continuous scoring** from a verdict the judge returns via a forced `submit_verdict` tool call (`{score: 0.0-1.0, rationale: "..."}`) — the model never returns free-form prose. A missing/malformed verdict, a non-numeric score, or an LLM error all produce `score=0.0` with an `error` populated.
```yaml
- type: "llm_judge"
description: "Implementation follows the rubric"
prompt: |
Grade the implementation on correctness and idiomatic style.
- 1.0: correct and idiomatic
- 0.5: correct but not idiomatic
- 0.0: incorrect or missing
files: ["main.py", "tests/test_main.py"]
include_reference: true # Default: show reference solution to the judge (never to the agent)
include_agent_output: false # Opt-in: include the latest turn's raw agent output
include_tool_calls: false # Opt-in: include a summary of the latest turn's tool calls
include_dialog: false # Opt-in: include the full user<->agent conversation (recommended for simulation)
model: "anthropic.claude-sonnet-4-6"
temperature: 0.0
max_tokens: 2000
max_file_chars: 20000 # Per-file content truncation
weight: 2.0
pass_threshold: 0.7
```
| Field | Default | Description |
|-------|---------|-------------|
| `prompt` | *required* | Grading instructions shown to the judge |
| `files` | `[]` | Paths whose contents are shown to the judge. Plain entries are sandbox-relative; entries prefixed with `$TASK_DIR/` or `$REFERENCE_DIR/` are read from the host filesystem, relative to the task YAML's parent directory and to the staged reference directory respectively (e.g. `$TASK_DIR/../shared/rubric.md` for a rubric shared across a task family, or `$REFERENCE_DIR/rubric.md` for one asset out of the reference — which works regardless of `include_reference`). Missing files render as ``. |
| `include_reference` | `true` | Inline the WHOLE reference directory into the judge prompt, one labelled block per file (silently omitted if no reference is configured). Never shown to the agent. Set `false` and use `$REFERENCE_DIR/` entries in `files` to attach only specific assets. |
| `include_agent_output` | `false` | Include the latest agent turn's raw output (wrapped as UNTRUSTED DATA) |
| `include_tool_calls` | `false` | Include a summary of the latest agent turn's tool calls |
| `include_dialog` | `false` | Include the full user↔agent conversation across **all** turns. In simulation mode the user side is generated by an LLM simulator and may invent premises — the rendered block is wrapped as `UNTRUSTED DATA` and instructs the judge to treat any claim made only by the simulated user as possibly fabricated, so the agent isn't penalized for going along with it (recommended whenever a task uses `simulation:`). |
| `max_dialog_chars` | `80000` | Aggregate cap on dialog text rendered into the judge prompt (per-message cap is `max_file_chars`). When exceeded, trailing turns are dropped and a degraded note is recorded. |
| `model` | `anthropic.claude-sonnet-4-6` | Judge model id (vendor-prefixed; auto-translated per backend) |
| `temperature` | `0.0` | Sampling temperature (0.0 = deterministic) |
| `max_tokens` | `2000` | Maximum tokens in the judge's response |
| `max_file_chars` | `20000` | Per-file (and agent_output) truncation applied before building the prompt |
| `capture_transcript` | `true` | Persist a `JudgeTranscript` (raw verdict + rendered prompts + token usage) to a sibling `judge-.yaml`. Set `false` to drop it when on-disk size matters (e.g. 1000-row datasets); the `findings` on the result persist regardless. |
| `max_transcript_chars` | `100000` | Aggregate cap on captured transcript text (verdict + prompt + system, split 60/30/10). Exceeding it marks the transcript `truncated=True`. |
**Transport selection.** The judge call is routed by the active `API_BACKEND`:
| `API_BACKEND` | Credentials | Judge transport |
|---|---|---|
| `direct` | `ANTHROPIC_API_KEY` set | Anthropic SDK → api.anthropic.com |
| `direct` | `ANTHROPIC_API_KEY` unset | run starts; this criterion fails fast at dispatch with a clear error |
| `bedrock` | `AWS_BEARER_TOKEN_BEDROCK` | AWS Bedrock |
The `direct`-mode transport is resolved once at startup, logged on the `API routing:` line (`anthropic_direct (judge transport: anthropic|none)`), and recorded in `EvaluationResult.environment_info.judge_transport`. Adding or removing `ANTHROPIC_API_KEY` between runs flips the transport, so check the startup log to confirm which path is in use.
**Security**
- The opt-in context blocks (`files`, `include_agent_output`, `include_tool_calls`, `include_dialog`) are wrapped with `UNTRUSTED DATA` / "may invent premises" preambles to mitigate prompt-injection via tool output and to flag simulator-generated user turns.
- The reference solution is shown only to the judge — never to the agent — and any occurrence of the reference is scrubbed from `CriterionResult.details` before persistence.
**Failure modes** — each sets `score=0.0` and populates `error`:
- The judge never emits the forced `submit_verdict` tool call (no verdict returned)
- `score` key missing from the verdict
- `score` is not coercible to float
- Judge backend unavailable / network error (handled by `@handle_criterion_errors`)
### `agent_judge`
Spawn a full Claude Code SDK agent as the judge. Unlike `llm_judge` (a single LLM call against a rubric), the judge agent has **tool access** — a read-only toolkit of `Bash`, `Read`, `Glob`, `Grep` by default (no `Write`/`Edit`) — and runs in an isolated copy of the task sandbox. Use it when functional validation requires executing something (`uip rpa get-errors`, `xmllint`, a test suite) rather than just inspecting file content.
```yaml
- type: "agent_judge"
description: "Judge validates the generated XAML via CLI"
prompt: |
Inspect Main.xaml and grade how well it matches the task requirements.
Do at least these checks using your tools:
1. Valid XML? (`xmllint --noout Main.xaml` or Python's xml.etree)
2. Contains the activities required by the task prompt?
3. Uses VisualBasic expressions (no CSharpValue)?
4. Variable declarations aligned with the reference?
Scoring:
- 1.0: all checks pass, structure aligned with reference
- 0.7: functional but minor structural deviations
- 0.4: partially correct — some critical checks fail
- 0.0: invalid XML or fundamentally wrong structure
files: ["Main.xaml"]
include_reference: true
include_agent_output: false
include_tool_calls: false
include_dialog: false # Opt-in: include the full user<->agent conversation (recommended for simulation)
max_turns: 5
turn_timeout: 300
agent: # Nested AgentConfig — same shape as task.agent
model: "claude-sonnet-5"
permission_mode: "bypassPermissions"
allowed_tools: ["Bash", "Read", "Grep", "Glob"]
sdk_options: {effort: low} # Optional SDK pass-through (e.g. effort)
weight: 5.0
pass_threshold: 0.7
```
| Field | Default | Description |
|-------|---------|-------------|
| `prompt` | *required* | Evaluation instructions for the judge agent |
| `files` | `[]` | Paths pre-attached to the prompt. Plain entries are sandbox-relative (the judge also has live access via its working-directory copy); entries prefixed with `$TASK_DIR/` or `$REFERENCE_DIR/` are read from the host filesystem — relative to the task YAML's parent directory and to the staged reference directory respectively (`$REFERENCE_DIR/` works regardless of `include_reference`) — and are inlined into the prompt only. |
| `include_reference` | `true` | Mount the reference tree at `_reference/` for the judge to Read/Glob (not inlined into the prompt). Use `$REFERENCE_DIR/` entries in `files` to pre-attach specific assets as text. |
| `include_agent_output` | `false` | Include the latest agent turn's raw output (UNTRUSTED) |
| `include_tool_calls` | `false` | Include summarized tool-call telemetry from the latest agent turn |
| `include_dialog` | `false` | Include the full user↔agent conversation across **all** turns. The rendered block is wrapped as `UNTRUSTED DATA` and warns the judge that simulator-generated user messages may invent premises (recommended whenever a task uses `simulation:`). |
| `max_dialog_chars` | `80000` | Aggregate cap on dialog text (per-message cap is `max_file_chars`). Trailing turns are dropped past the cap. |
| `max_file_chars` | `20000` | Per-file truncation for pre-attached files |
| `max_turns` | `50` | Judge's inner-loop turn limit |
| `turn_timeout` | `300` | Wall-clock timeout (seconds) |
| `agent` | hardened judge defaults | Nested `AgentConfig` — `model`, `permission_mode`, `allowed_tools`, `disallowed_tools`, `ignore_patterns`, `sdk_options`. A partial block (e.g. only `model:`) still applies the judge security defaults for missing fields, and the security floor (`.claude` / `.mcp.json` / `_reference` ignore patterns, `setting_sources=[]`) is always enforced. |
| `capture_transcript` | `true` | Persist a `JudgeTranscript` (tool calls + token usage + raw verdict + rendered prompts) to a sibling `judge-.yaml`. Set `false` to drop the trajectory log when on-disk size matters; the `findings` on the result persist regardless. |
| `max_transcript_chars` | `100000` | Aggregate cap on captured transcript text (verdict + prompt + system + tool detail/result-preview lines, split 60/30/10 with tool calls prioritized). Exceeding it marks the transcript `truncated=True`. |
**Security**
The judge runs with the evaluator's API credentials and can execute arbitrary Bash by default. Four attack surfaces:
1. **Malicious generation artifacts** — the coding agent could plant a file that exfiltrates credentials when the judge runs it (e.g. `python generated.py`). Use `llm_judge` for scenarios with adversarial generation.
2. **Prompt injection** — the UNTRUSTED markers on `include_agent_output` / `include_tool_calls` / `include_dialog` are hints, not guarantees. A strong injection could cause the judge to `curl` secrets out before returning a verdict.
3. **Credential exfiltration via Bash** — any network-capable tool can leak credentials. When the task doesn't need Bash (e.g. structural-only inspection), override `allowed_tools: [Read, Grep, Glob]`.
4. **Hooks / MCP servers planted by the main agent** — a compromised generation could drop `.claude/settings.json` or `.mcp.json` into the sandbox. The judge sets `setting_sources=[]` on its SDK config and excludes both paths from the sandbox copy, so neither gets loaded. This closes a pre-LLM-turn hook/MCP surface that the `allowed_tools` gate can't see.
**Reference handling**: The reference solution is MOUNTED at `_reference/` for the judge to browse (rather than inlined as `llm_judge` does) and is scrubbed from the persisted `CriterionResult.details` — a misbehaving judge that echoes the reference in its rationale won't leak it into run artifacts.
**Backend support**: Works on both backends (`direct`, `bedrock`) — the checker forwards the orchestrator's `ApiRoute` to the judge sub-agent.
**Operational notes**:
- Each invocation copies the sandbox into a `/tmp/sub_agent_*` directory and removes it when the check completes.
- The judge's token usage and wall-clock duration appear in `CriterionResult.details`.
- `agent_judge` is expensive relative to other criteria. Keep `max_turns` tight and consider running it alongside cheaper structural checks rather than as the sole gate.
**Failure modes** — each sets `score=0.0` and populates `error`:
- Non-JSON final message from the judge (parse failure)
- `score` missing / non-numeric / non-finite
- `TurnTimeoutError` (judge exceeded `turn_timeout`)
- SDK subprocess failure (e.g. `claude` CLI missing)
### `classification_match`
Matches a single label the agent wrote to a file against ground truth — the file-based classifier. Reads the file, normalizes the content (strip, and lowercase unless `case_sensitive`), and compares it to `expected_label`. **Binary scoring:** `1.0` on a match, else `0.0`.
The observed label is the canonical form from `allowed_labels` when the content matches; otherwise `(none)` when the file is missing/empty and `(other)` when the content isn't in the allowed set. Both sentinels are recorded so a suite rollup shows them as real failure classes in the confusion matrix.
```yaml
- type: "classification_match"
path: "result.txt" # file (relative to sandbox) holding the agent's predicted label
expected_label: "positive"
allowed_labels: [positive, negative]
case_sensitive: false # default: case-insensitive + canonicalized
description: "Sentiment label matches ground truth"
```
| Field | Default | Description |
|-------|---------|-------------|
| `path` | *required* | File (relative to sandbox) containing the agent's predicted label. |
| `expected_label` | *required* | Ground-truth label for this row (drive it from `${row.…}` on a dataset-backed task). |
| `allowed_labels` | *required* | Canonical label set (≥1). Content not in this set becomes `(other)`. |
| `case_sensitive` | `false` | When `false`, matching is case-insensitive and labels are canonicalized. |
Like `skill_triggered`, this criterion emits a `ClassificationCriterionResult`, so on a [dataset-backed task](#dataset) the suite aggregator computes accuracy / precision / recall / F1 and a confusion matrix — gate them with `suite_thresholds`. Use `classification_match` when the agent writes its answer to a file (labeling/extraction tasks); use `skill_triggered` when the signal is whether a skill fired.
### `skill_triggered`
Binary classifier: **did the agent engage the target skill during the run?** Agent-agnostic — scans the run's `turn_records` for either signal: Claude's explicit `Skill` tool call whose `skill` parameter matches `skill_name` (namespace prefixes like `plugin:skill` are stripped, so `skill_name: uipath-agents` matches `Skill(skill="uipath-coded-agents:uipath-agents")`), or — for an agent with no `Skill` tool, e.g. Codex — a command that reads the skill's files off disk (a parameter contains `skills//`, matching both the repo path and the `.agents/skills/` symlink).
Observed label is `"yes"` when either signal is found, else `"no"`. Expected label is `"yes"` iff `expected_skill == skill_name`. **Binary scoring:** `1.0` when observed matches expected, else `0.0`.
```yaml
- type: "skill_triggered"
description: "uipath-agents activation"
skill_name: uipath-agents # the skill to detect (Skill call or file read)
expected_skill: "${row.expected_skill}" # the row's true skill; "" for negatives
suite_thresholds:
recall.yes: 0.70
precision.yes: 0.80
```
| Field | Default | Description |
|-------|---------|-------------|
| `skill_name` | *required* | The skill to detect — a `Skill` call whose `skill` parameter matches, or a file read under `skills//` |
| `expected_skill` | *required* | The row's expected skill (after `${row.*}` substitution); empty string `""` for negative rows where the skill should **not** fire |
**Requires agent telemetry.** This criterion reads `turn_records`, so it only works against a real agent run (not a static check). With no turn records it reports `score=0.0` and an `error`.
**Classification metrics.** `skill_triggered` returns a `ClassificationCriterionResult`, so on a [dataset-backed task](#dataset) the suite aggregator computes accuracy / precision / recall / F1 / confusion matrix across all rows. Gate the suite with `suite_thresholds` using any of: `accuracy`, `macro_f1`, `weighted_f1`, `micro_f1`, or per-label `precision.` / `recall.` / `f1.` (labels are `yes` / `no`). The run exits non-zero if any listed metric falls below its minimum.
**Typical pattern.** Label each dataset row with its true skill (`expected_skill`, `""` for negatives) and stack one `skill_triggered` criterion per skill against the same dataset — each gets its own confusion matrix from the same agent traces. This is the natural companion to a skill A/B experiment (skill plugin on vs. off); see the [A/B Experiment Guide](https://coder-eval.com/docs/ab-experiments#recipe-ab-a-skill).
## Checker Context
`checker_context` carries task-authored config for the success-checking side, namespaced by reserved key. Currently the only recognized namespace is **`api_route`**:
```yaml
success_criteria:
- type: llm_judge
prompt: "Grade the fix for correctness."
checker_context:
api_route:
route: bedrock # which backend the eval side uses
model: claude-haiku-4-5 # model override for that route
```
- `route` selects which backend `llm_judge` and `agent_judge` call — they share one resolved eval route per run for `direct`/`bedrock`/`litellm` (this isn't per-criterion) — **decoupled from the agent's own route** (a Claude agent can be graded by a differently-backed judge, or vice versa). The simulator is NOT part of this sharing: it always resolves its own route the same way the agent under test does (subprocess-safe by construction), independent of `checker_context.api_route` entirely — see the `route: litellm` note below. This is a backend *name* (`direct` / `bedrock` / `litellm`), not a route object. For `direct`/`bedrock` credentials are never read from the task, always from the matching environment variables (`ANTHROPIC_API_KEY` for `direct`, `AWS_BEARER_TOKEN_BEDROCK`/`AWS_REGION` for `bedrock`). An unconfigured or unknown backend name raises at dispatch rather than silently falling back. **`route: litellm` dispatches `llm_judge` ONLY** through the `litellm` library (the `coder-eval[litellm]` extra, `litellm.acompletion`) rather than assuming one wire protocol — a gateway-routed judge model (e.g. an Azure AI `/openai/v1` deployment) rarely speaks Anthropic Messages, so this lets `model` carry its own provider hint (e.g. `azure/gpt-5.6-luna`) and get that provider's actual request/response shape handled by the library. `agent_judge` spawns a real Claude Code CLI subprocess that only speaks Anthropic Messages — combining `route: litellm` with an enabled `agent_judge` criterion is rejected at resolution time (see below); the simulator is unaffected since it never reads this override. Unlike the other two backends, `route: litellm` has NO implicit env-var fallback — see `params`/`env_params` below, which is how it's configured. `model` is required for `route: litellm` (there is no default open-weight/gateway model).
- `model` overrides the model that resolved route uses for **`llm_judge` only** — when the criterion itself leaves `model:` unset (precedence: an explicit per-criterion `model:` always wins; below that, `checker_context.api_route.model`; below that, the built-in `DEFAULT_JUDGE_MODEL`). This floor is deliberate and never the agent's own model — an unpinned judge must grade identically regardless of which model the agent under test is using, so `resolve_evaluation_route` never lets the agent's env-configured model (e.g. `BEDROCK_MODEL`) leak into `route.model` on its own; `route.model` is set only when this override was actually given. This works because every `ApiRoute` (`DirectRoute`/`BedrockRoute`/`LiteLLMRoute`) carries its own `model` field; the orchestrator bakes the override into the resolved route's `model` before any criterion runs, so `llm_judge` just reads `context.route.model` — it never reads `checker_context` directly. **`agent_judge` and the simulator do not honor this override** — `agent_judge`'s sub-agent model comes from the criterion's own `agent:` block (defaulted to a fixed judge model), and the simulator's model is pinned by `SimulationConfig.model` (see [Simulation](#simulation) below) — both independent of `checker_context.api_route.model` by design, for the same "measuring instrument stays fixed" reason.
- `params`/`env_params` (**`route: litellm` only**) are how the call is actually configured — there is no fallback to the agent's own `LITELLM_BASE_URL`/`LITELLM_AUTH_TOKEN` env vars, since a gateway-routed judge model rarely reuses the agent's own LiteLLM proxy/credential. They also cover any of the dozens of other provider-specific kwargs `litellm.acompletion` accepts (`aws_access_key_id`, `vertex_project`, `api_version`, ...), which have no dedicated field on `LiteLLMRoute`:
```yaml
checker_context:
api_route:
route: litellm
model: azure/gpt-5.6-luna
params: # arbitrary literal passthrough kwargs to litellm.acompletion
api_version: "2024-05-01"
env_params: # param name -> ENV VAR NAME (never the secret itself)
api_base: LITELLM_BASE_URL
api_key: LITELLM_AUTH_TOKEN
```
`params` is merged straight into the `litellm.acompletion(**kwargs)` call — litellm validates the param names itself, so there's no allowlist to keep in sync here. `env_params` maps a kwarg name to the *name* of an environment variable; the value is resolved right before the call, so no secret is ever written into task/experiment YAML — this is how an arbitrary provider's config, including secrets (IAM keys, an Azure AD token, a service-account path, ...), is representable without a dedicated field per provider. `env_params` is resolved after `params`, so it always wins for the same key. Rejected at task-load time if given without `route: litellm`. For an Azure deployment, pin `api_version` via `params` to whatever API version the agent side is actually configured for (e.g. Codex's `CODEX_API_VERSION`) — the judge has no way to inherit it, and a mismatched version can hit a different shape of the same endpoint.
**`route: litellm` has no bearing on the simulator** — the simulator is a real Claude Code CLI subprocess that speaks the Anthropic Messages protocol, so pointing it at an arbitrary litellm-fronted gateway (which may speak an entirely different wire protocol) isn't representable. Rather than rejecting a task that combines `route: litellm` with `simulation.enabled: true`, the simulator always resolves its own route independently of `checker_context.api_route` — the same way the agent under test resolves its route — so `llm_judge` grades through the gateway named here while the simulator behaves exactly as if this override weren't set. A task can freely combine `route: litellm` with `simulation.enabled: true`; there is nothing to disable or remove. **`agent_judge` is NOT decoupled the same way** — it still shares the `llm_judge` eval route, and `agent_judge`'s Claude Code CLI subprocess has no way to honor a `LiteLLMRoute` safely, so the orchestrator rejects `route: litellm` combined with an enabled `agent_judge` criterion at resolution time (a clear error, not a silent misroute) — use `route: bedrock`/`direct` instead if a task needs both.
`checker_context` merges shallow-per-namespace across `default_experiment.defaults.checker_context` → `experiment.defaults.checker_context` → `task.checker_context` → `variant.checker_context` (same 4-layer precedence as `agent`/`simulation`). So a judge-model A/B, or a judge-backend A/B, is a variant-level config change, not an edit to every task YAML.
## Reference Solutions
A reference solution is always a **directory**, given relative to the task YAML's own directory:
```yaml
reference:
directory: "reference"
```
| Field | Default | Description |
|-------|---------|-------------|
| `directory` | *required* | Directory holding the reference solution, relative to the task YAML. Exposed to criteria as `$REFERENCE_DIR` and the `REFERENCE_DIR` env var. |
There is no inline `code:` or single-file `file:` form. A directory is the only
shape that can be permission-gated as a unit (see below), and a one-file
reference is just a directory containing one file.
> **Migrating from `code:` / `file:`.** This is a **breaking** task-schema
> change, and it is a hard load error, not a silent downgrade — a task carrying
> either key fails validation with a message naming the replacement. Every task
> suite outside this repo (the `coder-eval-uipath` / eval-runner suites among
> them) must migrate before its next scheduled run:
>
> | Was | Now |
> |-----|-----|
> | `reference: {code: ""}` | write the source to a file in a directory, then `reference: {directory: "reference"}` |
> | `reference: {file: "solution.py"}` | move the file into a directory: `reference: {directory: "reference"}` |
>
> `reference_comparison` also gained a **required** `reference_file` naming
> which file inside that directory to compare against — previously implicit
> because there was only one.
>
> **Score-comparability warning.** `include_reference: true` (still the default)
> changed meaning for `llm_judge`: it used to inline the one reference file, and
> now inlines the **whole reference directory** (capped at 200 000 chars, files
> truncated to `max_file_chars` each, trailing files dropped with an explicit
> "omitted" marker). Every pre-existing judge task with a reference therefore
> sends a larger, differently-shaped prompt — judge scores are **not comparable
> across this migration**, and per-judge token cost rises roughly in proportion
> to the added reference bytes. Re-baseline any trend line that spans it, or set
> `include_reference: false` and attach the one asset you want with a
> `$REFERENCE_DIR/` entry in `files:` to restore the old shape.
>
> **Docker image lockstep.** The host↔image contract changed (a new
> `/work/references` bind mount plus a tmpfs mask over the reference's original
> location inside the task-dir mount). A pinned or cached `coder-eval-agent`
> image predating this change will fail closed with a missing-mount error rather
> than grade against an empty reference — but rebuild and republish the image in
> lockstep (`make docker-image`) so docker-driver pipelines don't simply stop.
### The agent never sees it
The agent under evaluation shares a filesystem with the harness, so "don't show
it to the agent" is not enough on its own — an agent that greps the task
directory finds the answer. Two mechanisms prevent that:
1. **A per-run private copy.** The reference is staged into a throwaway directory
for the duration of the run and deleted at cleanup. It is never copied into
`run_dir/artifacts`, so archived and shared run directories carry no solution.
2. **A mode-000 window.** Under `driver: docker`, that staged copy is chmod'd
to `000` for the whole of every `agent.communicate` call, and restored afterwards — including on crash,
timeout, and cancellation. Criteria and judges run outside the window and
read normally. The task directory is deliberately NOT shielded: under docker
it is a `:ro` mount (chmod fails with EROFS) and the same task YAML is
readable at `/work/input` regardless. On the host (`driver: tempdir`) the
window is a deliberate no-op: the agent runs with the same uid as the harness, so a `chmod` it can
simply undo buys no isolation, and the checked-out `tasks/` tree is shared
across a parallel batch. **Use `driver: docker` for any suite where the
reference must be unreachable.**
Under `driver: docker` the reference is bind-mounted **read-write** at
`/work/references` — deliberately: it is a throwaway copy, and a `:ro` mount
cannot be chmod'd (EROFS), so the window could not be applied at all. An empty
tmpfs masks its original location inside the task-directory mount, and the
container drops `DAC_OVERRIDE` and `DAC_READ_SEARCH`.
> **What this does and does not guarantee.** The mode-000 window stops an agent
> that *passively reads* the reference — `ls`, `cat`, `grep` all fail. Two
> things it does **not** stop:
>
> 1. **A deliberate re-chmod.** `chmod(2)` is gated on *owner-or-`CAP_FOWNER`*,
> and the container runs as root, which owns the bind-mounted copy. Verified:
> `chmod 755 /work/references` succeeds from inside the container and the
> solution is then readable. Dropping `FOWNER`/`CHOWN` does **not** fix this
> and is deliberately not done — the in-container orchestrator that *applies*
> the window is the same root process with the same capabilities, so dropping
> `FOWNER` breaks the harness's own `chmod` wherever the bind mount preserves
> a non-root owner (native Linux). Verified: container root, uid-1000-owned
> directory, `FOWNER` dropped → `chmod: Operation not permitted`. The drop
> only bites on the hosts where it also disables the control.
> 2. **Waiting the window out.** The window spans `agent.communicate`, so
> between turns and after the final one the reference is back at its normal
> mode, and nothing reaps the agent's child processes at turn end — a
> backgrounded read loop started during a turn succeeds once the window
> closes.
>
> The *write* half of (2) IS closed: the reference tree is hashed at staging
> time and re-verified before grading, and a mismatch fails the run with
> `ReferenceTamperedError` rather than scoring `reference_comparison` against a
> file the agent wrote. **Closing the read half fully requires running the agent
> as a non-root uid that does not own the reference, and holding the window for
> the agent's whole lifetime** — tracked as follow-up. Treat the current control
> as raising the cost of accidental leakage, not as a boundary against an
> adversarial agent.
### Addressing reference files
Criteria reach into the reference with the `$REFERENCE_DIR` token, which works
anywhere `$TASK_DIR` does:
```yaml
reference:
directory: "reference"
success_criteria:
# Attach one specific asset to a judge prompt
- type: "llm_judge"
description: "Graded against the published rubric"
prompt: "Grade the solution against the rubric."
include_reference: false # don't inline the whole tree...
files:
- "solution.py" # sandbox-relative (the agent's work)
- "$REFERENCE_DIR/rubric.md" # ...just this one reference asset
# Or compare against a single reference file
- type: "reference_comparison"
description: "Structure matches the reference"
agent_file: "solution.py"
reference_file: "solution.py"
```
`run_command` criteria get the same directory as the `REFERENCE_DIR` environment
variable (alongside `TASK_DIR`), so `diff -r "$REFERENCE_DIR" out/` works.
Symlinks inside `reference.directory` are **dropped** when the reference is
staged (they would otherwise pull host files into a directory a judge sub-agent
can read). Ship real files — a `reference_file:` or `$REFERENCE_DIR/...` entry
pointing at a symlink resolves to nothing.
## Pre-Run Commands
Run shell commands inside the sandbox **after setup completes but before the agent starts**.
Use them to seed databases, start background services, or prepare the environment.
By default (`fail_on_error: true`), a non-zero exit code, timeout, or exception **aborts
the evaluation** with `FinalStatus.ERROR` — the agent should not run against a broken
environment. Set `fail_on_error: false` per command for optional/informational steps.
```yaml
pre_run:
- command: "python seed_db.py"
timeout: 30
# fail_on_error defaults to true — if seeding fails, abort
- command: "start-mock-server.sh &"
# shell exits 0 immediately; background daemon keeps running
- command: "python check_connectivity.py"
fail_on_error: false # warn but don't abort if connectivity check fails
```
| Field | Default | Description |
|-------|---------|-------------|
| `command` | *required* | Shell command to execute (supports pipes, redirects, `&` for background) |
| `timeout` | 30 | Maximum seconds to wait (1–300) |
| `fail_on_error` | `true` | When true, failure aborts evaluation with `FinalStatus.ERROR` |
Commands run sequentially with `cwd` set to the sandbox directory. stdout and stderr are
captured in `pre_run_results` on the evaluation result (truncated to 100KB each). When a
command fails with `fail_on_error: true`, remaining commands are skipped.
**Execution order:**
1. Sandbox setup (template sources applied, venv/node packages installed)
2. **Pre-run commands** ← here
3. Agent evaluation loop
4. Success criteria checks
5. Post-run commands (if configured)
**Experiment-level defaults:**
Set `defaults.pre_run` in an experiment YAML to seed the environment before every task.
Experiment defaults are **prepended** before the task's own `pre_run` (baseline setup first):
```yaml
defaults:
pre_run:
- command: "docker-compose up -d"
timeout: 60
```
## Post-Run Commands
Run shell commands inside the sandbox after evaluation completes. Post-run commands are **informational only** — they never affect pass/fail status. Use them for artifact generation, data extraction, validation reports, or cleanup.
```yaml
post_run:
- command: "python3 validate_flow.py output.flow 12 4"
timeout: 60
- command: "cat results.json | jq '.summary'"
- command: "tar czf /tmp/artifacts.tar.gz ."
timeout: 120
```
| Field | Default | Description |
|-------|---------|-------------|
| `command` | *required* | Shell command to execute (supports pipes, redirects, etc.) |
| `timeout` | 30 | Maximum seconds to wait (1–300) |
Commands run sequentially with `cwd` set to the sandbox directory. stdout and stderr are captured on the `post_run_results` field of the evaluation result (truncated to 100KB each).
**Experiment-level defaults:**
Set `defaults.post_run` in an experiment YAML to run cleanup or extraction after every task.
Experiment defaults are **appended** after the task's own `post_run` (task-specific work first, then defaults):
```yaml
defaults:
post_run:
- command: "rm -rf node_modules .npm-prefix"
timeout: 30
```
The shipped `experiments/*.yaml` use this to drop sandbox-scoped npm dirs (introduced by [PR #250](https://github.com/UiPath/coder_eval/pull/250) for MST-9674) so preserved-sandbox artifacts stay small.
## Simulation (Multi-Turn User Dialog)
Optional `simulation` block. When present and enabled, the orchestrator replaces the single-shot iteration loop with a multi-turn dialog between the coding agent and a simulated user (a second LLM with a persona and goal). Use this for tasks where the real usage pattern is conversational — clarifying questions, incremental requirements, mid-task corrections — rather than a single fire-and-forget prompt.
> This section is the field reference. For when to use dialog mode, how to design a persona and
> goal, trials and variance, grading, and cost, see **[Dialog Mode](https://coder-eval.com/docs/dialog-mode)**.
```yaml
simulation:
enabled: true # Master switch; when false, simulation is skipped entirely.
# Persona and goal (required).
persona: |
A non-technical business analyst who knows the outcome they want
but not how automation works. Mildly impatient.
goal: |
Build a flow that reads invoice PDFs from an Outlook folder,
extracts vendor/amount/date, and posts to Google Sheets.
Do NOT volunteer the Google Sheets requirement unless asked.
constraints: # Optional behavioral rules.
- "Do not paste code — you cannot read code."
- "If the agent goes silent for two turns, ask 'are you still there?'."
# Termination.
max_turns: 12 # Hard cap on user↔agent exchanges.
stop_token: "<<>>" # Simulator emits this when it judges the task complete.
stop_on_criteria_pass: true # End early when all success criteria pass.
max_total_tokens: 150000 # Optional budget across the whole dialog.
# Sampling (variance analysis).
n_trials: 3 # Run N independent dialogs per (task, variant).
# Who plays the simulated user. Pinned, NOT inherited from the run's route.
model: anthropic.claude-sonnet-4-6
# Criteria timing.
check_criteria: every_turn # One of: end_of_dialog | every_turn | both.
# Required to be 'every_turn' or 'both' when
# stop_on_criteria_pass is True.
```
| Field | Default | Description |
|-------|---------|-------------|
| `enabled` | `false` | When false, simulation is skipped; task runs in single-shot mode. |
| `persona` | *required* | Who the simulator is roleplaying. |
| `goal` | *required* | What the simulated user wants. |
| `constraints` | `[]` | Behavioral rules the simulator must follow. |
| `max_turns` | `8` | Hard cap on user↔agent exchanges (1–100). |
| `stop_token` | `"<<>>"` | Sentinel the simulator emits to end the dialog. |
| `stop_on_criteria_pass` | `false` | End when all criteria pass (requires per-turn checking). |
| `max_total_tokens` | *unset* | Optional dialog-wide token budget (simulator **plus** agent). Distinct from [`run_limits.max_total_tokens`](#run-limits) — see below. |
| `n_trials` | `1` | Independent dialog trajectories per (task, variant). |
| `check_criteria` | `end_of_dialog` | `end_of_dialog`, `every_turn`, or `both`. |
| `model` | `anthropic.claude-sonnet-4-6` | Model that plays the simulated user. Auto-translated to the run's backend (Bedrock inference profile / bare Anthropic alias), the same way [`llm_judge`](#llm_judge)'s `model` is. |
The simulator runs as a tools-disabled Claude Code agent on its own resolved `ApiRoute` (the same resolution as the coding agent's own route — [`checker_context.api_route.route`](#checker-context) has no bearing on it), so temperature and sampling are resolved at the route level (same `-b` flag as the coding agent by default) and are not configured on this block. The **model is not**: it is pinned by `model` above. Inheriting it from the route meant `BEDROCK_MODEL` decided who the simulated user was, so an A/B varying the subject model silently varied its interlocutor too. Hold `model` fixed across variants for the same reason you hold a judge model fixed — the simulator is part of the measuring instrument, not the thing being measured.
**Semantics:**
- The task's `initial_prompt` is the user's *opening* message; the simulator picks up from turn 2.
- `max_turns` is the intra-dialog cap (the worst-case agent call budget per trial). Use `n_trials` for variance sampling.
- The `reference` solution, if present, is hidden from the simulator (same security posture as for the coding agent).
- When `n_trials > 1`, each trial becomes its own `ResolvedTask` with its own zero-padded replicate directory (`runs/////`) and its own `task.json` — the same fan-out mechanism as experiment `repeats`, which `n_trials` takes precedence over when simulation is enabled. Trial-level metadata appears under `simulation.replicate_index` / `simulation.n_trials` on the `EvaluationResult`.
**Termination precedence** (evaluated after each exchange, first match wins): `run_limits` breach →
`stop_on_criteria_pass` → `max_turns` → `max_total_tokens` → `stop_token`. The stop token is checked
**last**, on the simulator's next utterance, which is only solicited if nothing above fired — so a
turn that hits `max_turns` or the token budget ends the dialog before the simulator can emit it.
A raising simulator call ends the dialog with `stop_reason: error`.
> **`simulation.max_total_tokens` vs. `run_limits.max_total_tokens`.** This one covers the **whole
> dialog** (simulator + agent) and ends the conversation gracefully with `stop_reason='budget'`, so
> the task is still scored. [`run_limits.max_total_tokens`](#run-limits) covers the **subject agent
> only** and **aborts** the task with `FinalStatus.TOKEN_BUDGET_EXCEEDED`. They compose — set both
> for a hard ceiling on a simulated task.
**Grading simulated dialogs.** When a task uses `simulation:`, set `include_dialog: true` on any `llm_judge` / `agent_judge` criterion. Without it, the judge sees only the agent's outputs and may flag a fabricated-but-conceded premise as a hallucination by the agent. The dialog block is rendered with a rubric guard telling the judge to treat any claim made only by the simulated user as possibly invented, and not to penalize the agent for going along with it unless the grading prompt contradicts it.
**Experiment variants** can override any simulation field (persona, goal, constraints, n_trials, etc.) by setting a partial `simulation:` block on a variant — it is shallow-merged onto the task's simulation block. Useful experiment axes: simulator persona (terse vs. chatty), goal withholding, and n_trials for budget/quality tradeoffs.
## Command Telemetry
The framework automatically tracks all agent commands. No configuration needed.
**What's tracked:**
- Tool name and parameters
- Duration (millisecond precision)
- Status (success, error, unknown)
- Execution sequence within each turn
**Token usage** is also tracked (input/output tokens per turn) for cost analysis.
Results include aggregated statistics:
```json
{
"command_stats": {
"total_commands": 42,
"commands_by_tool": { "Read": 15, "Write": 12, "Bash": 10 },
"total_command_time_ms": 8543.2,
"success_rate": 0.95,
"slowest_commands": [...]
}
}
```
## Complete Example
A full-featured task definition using most features:
```yaml
task_id: "calculator_agent"
description: "Create a calculator agent using LangGraph"
initial_prompt: |
Create a calculator agent using StateGraph that performs
basic arithmetic operations (+, -, *, /).
agent:
type: "claude-code"
permission_mode: "acceptEdits"
allowed_tools: ["Read", "Write", "Bash"]
sandbox:
driver: "tempdir"
python:
env_packages:
- pytest
- pylint>=3.0
template_sources:
- type: "template_dir"
path: "../templates/python-starter"
success_criteria:
- type: "file_exists"
path: "main.py"
description: "main.py must exist"
weight: 0.5
- type: "file_contains"
path: "main.py"
includes: ["StateGraph", "BaseModel"]
description: "Must use required libraries"
weight: 2.0
- type: "run_command"
command: "python -m py_compile main.py"
timeout: 10
description: "Valid Python syntax"
- type: "reference_comparison"
agent_file: "main.py"
reference_file: "main.py"
comparison_method: "ast"
similarity_threshold: 0.7
description: "Code structure matches reference"
weight: 2.5
- type: "command_executed"
tool_name: "Bash"
command_pattern: "python.*main\\.py"
min_count: 1
description: "Agent must run the script"
reference:
directory: "reference" # ./reference/main.py holds the solution
```
---
# Running Claude Code in Coder Eval
## Overview
**Claude Code is the default agent** in Coder Eval — `agent.type: claude-code`. It
ships in the base install (no extra needed; the `claude-agent-sdk` is a core
dependency), and most tasks and tutorials assume it. This guide is the reference
for its config surface, authentication, and telemetry; for the agent-agnostic task
schema see the [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide).
Because `agent.type` defaults to `claude-code` in `experiments/default.yaml`, you can
omit the `type` field entirely.
## Setup
Nothing beyond the base install:
```bash
uv tool install coder-eval # or: pip install coder-eval
```
Provide model credentials (see [Authentication](#authentication)) and you're ready:
```bash
coder-eval run tasks/hello_date.yaml # claude-code is the default
```
## Authentication
Claude Code routing follows the `--backend` flag (or `API_BACKEND` env var):
### Direct (default)
`--backend direct` calls the Anthropic API. The SDK picks its own credential, in
order:
1. `ANTHROPIC_API_KEY` in the environment / `.env`, or
2. a cached `claude login` (subscription) session.
No key is validated at startup — the SDK fails with a clear error if none is found.
The `llm_judge` / `agent_judge` criteria also need `ANTHROPIC_API_KEY` under the
direct backend (they call `api.anthropic.com`).
### AWS Bedrock
`--backend bedrock` routes through Bedrock with bearer-token auth. Set in `.env`:
| Variable | Purpose |
| --- | --- |
| `AWS_BEARER_TOKEN_BEDROCK` | Bedrock bearer token (required) |
| `AWS_REGION` | Bedrock region, e.g. `eu-north-1` (required) |
| `BEDROCK_MODEL` | Cross-region model id, e.g. `eu.anthropic.claude-sonnet-5` (required) |
| `BEDROCK_SMALL_MODEL` | Small/fast model id (falls back to the main model) |
The agent sets `CLAUDE_CODE_USE_BEDROCK=1` and forwards these into the SDK
subprocess. `BEDROCK_MODEL` is the route-level default; an explicit `--model` /
`-D agent.model=…` / task `agent.model` always wins over it, and bare aliases are
auto-qualified to a regional inference profile (`eu.` / `us.` / `apac.` / `global.`).
> **For official benchmarking use the direct API** — the SDK reports accurate
> token/cost there. See [User Guide → API Routing](https://coder-eval.com/docs/user-guide#api-routing--benchmarking).
## Agent config surface
All fields live under `agent:` in a task (or an experiment variant). Only `type` is
required; everything else has a default.
```yaml
agent:
type: claude-code
model: claude-sonnet-5 # optional; omit to use the route default
permission_mode: acceptEdits # default | acceptEdits | plan | bypassPermissions
allowed_tools: ["Read", "Write", "Bash"]
disallowed_tools: ["WebSearch"]
setting_sources: [] # [] = fully isolated (recommended, see below)
plugins:
- type: local
path: "$SKILLS_PLUGIN_PATH"
system_prompt: "You are a careful engineer." # or system_prompt_file
claude_settings:
permissions:
deny: ["Read(/etc/**)"]
sdk_options:
effort: high
```
| Field | Type / default | Meaning |
| --- | --- | --- |
| `type` | `"claude-code"` | Agent kind (the default). |
| `model` | `str \| null` | Specific model id. Omit to use the backend/route default. |
| `permission_mode` | default **`acceptEdits`** | `default` / `acceptEdits` / `plan` / `bypassPermissions` — semantics come from the Claude Code SDK. `plan` is read-only; `bypassPermissions` grants full autonomy. |
| `allowed_tools` | `list[str] \| null` | Tool allowlist. Unset ⇒ all tools allowed. |
| `disallowed_tools` | `list[str] \| null` | Tool denylist. (`ToolSearch` is always appended for Bedrock parity.) |
| `plugins` | `list[{type: local, path}]` | Local plugin roots; `$VAR` in `path` is expanded and resolved to an absolute path. **`path` must hold a `skills/` subdirectory** — a bare directory of skill directories loads nothing here, though Codex and Antigravity accept it. See [Harness parity](https://coder-eval.com/docs/agents/harness-parity#agentpluginspath-accepts-different-depths-per-harness). |
| `system_prompt` | `str \| null` | **Appended** to the default Claude Code system prompt (via the SDK's `claude_code` preset) — the default's behavioral guidance is kept unless `system_prompt_mode: replace` opts out. Mutually exclusive with `system_prompt_file`. An empty or whitespace-only value is treated as unset. |
| `system_prompt_mode` | `"append"` (default) / `"replace"` | `replace` sends `system_prompt` as the **entire** system prompt (no preset) and requires a non-blank `system_prompt` / `system_prompt_file` (validated at load). Used by judge sub-agents and the user simulator, which must not carry the coding-agent persona; rarely needed in tasks — see [the migration note](#migrating-tasks-that-set-system_prompt). |
| `system_prompt_file` | `str \| null` | Path (relative to the task YAML) loaded into `system_prompt` at resolution. Works with either `system_prompt_mode`. |
| `setting_sources` | `list["user"\|"project"\|"local"] \| null` | Which host setting sources the SDK reads. Default resolves to `["project"]`. See [Sandbox isolation](#sandbox-isolation). |
| `claude_settings` | `str \| dict \| null` | Passed to the SDK `--settings`. A dict is JSON-serialized; a str is a settings file path. Use `permissions.deny` to block tools/paths. |
| `sdk_options` | `dict` (default `{}`) | Pass-through for `ClaudeAgentOptions` fields Coder Eval doesn't own (e.g. `effort`). Validated at load — an unknown or framework-owned key is a hard error. |
| `ignore_patterns` | `list[str] \| null` | Gitignore-style overrides for the workspace copy used by judge sub-agents (supports `!` negation). |
> `sdk_options` is a deliberate escape hatch. Framework-owned keys (`model`,
> `permission_mode`, `allowed_tools`, `mcp_servers`, `resume`, `max_turns`,
> `setting_sources`, `include_partial_messages`, …) are rejected there — set those
> through their typed fields or `-D run_limits.*`. MCP servers are not a YAML field.
> **System-prompt reproducibility.** In `append` mode the preset's *dynamic
> sections* (working directory, git status, auto-memory) are excluded so the system
> prompt stays identical across runs — the per-run sandbox tempdir path would
> otherwise be baked into it, breaking prompt caching and run comparability. The
> SDK re-injects the stripped content into the first user message, so the agent
> loses nothing. Note the default-prompt baseline tracks the installed Claude Code
> CLI version; `environment_info.claude_code_cli` in `run.json` records which
> version a run used, and `environment_info.system_prompt_semantics`
> (`append` / `replace`) records the prompt regime — runs predating that marker
> used replace-on-set / empty-on-unset semantics and are not score-comparable.
### Migrating tasks that set `system_prompt`
`system_prompt` used to **replace** Claude Code's default system prompt. It now
appends to it. If your task or experiment sets `system_prompt`, the agent gains back
every default behavioral instruction it was previously running without — parallel
tool-call batching, conciseness rules, the `Read`/`Grep`/`Glob` tool preferences, and
the default security guardrails.
That is a genuine behavior change, so **scores are not comparable across this
boundary**. Pick one:
- **Keep the repair (recommended).** Do nothing. Re-baseline any threshold or
reference score the task gates on, and expect turn counts to drop on tasks that
depend on batched tool calls.
- **Preserve the old behavior.** Add `system_prompt_mode: replace` to the `agent:`
block. The configured prompt again becomes the entire system prompt. Only do this
if the task *intends* to run without the default guidance — a prompt that merely
adds sandbox policy or a persona does not.
Segment dashboards on `environment_info.system_prompt_semantics` to keep the two
regimes in separate cohorts. Note the append-mode baseline also tracks the installed
CLI version, so a `CLAUDE_CODE_VERSION` bump becomes a score-affecting change
(attributable via `environment_info.claude_code_cli`).
> **Consumers reading `sdk_options.system_prompt`.** The persisted value changed
> shape: a plain `str` in the old regime, a `SystemPromptPreset` dict
> (`{type, preset, exclude_dynamic_sections, append}`) in append mode. Code that
> string-handles that field needs to branch on the type — see
> [Report schema](https://coder-eval.com/docs/report-schema).
### Setting fields from the CLI
Any of these merge-resolve through `-D` / `--set` (see
[User Guide → CLI overrides](https://coder-eval.com/docs/user-guide#cli-commands)):
```bash
coder-eval run tasks/hello_date.yaml \
-D agent.model=claude-opus-5 \
-D agent.permission_mode=plan \
-D agent.sdk_options.effort=high
```
## Sandbox isolation
`setting_sources` controls whether the host project's settings leak into the run.
The default (`["project"]`) lets the SDK discover `.mcp.json` — but it also pulls in
the host project's `CLAUDE.md`, settings, and hooks, which for this repo is 20 KB+
injected into every API call (inflating cache-creation tokens and cost).
**For tasks that don't need host MCP servers, set `setting_sources: []`** for full
isolation from the host `CLAUDE.md`/settings/hooks. (Judge sub-agents and the user
simulator force `[]` for the same reason.)
## Skills & plugins
- **Skills** are engaged via Claude's explicit `Skill` tool call; the
[`skill_triggered`](https://coder-eval.com/docs/task-definition-guide#skill_triggered) criterion detects
that call and scores skill-activation suites.
- **Plugins** are supplied as `plugins: [{type: local, path: …}]`; the path is
env-expanded and resolved to an absolute path before being handed to the SDK.
It must name a **plugin root** — a directory holding `skills/`, so the skill
resolves at `/skills//SKILL.md`. One level deeper loads nothing, with
no error: every positive row of an activation suite then scores 0 and the suite
reports recall 0.0, which reads exactly like a skill that never triggers. Codex
and Antigravity scan both depths, so this is claude-code-only — see
[Harness parity](https://coder-eval.com/docs/agents/harness-parity#agentpluginspath-accepts-different-depths-per-harness).
- A plugin root loads **everything** the plugin declares, not only `skills/`: an
`agents/`, `commands/` or `hooks/` directory beside it becomes visible to the
evaluated agent too. Point at a minimal root when the suite must measure one
skill in isolation.
- **`PLUGIN_TOOLS_DIR`** pins the canonical `node_modules/@uipath` directory for
UiPath CLI plugin discovery; when unset the sandbox derives it from the resolved
`uip` binary. See [User Guide → Environment Variables](https://coder-eval.com/docs/user-guide#environment-variables).
## Early stop
Claude Code supports the cooperative early-stop seam, as do the
[Codex](https://coder-eval.com/docs/agents/codex) and [Antigravity](https://coder-eval.com/docs/agents/antigravity) agents. When a criterion
carries a `stop_early:` block, a single-shot run ends cleanly at the next
tool-call boundary once its **armed** criteria (those carrying a
`stop_early:` block) are
decided — so a raised `max_turns` isn't wasted on a smoke run. Early stop errors at
resolution for any agent that does not declare `supports_cooperative_stop`. See the
[Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) for the full contract.
## Telemetry
Claude Code produces the richest telemetry of the agents:
- **Authoritative billing** comes from the SDK's cumulative `model_usage` on the
terminal result message and reconciles to `total_cost_usd` — this already includes
sub-agent consumption that the per-message stream under-reports.
- **Sub-agent accounting** is derived by grouping `parent_tool_use_id`-tagged
assistant messages; there is no separate per-sub-agent field. The terminal
sub-agent generation (delivered as the Agent tool result, never streamed) is
synthesized into one message.
- **Reconciliation message.** Because the per-message stream slightly under-reports
the turn total (a fixed ~512-token input slice is billed on no streamed message,
and sub-agent input/cache only partially bubbles up), each turn carries one
synthetic `role="reconciliation"` entry holding the per-bucket residual. The
invariant: summing the token buckets across `TurnRecord.messages` equals the turn
total exactly. It carries no cost and is excluded from turn/generation counts.
Set the `CODER_EVAL_RAW_SDK_LOG` environment variable to `1` to dump every raw SDK
event to the task log.
## Lifecycle & robustness
- **Session resume** across turns via the SDK `resume` option; the session id only
advances on clean (non-error) turns.
- **Timeouts** are enforced by a `ThreadedWatchdog` (an OS-thread timer immune to
event-loop stalls) plus an in-loop wall-clock guard; on breach it SIGKILLs the CLI
subprocess and raises `TurnTimeoutError` with a partial `TurnRecord` preserved.
- **Crashes** raise `AgentCrashError` with assembled stderr; the orchestrator drains
the partial turn and rolls back. Cost is backfilled from the rate card when a run
is killed before a terminal result message arrives.
## References
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) — the full task/criterion schema
- [User Guide](https://coder-eval.com/docs/user-guide) — CLI, backends, environment variables
- [Codex Agent Guide](https://coder-eval.com/docs/agents/codex) · [Antigravity (Gemini) Agent Guide](https://coder-eval.com/docs/agents/antigravity)
- [Extending Coder Eval](https://coder-eval.com/docs/extending) — how agents register via the plugin SPI
---
# Running OpenAI Codex in Coder Eval
## Overview
Coder Eval can run OpenAI's Codex as the agent under evaluation, via the official Codex SDK. The `CodexAgent` mirrors the structure of `ClaudeCodeAgent` and plugs into the same sandbox, scoring, and telemetry pipeline — set `agent.type: codex` in a task and the rest of the framework works unchanged.
## Setup
### 1. Install the Codex SDK
Install coder-eval with the `codex` extra:
```bash
pip install 'coder-eval[codex]'
```
This installs:
- `openai-codex` - The official Codex Python SDK (from PyPI)
- `openai-codex-cli-bin` - Platform-specific Codex CLI binaries (pulled in transitively)
### 2. Authentication
Codex requires authentication. Options:
```python
# Option 1: API Key (direct)
await codex_client.login_api_key("your-api-key")
# Option 2: ChatGPT (interactive)
await codex_client.login_chatgpt()
# Option 3: Device Code Flow
await codex_client.login_chatgpt_device_code()
```
`CodexAgent.start()` calls `login_api_key` automatically when **`CODEX_API_KEY`** is present in the environment. Without a key it falls back to any existing ChatGPT login. (Only `CODEX_API_KEY` is read — not `OPENAI_API_KEY`/`AZURE_OPENAI_API_KEY`; point `CODEX_API_KEY` at whichever endpoint's key you use.)
### Endpoint routing
| Env var | Purpose |
|---|---|
| `CODEX_API_KEY` | Auth key/token for the selected endpoint (required for headless runs). |
| `CODEX_BASE_URL` | Route to a custom endpoint. **Unset → standard OpenAI platform** (api.openai.com). Set → custom provider (gateway or Azure). |
| `CODEX_MODEL` | Fallback model when `agent.model` is unset. On Azure this is the **deployment name**. |
| `CODEX_API_VERSION` | Azure only: the required `api-version` query param. Leave unset for OpenAI/gateways. |
**Standard OpenAI:** leave `CODEX_BASE_URL` unset, set `CODEX_API_KEY` to an OpenAI `sk-…` key and `CODEX_MODEL` to a Codex/Responses-capable model.
**Azure OpenAI:**
```bash
CODEX_BASE_URL=https://.openai.azure.com/openai
CODEX_API_VERSION=2025-04-01-preview # required by Azure
CODEX_MODEL= # deployment, not the base model id
CODEX_API_KEY=
```
This registers a custom Codex model provider (`base_url` + `env_key=CODEX_API_KEY` + `query_params={api-version}` + `wire_api=responses`). The Codex CLI only supports the Responses wire API (it rejects `wire_api=chat` as "no longer supported"), so the protocol is fixed. If your Azure deployment requires the key in an `api-key` header rather than `Authorization: Bearer`, that needs an additional provider `http_headers`/`env_http_headers` entry — open an issue if you hit that.
## Usage
### Command Line
Run a task with Codex agent:
```bash
coder-eval run tasks/agents/codex_hello_world.yaml --type codex
```
Or override agent type for all tasks in an experiment:
```bash
coder-eval run experiments/model-comparison.yaml --type codex
```
### Task Definition (YAML)
Specify Codex in task YAML:
```yaml
agent:
type: codex
permission_mode: acceptEdits
allowed_tools:
- Bash
- Read
- Write
disallowed_tools:
- Edit
plugins:
- type: local
path: "$PLUGIN_PATH"
success_criteria:
- type: file_exists
path: "src/solution.py"
description: "Solution file must exist"
```
Valid `permission_mode` values:
- `default` - Standard access, requires approval on failure
- `acceptEdits` - Automatically accept file edits, no filesystem restrictions
- `plan` - Read-only sandbox, approval required for any changes
- `bypassPermissions` - Full access, no approvals needed
### Skills (SKILL.md)
CodexAgent supports SKILL.md files following the [Agent Skills open standard](https://agentskills.io/specification). Skills are discovered from:
1. **config.plugins** - Local plugins with `type: local` and `path` pointing to a skills directory
2. **plugin_tools_dir** parameter - Runtime plugin directory passed to `start()`
Skills are symlinked (or copied) to `.agents/skills/` where the Codex CLI auto-discovers them. Environment variables in plugin paths (`$VAR`, `${VAR}`) are expanded at runtime.
Example with environment variable:
```yaml
agent:
type: codex
plugins:
- type: local
path: "$SKILLS_PLUGIN_PATH"
```
Set environment variable:
```bash
export SKILLS_PLUGIN_PATH=~/uipath/uipath-claude-plugins/plugins/uipath-coded-agents
coder-eval run tasks/my_task.yaml
```
## Architecture
### Class Hierarchy
```
Agent (ABC)
└── CodexAgent
├── Codex SDK Client (openai_codex.Codex)
├── Thread Management (thread_start, turn.stream)
└── Streaming telemetry (commands, token usage, agent text)
```
### Key Methods
- **`start(working_directory)`** - Initialize Codex client and set working directory
- **`communicate(user_input, timeout, stream_callback)`** - Execute one turn with Codex
- **`stop()`** - Clean up resources
- **`get_state()`** - Return current agent state
- **`discard_pending_turn()`** - Rollback on failure
### TurnRecord Format
Each turn returns a `TurnRecord` with:
- `iteration` - Turn number
- `user_input` - The prompt sent
- `agent_output` - assembled from the streamed `agentMessage` deltas
- `commands` - `CommandTelemetry` for each shell command (`Bash`) and apply_patch file change (`Write`)
- `timestamp` - When the turn completed
- `duration_seconds` - Wall-clock execution time
- `token_usage` - input/output/cache-read token counts (from the SDK token-usage stream)
- `model_used` - the pinned `agent.model`, when set
## Implementation Details
### Timeout Handling
The agent uses a `ThreadedWatchdog` to enforce wall-clock timeouts. If a turn exceeds the deadline, a `TurnTimeoutError` is raised with a partial `TurnRecord` preserved in `pending_turn`.
### Error Recovery
On failure, the agent:
1. Sets `pending_turn` to a `crashed=True` TurnRecord with captured telemetry
2. Raises `AgentCrashError` or `TurnTimeoutError`
3. The orchestrator reads `pending_turn` and calls `discard_pending_turn()` to roll back state
### Permission and Tool Mapping
The agent maps `permission_mode` to the Codex SDK's `Sandbox`. The approval mode is **uniformly `deny_all`** for every mode — the trust boundary is the sandbox, which does vary by mode:
| `permission_mode` | `sandbox` | `approval_mode` |
|-------------------|-----------|-----------------|
| `bypassPermissions` | `full-access` | `deny_all` |
| `acceptEdits` | `workspace-write` | `deny_all` |
| `default` | `workspace-write` | `deny_all` |
| `plan` | `read-only` | `deny_all` |
`deny_all` means *run autonomously, never prompt, no server-side reviewer*: in-sandbox operations execute directly and only escalations beyond the sandbox are refused. Coder Eval uses it for every mode because the alternative (`auto_review`) adds a server-side reviewer that can spuriously return `declined` under gateway load.
`allowed_tools` / `disallowed_tools` are normalized (`Bash` → `shell`, `Write`/`Edit` → `apply_patch`, etc.) and passed as `enabled_tools` / `disabled_tools` in the thread `config`. **Note:** the Codex SDK does not currently enforce `disabled_tools`; do not rely on it as a security boundary (the agent logs a warning when it is set).
### Skills Discovery
The agent sets up SKILL.md files (Agent Skills open standard) in `.agents/skills/` directory:
1. Scans `config.plugins` for local plugins with `path` field
2. Checks `plugin_tools_dir` parameter passed to `start()`
3. Expands environment variables in paths (`$PLUGIN_PATH`, `${PLUGIN_PATH}`)
4. Symlinks skill directories (falls back to copying if symlink fails)
5. Codex CLI auto-discovers skills in `.agents/skills/`
### Async Integration
The Codex SDK is synchronous. The agent uses `_run_async()` helper to detect and await coroutines, preserving the async interface.
## Differences from Claude Code Agent
| Feature | Claude Code | Codex |
|---------|------------|-------|
| **SDK Type** | Subprocess (CLI via JSON generator) | Sync client (app-server subprocess) |
| **Command Tracking** | Full telemetry (tool name, params, duration) | Streamed telemetry: shell → `Bash`, apply_patch → `Write` |
| **Model Selection** | Direct via `--model` or config | `agent.model` pinned into `thread_start` |
| **System prompt** | `system_prompt` appended to the default prompt (SDK `claude_code` preset) | `system_prompt` passed as `developer_instructions` on top of the Codex base prompt |
| **Session Resume** | `--resume {session_id}` | Via thread ID |
| **Permissions** | `permission_mode` + `allowed_tools` | `permission_mode` → sandbox/approval + `allowed_tools`/`disallowed_tools` → thread config |
| **Tool Enforcement** | Not enforced by Coder Eval wrapper | `enabled_tools` honored; `disabled_tools` NOT enforced by the SDK |
| **`max_turns`** | Native SDK turn cap (assistant messages) | Visible-turn cap (tool calls), enforced on the notification pump |
| **Early stop** | Supported (cooperative `should_stop`, polled between messages) | Supported — polled after each streamed notification; the in-flight turn is interrupted best-effort |
Run-limit semantics per harness: [Run-Limit Parity](https://coder-eval.com/docs/agents/harness-parity).
## Known Limitations
1. **Tool-name collapse** - Codex reports shell tools (`Read`/`Grep`/`Bash`) all as shell commands, surfaced as `Bash` telemetry; name-keyed criteria that distinguish these tools aren't meaningful across agents.
2. **`skill_triggered` criterion** - Codex has no distinct `Skill` tool (it engages a skill by reading its files via shell), so the criterion detects Codex engagement from that file-read signal (a command referencing `skills//`) instead of a `Skill` tool call. The file-read signal is weaker than Claude's explicit invocation.
3. **`disallowed_tools`** - passed to the SDK but not enforced; not a security boundary.
4. **Authentication** - Requires `CODEX_API_KEY` in the environment (point it at whichever endpoint's key you use — OpenAI, gateway, or Azure); the agent calls `login_api_key` when a key is present. `OPENAI_API_KEY`/`AZURE_OPENAI_API_KEY` are NOT read.
5. **Model field** - `TurnRecord.model_used` reflects the pinned `agent.model`; the Codex `Turn` payload itself doesn't carry the resolved model.
6. **Skills with Windows paths** - Symlink creation may fail on Windows; agent falls back to copying (slower).
7. **No `system_prompt_mode`** - `replace` semantics are Claude-Code-only. `system_prompt` is always appended as `developer_instructions`; setting `system_prompt_mode` on a Codex `agent:` block is a validation error (unknown field).
## Migrating tasks that set `system_prompt`
`system_prompt` was previously **ignored** on Codex tasks — silently dropped, so the
task ran on Codex's base prompt alone. It is now forwarded as
`developer_instructions`, layered on top of that base prompt. Any Codex task setting
the field now actually receives those instructions, so **scores are not comparable
across this boundary**. Two things to check:
- A prompt written for Claude (naming `Read`/`Grep`/`Glob`, or Claude tool etiquette)
is now live on Codex, where those tool names don't exist.
- There is **no opt-out** (see Known Limitations #7). To restore the old behavior,
remove `system_prompt` from the Codex variant — otherwise re-baseline.
## Future Enhancements
- [ ] Implement session-based resume (thread ID tracking)
- [ ] Strengthen the Codex `skill_triggered` signal — it currently infers engagement from a file read, weaker than Claude's `Skill` tool call
- [ ] Capture the resolved model from the SDK (vs. the pinned config value)
## Testing
Run the included test tasks:
```bash
# Basic functionality test
coder-eval run tasks/agents/codex_hello_world.yaml
# Tool restriction test (verifies disallowed_tools enforcement)
coder-eval run tasks/agents/codex_disallowed_tools_test.yaml
# Skills discovery test (requires PLUGIN_PATH environment variable)
export PLUGIN_PATH=~/path/to/skills
coder-eval run tasks/agents/codex_skills_test.yaml
```
Example unit test to verify agent setup:
```python
import pytest
from coder_eval.models import AgentKind, AgentConfig
from coder_eval.agents.codex_agent import CodexAgent
from coder_eval.agent import AgentState
def test_codex_agent_initialization():
"""Verify CodexAgent can be instantiated with valid config."""
config = AgentConfig(
type=AgentKind.CODEX,
permission_mode="acceptEdits",
allowed_tools=["Bash", "Read", "Write"],
)
agent = CodexAgent(config)
assert agent.get_state() == AgentState.WORKING
assert agent.config.type == AgentKind.CODEX
def test_tool_name_mapping():
"""Verify Claude Code tool names map to Codex SDK names."""
from coder_eval.agents.codex_agent import _CLAUDE_TO_CODEX_TOOL_MAP
assert _CLAUDE_TO_CODEX_TOOL_MAP["Bash"] == "shell"
assert _CLAUDE_TO_CODEX_TOOL_MAP["Write"] == "apply_patch"
assert _CLAUDE_TO_CODEX_TOOL_MAP["Edit"] == "apply_patch"
assert _CLAUDE_TO_CODEX_TOOL_MAP["Read"] == "shell"
def test_permission_mode_mapping():
"""Verify permission_mode maps to a sandbox; approval is uniformly deny_all."""
from coder_eval.agents.codex_agent import (
_CODEX_APPROVAL_MODE,
_PERMISSION_MODE_TO_SANDBOX,
)
assert _PERMISSION_MODE_TO_SANDBOX["acceptEdits"] == "workspace-write"
assert _PERMISSION_MODE_TO_SANDBOX["plan"] == "read-only"
# Approval is the same for every permission mode — no per-mode mapping.
assert _CODEX_APPROVAL_MODE == "deny_all"
```
## References
- [Codex SDK Documentation](https://developers.openai.com/codex/sdk)
- [Codex CLI Guide](https://developers.openai.com/codex/cli)
- [Codex GitHub Repository](https://github.com/openai/codex)
---
# Running Google Antigravity (Gemini) in Coder Eval
## Overview
Coder Eval can run Google's **Antigravity** agent — powered by **Gemini** — as the
agent under evaluation. Set `agent.type: antigravity` in a task and the rest of the
framework (sandbox, scoring, telemetry, reports) works unchanged.
Under the hood `AntigravityAgent` drives the Antigravity SDK's **local harness**
(the `localharness` binary bundled in the wheel) rather than the branded `agy` CLI
or the remote Interactions API. The local harness is the only surface that can (a)
authenticate headlessly with an API key and (b) make edits land in the sandbox
working directory — both required for an unattended eval.
## Setup
### 1. Install the Antigravity SDK
```bash
pip install 'coder-eval[antigravity]'
```
This pulls in `google-antigravity` (pinned to `0.1.7`), whose wheel bundles the
platform `localharness` binary. As with the other agents the SDK is imported lazily
— a base install without the extra still runs end-to-end; Antigravity tasks fail at
dispatch with a clear hint to install the extra.
### 2. Authentication
Antigravity authenticates against the **Gemini Developer API** with a single
credential:
```bash
GEMINI_API_KEY=
```
Set it in `.env` (or the environment). That is the *only* credential Antigravity
reads — there is **no base-URL, project, or region override** for this agent
(unlike Codex's `CODEX_BASE_URL` / Azure routing). If `GEMINI_API_KEY` is unset the
SDK raises a clear error on first use.
> The `--backend` flag (`direct` / `bedrock`) governs *Claude* routing only; it has
> no effect on the Antigravity agent.
## Usage
### Command line
```bash
coder-eval run tasks/agents/antigravity_hello_world.yaml --type antigravity
```
Or override the agent type for every task in an experiment:
```bash
coder-eval run experiments/model-comparison.yaml --type antigravity
```
### Task definition (YAML)
```yaml
agent:
type: antigravity
model: gemini-3.1-pro-preview # optional; see "Model selection" below
thinking_level: medium # minimal | low | medium | high (default: medium)
plugins:
- type: local
path: "$SKILLS_PLUGIN_PATH" # a directory of skills (SKILL.md), env-expanded
run_limits:
max_turns: 5
task_timeout: 360
turn_timeout: 300
success_criteria:
- type: file_exists
path: "hello.py"
description: "hello.py must be created"
```
Two runnable examples ship in the repo:
- `tasks/agents/antigravity_hello_world.yaml` — `tempdir` driver
- `tasks/agents/antigravity_hello_world_docker.yaml` — `docker` driver
### Model selection
The resolved model is the first of:
1. `agent.model` in the task YAML
2. `ANTIGRAVITY_MODEL` in the environment
3. the built-in default, **`gemini-3.5-flash`**
> **Note:** the shipped example tasks pin `gemini-3.1-pro-preview`. Pin `agent.model`
> explicitly in any task you care about reproducing — don't rely on the built-in
> default, which tracks the current recommended coding model and may change.
### `thinking_level`
Antigravity exposes a `thinking_level` field (`minimal` / `low` / `medium` /
`high`, default `medium`) that maps to Gemini's thinking budget. This is
Antigravity-specific — Claude Code and Codex don't take this field. Thinking tokens
are billed as **output** tokens (see [Telemetry](#telemetry)).
### `system_prompt`
`agent.system_prompt` is passed to the SDK as `system_instructions`, whose string
shorthand maps to `TemplatedSystemInstructions` — a named section **appended** to
the harness's default system instructions, never a replacement. This matches the
append-only semantics of the shared config field across agents (Claude Code appends
via the `claude_code` preset; Codex via `developer_instructions`).
### Skills (SKILL.md)
Antigravity supports [Agent Skills](https://agentskills.io/specification)
(`SKILL.md`) natively. Skill directories are discovered from:
1. `agent.plugins` entries with `type: local` and a `path` (env vars in the path are
expanded at runtime), and
2. the runtime plugin directory passed to `start()`.
For each source, the harness is handed whichever of `/skills` or ``
directly contains subdirectories with a `SKILL.md`. Unlike Codex — which symlinks
skills into `.agents/skills/` — Antigravity is given the search-path roots directly
via the SDK's `skills_paths`, and those roots are also added to the harness
`workspaces` allowlist (otherwise the agent would find a skill but be denied the
`SKILL.md` read as out-of-workspace). The agent logs a loud warning if a skills path
can't be resolved or if zero skills are discovered.
## Permissions & tools — important differences
**Antigravity ignores `permission_mode`, `allowed_tools`, and `disallowed_tools`.**
The local harness runs in a single unconditional mode: every tool call (including
`run_command`) is approved via an allow-all policy, and file tools are restricted to
the configured `workspaces` (the sandbox working directory plus any skill roots).
The trust boundary for an Antigravity run is therefore the **sandbox**, not the
agent config. Run untrusted tasks under the [Docker driver](https://coder-eval.com/docs/docker-isolation);
the `tempdir` driver is not a security boundary. This mirrors the reality that the
`bypassPermissions`-equivalent behavior is always on for this backend.
Those inherited fields still exist on the config for schema uniformity but have no
runtime effect here — don't rely on them to gate Antigravity.
## Telemetry
Each `communicate()` call is one logical turn; the standard `TurnRecord` is built by
the shared `EventCollector`, so Antigravity runs report the same per-turn structure
as every other agent.
- **Tool-name normalization.** Antigravity's built-in tool names are mapped to the
canonical Claude-style names so cross-agent criteria work: `run_command` → `Bash`,
`create_file` → `Write`, `edit_file` → `Edit`, `view_file` → `Read`,
`search_directory` → `Grep`, `find_file` → `Glob`, `list_directory` → `LS`,
`start_subagent` → `Task`, `search_web` → `WebSearch`. Argument keys are also
normalized (e.g. `command_line` → `command`) so `command_executed` criteria key on
the same params across agents.
- **Tokens.** Gemini usage maps to Coder Eval's four buckets: uncached input, cache
read (`cached_content_token_count`), output, and **`cache_creation` is always 0**
(Gemini bills no separate cache-write). Thinking tokens are folded into **output**.
Per-generation usage is cut into `AssistantMessage`s that sum exactly to the turn
total, so there is typically no reconciliation residual.
- **Commands.** Each tool call is captured as `CommandTelemetry` with status, an
untruncated `result_summary`, error message, and duration. Harness-appended result
fields (`exit_code`, `combined_output`, `diff_block`, `stdout`/`stderr`, …) are
stripped from the recorded `parameters` so tool *output* never leaks into the
recorded call — which also keeps it from false-positiving a `skill_triggered`
substring match.
## Known limitations
1. **No endpoint routing.** Only `GEMINI_API_KEY` + `ANTIGRAVITY_MODEL` are read —
there is no base-URL, project, region, or gateway override.
2. **Default-model drift.** The runtime fallback (`gemini-3.5-flash`) may differ from
what a given release's docs or example tasks pin; always set `agent.model`
explicitly for reproducible runs.
3. **`kill_sync()` is best-effort.** The SDK's cancel/disconnect are async-only, so
the watchdog's synchronous kill only flips agent state to `ERROR`; real teardown
happens on the subsequent async `stop()`.
4. **`permission_mode` does not confine the harness.** Every mode runs
`policy.allow_all()`; coder_eval's write boundary is the sandbox driver, and a
headless eval has no human to approve anything.
5. **`allowed_tools` / `disallowed_tools` are not read.** The harness runs with its
full builtin tool set, so an Antigravity run has tools (web search, subagents,
URL fetch) that the same task file denies on Claude Code and Codex.
6. **`max_turns` counts visible turns.** One `communicate()` is a single SDK turn here,
so the cap counts resolved tool calls instead, enforced on the step loop. See
[Run-Limit Parity](https://coder-eval.com/docs/agents/harness-parity).
7. **Shell commands over ~10s are moved to the background.** The localharness has a
10-second maximum synchronous wait; past it the command becomes a background task
and the model gets a task id, not a result. The turn polls for that result instead
of finalizing on an idle step stream, so slow work does complete — but the wait is
bounded by 80% of `turn_timeout`, and a job that outlives it is force-closed as
`result_status: unknown` and graded as an ordinary low score rather than a timeout.
Measured in [Run-Limit Parity](https://coder-eval.com/docs/agents/harness-parity).
## Running in Docker
The `docker` driver works the same as for other agents (see
[Docker Isolation](https://coder-eval.com/docs/docker-isolation)). The `localharness` binary ships inside
the image via the `[antigravity]` extra, and `GEMINI_API_KEY` + `ANTIGRAVITY_MODEL`
are on the container env passthrough allowlist, so they are forwarded automatically.
```bash
coder-eval run tasks/agents/antigravity_hello_world_docker.yaml
```
## References
- [Agent Skills specification](https://agentskills.io/specification)
- [Codex Agent Guide](https://coder-eval.com/docs/agents/codex) — the sibling third-party-agent guide
- [Claude Code Agent](https://coder-eval.com/docs/agents/claude-code) — the default agent
- [Extending Coder Eval](https://coder-eval.com/docs/extending) — how agents register via the plugin SPI
---
# Running OpenCode in Coder Eval
## Overview
[OpenCode](https://opencode.ai) is an open-source terminal coding agent. Coder Eval
drives it **non-interactively**:
```bash
opencode run --format json -m --dir --auto --pure ""
```
`--format json` streams **newline-delimited JSON events** on stdout, one event per
line. `OpenCodeAgent` reduces that stream into the standardized event protocol
(`AgentStart` / `TurnStart` / `ToolStart` / `ToolEnd` / `TurnEnd` / `AgentEnd`) and
lets `EventCollector` build the `TurnRecord`, exactly like every other harness.
Because OpenCode is model-agnostic, this is the cheapest way to evaluate a broad
set of open-weight models (DeepSeek, Kimi, GLM, …) through a single agent.
## Setup
### 1. Install the OpenCode CLI
OpenCode is a **Node** CLI, not a Python package:
```bash
npm install -g opencode-ai
opencode --version
```
The `coder-eval[opencode]` extra exists for symmetry with the other harnesses and
carries **no Python dependencies** — the agent shells out to the binary above and
imports no third-party package:
```bash
uv sync --extra opencode # documents the opt-in; installs no extra packages
```
> The `opencode-ai` package on **PyPI** is an HTTP client for `opencode serve`, a
> different integration surface than the CLI this harness drives. You do not need
> it.
If the binary is missing, the task fails at `start()` with an actionable error
naming the install command, rather than failing obscurely mid-run.
### 2. Authentication
OpenCode resolves credentials itself, per provider. Either log in once:
```bash
opencode auth login
```
…or export the provider key, which Coder Eval forwards into the subprocess
environment (it also picks up keys from `.env`, since `config.py` calls
`load_dotenv(override=True)`):
```bash
export OPENROUTER_API_KEY="sk-or-..." # OpenRouter (any model)
export DEEPSEEK_API_KEY="sk-..." # DeepSeek first-party
```
Check what a given model id resolves to with:
```bash
opencode models | grep
```
## Usage
### Command line
```bash
uv run coder-eval run tasks/opencode_smoke_test.yaml
uv run coder-eval run tasks/my_task.yaml -D agent.type=opencode -D agent.model=openrouter/deepseek/deepseek-v4-pro
```
### Task definition (YAML)
```yaml
agent:
type: "opencode"
# provider/model, exactly as `opencode models` prints it.
model: "openrouter/deepseek/deepseek-v4-pro"
permission_mode: "acceptEdits"
variant: "high" # optional: provider reasoning effort
pure: true # optional (default): run with --pure, no host plugins
```
### Model selection
`agent.model` is passed through verbatim to `-m`, so it must be OpenCode's
`provider/model` form. The provider prefix decides which credential is used:
| `agent.model` | Provider | Credential |
|---|---|---|
| `openrouter/deepseek/deepseek-v4-pro` | OpenRouter | `OPENROUTER_API_KEY` |
| `deepseek/deepseek-v4-pro` | DeepSeek direct | `DEEPSEEK_API_KEY` |
OpenCode speaks OpenRouter natively, so it does **not** need the LiteLLM proxy —
that shim exists to translate Anthropic ↔ OpenAI for the Claude Code SDK.
### `variant`
Provider-specific reasoning effort (`minimal` / `high` / `max`, provider
dependent), forwarded as `--variant`. Omit to take the provider default.
### `pure`
Defaults to `true`, forwarding `--pure` so the sandbox is isolated from host-level
OpenCode plugin configuration. This mirrors the rationale behind the Claude agent's
`setting_sources: []`. Set to `false` to load host plugins deliberately.
`--pure` skips external *plugins*; it does **not** skip configured skill paths, so
skill injection (below) works under the default `pure: true`.
### `plugins` — skill injection
A `plugins:` entry is a Claude-plugin root, which is how a task ships the skills
under test:
```yaml
agent:
plugins:
- type: "local"
path: "$SKILLS_REPO_PATH"
```
OpenCode has no plugin knob, but it does load skills from `skills.paths` in its
config, so each local plugin root is mapped to that:
1. `/.claude-plugin/plugin.json` is read for its `skills` field (a string or
a list, each relative to the root); Claude Code reads the same field, so one
`plugins:` line means the same thing on both harnesses.
2. Absent a manifest, the convention default `/skills` is used.
3. A path that is already a bare skills directory (`//SKILL.md`, no
`skills/` subdir) is used as-is.
The resulting directories are passed through `OPENCODE_CONFIG_CONTENT`, which the
CLI merges as a final local-scope config layer. That seam was chosen over writing
`/.opencode/skills/` because it writes nothing into the sandbox that is
later preserved as a run artifact and inspected by file criteria, and because it
does not depend on how the CLI resolves a project root from `--dir`. An inherited
`OPENCODE_CONFIG_CONTENT` is merged into, not clobbered. With no `plugins:` entry
the variable is left exactly as inherited.
> A plugin root is mapped to its *skills subdirectory*, never to the root itself
> when one exists. `skills.paths` is scanned **recursively**, and a plugin root can
> contain a self-referential symlink (`UiPath/skills` has `plugins/uipath -> ..`),
> which resolves skills through an arbitrary path and silently drops duplicate names.
Verify what the agent will actually see, using the same environment it builds:
```bash
opencode debug skill --pure # lists every skill the CLI can load
```
Every way this can resolve to nothing — an unset `$SKILLS_REPO_PATH`, a missing
directory, a root with no `SKILL.md` under it — is logged as a warning at `start()`,
and the resolved paths are recorded per task under `environment_info`
(`opencode_skill_paths`). A run that quietly measures the bare model instead of the
skills under test otherwise looks entirely normal.
## Permissions
Every `permission_mode` except `plan` passes `--auto`, auto-approving tool use.
This is required for unattended evaluation — without it OpenCode blocks on an
interactive approval prompt and the turn runs to its timeout. Use
`permission_mode: plan` when you explicitly want approvals withheld.
## Telemetry
Mapping from the CLI's event vocabulary onto `TurnRecord`:
| OpenCode event | Becomes |
|---|---|
| `step_start` | `TurnStartEvent` (one inner turn) |
| `text` | `TextChunkEvent` + `agent_output` |
| `tool_use` | `ToolStartEvent` + `ToolEndEvent` (one terminal event carries both) |
| `step_finish` | `TurnEndEvent` + per-step tokens/cost, one `AssistantMessage` |
| `error` | `AgentCrashError` with the partial turn preserved |
Token buckets come from `step_finish.tokens`. Two conventions for `tokens.input`
exist in the wild, and the stream's own `total` arbitrates **per step**:
- **flat** (what the current CLI emits, verified live —
`7966 = 6796 + 128 + 18 + 1024` exactly): `input` already *is* the fresh slice,
and `total = input + output + reasoning + cache.read + cache.write`;
- **nested** (the OpenAI `prompt_tokens` convention): cached tokens are counted
inside `input`, `total = input + output + reasoning`, so the fresh slice is
`input - cache.read - cache.write`.
With no cache traffic the two agree. With no usable `total` the flat reading is
taken — logged as a warning when cache traffic is present, since the convention
then cannot be verified. A `total` matching **neither** also warns (once per
turn) that the bucket mapping may no longer match the CLI — so a drifting schema
is visible in `task.log` instead of quietly mis-costing every run. Reasoning
tokens are folded into `output_tokens` (they bill at the output rate) while
remaining visible as `reasoning_tokens` per message. This keeps the
reconciliation invariant exact: summing the four buckets across
`TurnRecord.messages` equals `token_usage`.
Real per-call cost rides on `step_finish.cost` and lands on
`token_usage.total_cost_usd`, so runs are costed from the provider's own
accounting rather than the static rate card. The rate card
(`calculate_cost` over the captured buckets) fills two gaps so the run total
never books tokens with no money: a stream that reports **no** cost at all (a
provider or auth mode that omits it, or a turn that died before its first
`step_finish`), and a stream that reports **`cost: 0`** for tokens the rate
card prices above zero — OpenCode reports 0 when its own model registry has no
price for the model, or under subscription-style auth, and neither means the
tokens were free (the fallback logs a warning naming the substituted amount). A
*non-zero* cost the CLI reported always wins, and a genuinely free model still
resolves to $0 because its rate entry is absent or all-zero.
Tool names are normalized to the canonical (Claude) vocabulary on capture —
`bash` → `Bash`, `read` → `Read`, `write`/`edit`/`patch` → `Write`/`Edit`, and so
on; an unmapped tool keeps its own name. This is what lets one
`command_executed` criterion (which filters on `tool_name` and reads a `Bash`
call's `command` parameter) score identically whether the run used Claude, Codex
or OpenCode.
Tool **argument keys** are normalized the same way, because `command_executed`
serializes `parameters` to JSON for every tool but `Bash` — so a criterion like
`{type: command_executed, tool_name: Read, command_pattern: 'file_path.*app\.py'}`
would otherwise match on Claude and score 0 on OpenCode for identical behaviour:
| Canonical tool | OpenCode key | Recorded as |
|---|---|---|
| `Read` / `Write` / `Edit` | `path` (or `filePath`) | `file_path` |
| `Edit` | `oldString` / `newString` / `replaceAll` | `old_string` / `new_string` / `replace_all` |
| `Skill` | `name` | `skill` |
Both file-path spellings are accepted because the CLI has moved between versions
(a 2026-08-13 capture emitted `filePath`; current builds register `path`).
`Bash`'s `command` and the search tools' `path` already match Claude's names and
pass through untouched, as does every unlisted key.
> **The tool vocabulary varies by MODEL, not just by harness.** OpenCode exposes a
> provider-specific tool set: a GPT-family model edits via `apply_patch` where
> DeepSeek uses `write`/`edit`. `apply_patch` is therefore mapped to `Write` (as
> `codex_agent` does), so one `tool_name: Write` criterion reads the same on
> either. Its argument is a patch envelope (`patchText`), not a file path, so a
> `command_pattern` written against `file_path` will not match it — assert on
> `tool_name` alone, or on the resulting file with `file_exists`/`file_contains`.
> These event names are the CLI's own compact vocabulary. They are **not** the
> `session.next.*` names in the OpenAPI schema served by `opencode serve` — that
> describes the HTTP/SSE surface and does not apply here.
Drift is crashed, not scored: a turn whose CLI exits cleanly but which captured
**no token telemetry** is failed rather than reported as a clean empty success.
File-based criteria could otherwise still pass on whatever the agent did, giving
a SUCCESS that silently vanishes from every token aggregate — and whose
`run_limits.max_total_tokens` / `max_usd` gates could never trip no matter what
the run really billed. Two shapes reach it:
- the stream contained **no recognized events** (an upgrade renamed the
vocabulary) — the error names the unrecognized event types it saw;
- events were recognized but **every finished step carried no usable token
counts** (a provider or auth mode that omits `tokens`) — the error reports the
finished-step count and whether cost was present.
Intentional cuts (`should_stop`, `max_turns`) are exempt: both can land before
the first event, or between a step's start and its `step_finish`.
For a provider or auth mode that genuinely reports no usage — where failing every
turn would make the harness unusable rather than merely imprecise — set
`require_token_telemetry: false` (or `-D agent.require_token_telemetry=false`).
The turn is then warned about and scored. This relaxes only the missing-token
arm: a stream with **no recognized events** still fails, since no provider quirk
explains a renamed event vocabulary.
## Running in Docker
**Not supported yet — use the default `tempdir` driver.** Unlike the other
built-in agents, `sandbox: {driver: docker}` does not work with
`agent: {type: opencode}`, and the failure is loud rather than silent:
`start()` finds no `opencode` on PATH inside the container and every task dies
with the install hint, which you cannot act on because that PATH lives in an
image you did not build.
Two things are missing, both deliberate rather than overlooked:
- **The CLI is not in the image.** `docker/Dockerfile` bakes in `claude-code`
(pinned) plus the `codex` and `antigravity` extras. OpenCode is a Node CLI
installed with `npm install -g opencode-ai`, so shipping it means adding a
pinned version that travels with the coder_eval release tag the way
`CLAUDE_CODE_VERSION` does — a release-process decision, not a one-line edit.
(Node 22 is already present in the image, so the change itself is small.)
- **No credentials would reach it.** The docker driver forwards host environment
variables through an explicit allowlist (`SandboxConfig.env_passthrough`),
which carries per-harness blocks for Codex and Antigravity but none for
OpenCode — so `OPENROUTER_API_KEY` and friends are not passed through, and
`opencode auth login`'s credential file is not mounted. Even a custom image
with the CLI baked in would authenticate against nothing.
Until both land, run OpenCode tasks under `tempdir` (the default) on a host that
has the CLI and its provider credentials. If you need container isolation now,
build your own image from `docker/Dockerfile` with the `npm install -g` line
added and pass the credentials via `sandbox.env_passthrough_extra`.
## Known limitations
- **`allowed_tools` / `disallowed_tools` / `system_prompt` / `system_prompt_file`
are not enforced.** The CLI exposes no equivalent knob, so these are
dropped — `start()` logs a warning naming each one it saw (`experiments/default.yaml`
sets `allowed_tools` on every task, so expect it on a default run). Do not rely on
them as a boundary here.
- **Only the *skills* half of a `plugins:` entry is honored** (see below). A Claude
plugin's agents, hooks, commands and MCP servers have no OpenCode equivalent and
are still dropped.
- **`max_turns` counts OpenCode's native steps.** One step = one assistant
generation (`step_start`/`step_finish`) and may carry several tool calls;
`max_turns: N` allows N complete steps, then the run finalizes cleanly as
`max_turns_exhausted`. This is the claude-code-style native unit, not the
visible-turn unit Codex/Antigravity use — see
[Run-Limit Parity](https://coder-eval.com/docs/agents/harness-parity) before holding `max_turns` constant
across harnesses.
- **The `docker` sandbox driver is unsupported.** The CLI is not in the image and
no OpenCode credentials are in the `env_passthrough` allowlist — see
[Running in Docker](#running-in-docker) for the workaround and what it would
take to close.
- **No sub-agent attribution.** OpenCode's CLI stream does not expose nested agent
generations, so per-sub-agent token grouping (available for Claude and Codex) is
not derivable.
- **Cooperative stop is at event granularity.** `should_stop` is polled between
events and honored by terminating the CLI, so `stop_early` works, but the cut
lands on an event boundary rather than mid-tool.
- **Pipe and process teardown.** `opencode run` leaves a local server child
holding the inherited stdout/stderr pipes, so EOF never arrives on its own. The
agent races each read against process exit, bounds the post-exit drain, and
bounds the final reap by the turn deadline (a CLI that closes its stream but
never exits is cut as a timeout/crash, not waited out). stderr gets its own
concurrent reader from the moment the CLI starts — draining it only afterwards
would let a full stderr pipe block the child mid-write and stall stdout with it.
Each invocation runs in its own process group (`start_new_session`), and
`kill()` / `kill_sync()` / `stop()` sweep that group with SIGKILL, so the server
child is reaped rather than leaked across a batch; OpenCode persists sessions on
disk, so `--session` continuity survives the sweep.
## Troubleshooting
**`No endpoints available matching your guardrail restrictions and data policy`**
— an OpenRouter *account* setting, not a Coder Eval problem. The model's serving
providers are all excluded by your account's privacy/guardrail configuration.
Verify independently with a direct API call, then adjust at
[openrouter.ai/settings/privacy](https://openrouter.ai/settings/privacy).
**Task fails with `captured zero token telemetry`** — the CLI exited cleanly but
the turn booked no tokens, so it would have scored with nothing in any aggregate;
the harness fails it instead. Check the raw stream with
`opencode run --format json ... > raw.jsonl`:
- if the error says *no recognized events*, compare the `type` values against the
table above — an OpenCode upgrade that renames them needs a matching harness
update;
- if it reports finished steps with no usable token counts, inspect a
`step_finish` payload's `tokens` object — a provider or auth mode that omits
usage, or a renamed bucket, produces this.
## References
- [OpenCode docs](https://opencode.ai/docs/) · [CLI reference](https://opencode.ai/docs/cli/)
- [Extending Coder Eval](https://coder-eval.com/docs/extending) — the agent plugin SPI
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide)
---
# Run-Limit Parity
One task file, run on any harness, must be the same task. `run_limits.max_turns`
was the field that broke that promise hardest: Claude Code enforced it, and Codex and
Antigravity accepted it and never read it, so `max_turns: 6` ran capped on one
backend and unbounded on the other two.
This page is the contract for what each run limit means per harness, plus the shared
`agent` fields whose meaning still differs across them.
## The table
| Limit | claude-code | codex | antigravity | opencode |
|---|---|---|---|---|
| `run_limits.max_turns` | native SDK cap (agent-loop turns) | visible-turn cap (resolved tool calls) | visible-turn cap (resolved tool calls) | native step cap (the CLI's own agent-loop steps) |
| `run_limits.turn_timeout` | watchdog, SIGKILL on the CLI subprocess | watchdog + cooperative interrupt | watchdog, plus an earlier internal poll deadline at 80% of it (see below) | deadline enforced in-loop and on the final reap; SIGTERM→SIGKILL on the CLI's whole process group |
| `run_limits.task_timeout` | orchestrator-level, agent-agnostic | orchestrator-level, agent-agnostic | orchestrator-level, agent-agnostic | orchestrator-level, agent-agnostic |
| `run_limits.stop_early` | cooperative `should_stop` | cooperative `should_stop` | cooperative `should_stop` | cooperative `should_stop` (event granularity) |
## `max_turns` counts visible turns on Codex and Antigravity
A "visible turn" is one entry in the run's timeline: one resolved tool call. It is
the unit `reports_stats.visible_turn_count` reports and the unit that lands in
`TurnRecord.commands`. Both backends count it live off the shared
`EventCollector.visible_turn_count`, so one `max_turns` value means one thing on
both.
They need their own counter because a native one would be meaningless: Codex and
Antigravity each deliver exactly **one SDK turn per `communicate()` call**, so an
SDK-level cap would clamp at 1 no matter what the task asked for.
The cap is enforced on the same loop boundary as the cooperative early stop: the
step or notification that reaches the cap is processed whole, and the next one is
never pulled. The in-flight turn is then cancelled server-side (best effort) so
the cap actually stops spend. A run cut this way finalizes cleanly as
`max_turns_exhausted` — it is not a crash, and it is not retried.
**claude-code keeps its native SDK cap.** That is a real, honored cap, so it is
left alone rather than reimplemented in a different unit. Its unit is the SDK's own
agent-loop turn, which absorbs an arbitrary number of *parallel* tool calls, so the
same number bounds very different amounts of work: under a prompt that encourages
batching, a cap of N here permits many more than N tool calls, where it buys exactly
N on the other two.
**OpenCode also keeps a native unit — its stream's own steps.** Unlike Codex and
Antigravity, `opencode run` executes a real multi-step agent loop per invocation
and streams it (`step_start` / `step_finish`), so the natural agent-loop unit
exists and is honored: `max_turns: N` allows N complete steps and cuts the run
when step N+1 begins, with the completed steps' tokens intact. A step is one
assistant generation and may carry several tool calls — so, as with claude-code,
the same number is a looser tool-call budget than on the visible-turn backends.
**So holding `max_turns` constant across harnesses does not hold the budget
constant.** If you are A/B-ing across backends and the cap is close to binding, that
is the number to distrust.
### What a capped run looks like
The signals a capped run leaves behind, on every backend:
- Criteria are still checked against whatever the agent produced, because the cap is
an ordinary end-of-run rather than an error. So a capped run that nonetheless
satisfies its criteria finishes as `SUCCESS`; one that does not finishes as
`MAX_TURNS_EXHAUSTED` (reporting category `failed`, icon `M`). Never `ERROR`,
and never retried.
- `max_turns_exhausted: true` on the task record.
- On Codex and Antigravity, the count of *resolved* tool calls the model itself
issued equals the cap. Two things can add a further *recorded* command, and
neither means the cap leaked:
- A tool call already in flight when the cap fires is force-closed and recorded
with `result_status: unknown` rather than dropped, so the trajectory shows what
was interrupted.
- On Codex, a sub-agent's inner tool calls are recovered from its rollout after
the pump stops, so the child's work and its tokens still reach the record. The
cap bounds what the model was allowed to do, not what the record may explain.
## What a timeout looks like
On Claude Code and Codex a `turn_timeout` breach is a *failure*: the watchdog fires
at the deadline, the partial turn is preserved on `pending_turn`, and the turn is
marked `crashed`.
Antigravity stops earlier and more gently, for the reason in the next section.
## Antigravity backgrounds anything over 10 seconds
The Antigravity localharness has a **10-second maximum synchronous wait** for shell
commands. Past it, the harness moves the command to a background task and hands the
model a task id instead of a result. That is harness behavior, not something
coder_eval configures.
What coder_eval does about it: the turn polls for the backgrounded result rather
than finalizing the moment the step stream goes idle, so slow work does finish and
its real exit code reaches the model. Without that poll, a command over the 10s
boundary left the tool call unresolved and the turn was graded on work that had not
happened yet.
The wait is bounded by **80% of `turn_timeout`** (or 120 five-second cycles when the
task sets no timeout), not by `turn_timeout` itself. A job that outlives that bound
is force-closed as unresolved and the turn is graded on everything else, where
Claude Code and Codex instead raise a turn timeout and mark the turn crashed.
So the residual divergence is the terminal signal, not whether slow work completes:
a long `npm install` or build runs to completion here the way it does on the other
two, but a command that never finishes reads as an ordinary low score rather than a
timeout.
## Timeouts are not turn caps
A timeout is a *failure* (partial turn captured, error status); the turn cap is a
*clean stop*. Conflating them is the mistake this page exists to prevent: a task
whose cap fires should not look like a task whose harness hung.
## `agent.plugins[].path` accepts different depths per harness
Not a run limit, but the same promise: one task file, three harnesses, same meaning.
This field breaks it silently.
| | claude-code | codex | antigravity |
|---|---|---|---|
| `/skills//SKILL.md` (plugin root) | **required** | accepted | accepted |
| `//SKILL.md` (bare skills dir) | **loads nothing** | accepted | accepted |
claude-code hands the value to the SDK as a *plugin directory*, and a plugin's skills
live at `/skills//SKILL.md`. Point it at the directory that directly
parents the skill directories and no skill loads. Codex
(`codex_agent._setup_skills`) and Antigravity (`antigravity_agent._resolve_skills_paths`)
both scan **both** layouts and take whichever actually holds a `/SKILL.md`.
So `.claude/skills` works on two backends out of three and fails on the third — and
fails without an error. The agent simply is not offered the skill, every positive row
of an activation suite scores 0, and the suite reports recall 0.0. That is
indistinguishable from a skill that never triggers, which is the finding such a suite
exists to produce. It shipped in six documentation surfaces at once for exactly this
reason.
Probe it — but **read the namespace, not the presence**. Claude Code discovers a
project's own `./.claude/skills/` natively, independent of `--plugin-dir`, so run
from a repo root and BOTH commands list the skill: the deeper one only looks
correct. The plugin loaded iff the name carries the root's prefix.
```bash
# Run from a directory that is NOT the skill's own repo root.
claude --plugin-dir /path/to/root # lists `root:` <- plugin loaded
claude --plugin-dir /path/to/root/skills # lists nothing <- loaded nothing
```
A bare `` with no prefix is project discovery, not your plugin.
**Write the plugin root.** It is correct on all three, so there is never a reason to
write the deeper form. For `.claude/skills/my-skill/SKILL.md` that is `.claude`.
Note what else that pulls in: a plugin root loads the **whole** plugin, so an
`agents/`, `commands/` or `hooks/` directory sitting beside `skills/` becomes visible
to the evaluated agent as well. Verified — a root holding `skills/probe-beta/`,
`agents/probe-subagent.md` and `commands/probe-cmd.md` offers all three as
`root:probe-beta`, `root:probe-subagent` and `root:probe-cmd`. Pointing a suite at a
repo's `.claude` therefore hands the agent every project subagent, which can answer a
request the skill was supposed to answer. Stage a minimal root when the suite must
isolate one skill.
`SKILL_SOURCE_PATH` — the variable `/coder-eval:check-skill` emits — is held to the
plugin-root shape by lint rule CE045. The rule keys on that variable name only; it is
**not** a statement that other variables may use the deeper form. `$PLUGIN_PATH`, for
one, feeds `experiments/plugin-comparison.yaml`, whose default agent is claude-code,
so the same requirement applies there and is unlinted.
## Reproducing
`tasks/run_limits/` holds one fixture per limit: `max_turns_cap.yaml` asks for more
sequential work than its cap allows, and `turn_timeout.yaml` runs a command that
outlives its watchdog. Run either with `--type claude-code` / `--type codex` /
`--type antigravity` / `--type opencode` to check a backend against the contract
above.
## Related
- [Claude Code](https://coder-eval.com/docs/agents/claude-code) · [Codex](https://coder-eval.com/docs/agents/codex) · [Antigravity](https://coder-eval.com/docs/agents/antigravity) · [OpenCode](https://coder-eval.com/docs/agents/opencode)
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) — the full `run_limits` schema
---
# A/B Experiment Guide
How to run the same tasks across multiple configuration variants ("arms") and
compare them — model A vs. model B, skill on vs. off, prompt X vs. prompt Y.
The experiment layer sits **above** the single-task pipeline as a pre-processing
config resolver. It expands `tasks × variants` into fully-resolved tasks, runs
them through the normal batch path, and emits a cross-variant report. No changes
to the orchestrator are involved.
## Table of Contents
- [Quick Start](#quick-start)
- [Experiment YAML Structure](#experiment-yaml-structure)
- [The 5-Layer Config Merge](#the-5-layer-config-merge)
- [What a Variant Can Override](#what-a-variant-can-override)
- [Recipe: A/B a Skill](#recipe-ab-a-skill)
- [Recipe: A/B a Model](#recipe-ab-a-model)
- [Recipe: A/B a Prompt](#recipe-ab-a-prompt)
- [Recipe: Smoke vs. e2e Flavors (Early Stop)](#recipe-smoke-vs-e2e-flavors-early-stop)
- [Replicates (Statistical Power)](#replicates-statistical-power)
- [Measuring the Difference](#measuring-the-difference)
- [CLI Reference](#cli-reference)
- [Reading the Report](#reading-the-report)
## Quick Start
```bash
# Run every task under tasks/ against the variants in an experiment:
coder-eval run -e experiments/model-comparison.yaml
# Scope to specific tasks:
coder-eval run -e experiments/plugin-comparison.yaml tasks/agents/claude_*.yaml
# Bare experiment name resolves to experiments/.yaml:
coder-eval run -e model-comparison tasks/hello_date.yaml
```
With no `-e`, `experiments/default.yaml` is applied as a single implicit variant
(`default`). Adding `-e` is what turns a run into an A/B comparison.
## Experiment YAML Structure
An experiment file lives in `experiments/` and has three top-level keys:
```yaml
experiment_id: my-comparison # kebab-case, required
description: "What this experiment measures"
defaults: # optional — applied to every variant
agent:
type: claude-code
permission_mode: bypassPermissions
allowed_tools: ["Skill", "Bash", "Read", "Write", "Edit", "Glob", "Grep"]
repeats: 3 # default replicate count for all variants
variants: # required — at least 1, unique variant_id
- variant_id: arm-a
description: "Baseline"
agent:
plugins: []
- variant_id: arm-b
description: "Treatment"
agent:
plugins:
- type: "local"
path: "../skills"
```
`defaults` is an `ExperimentDefaults` block; each entry under `variants` is an
`ExperimentVariant`. Both carry **partial** `agent` dicts — you only specify the
keys that differ from the layers below.
## The 5-Layer Config Merge
Every resolved task is built by merging five layers, **later wins**:
| # | Layer | Source |
| --- | ------------------- | --------------------------------------------------------- |
| 1 | Baseline defaults | `experiments/default.yaml` |
| 2 | Experiment defaults | `defaults:` block in your experiment YAML |
| 3 | Task config | `tasks/.yaml` (`agent:`, `run_limits:`, …) |
| 4 | Variant overrides | the per-variant block in your experiment YAML |
| 5 | CLI flags | `-D path=value` / `--set` and its two aliases (`--model`, `--driver`) — always wins |
Merge semantics: all five layers merge through **one** resolver
(`orchestration/config_merge.py`), where each field declares *how it merges* once
on the model. A given field merges identically regardless of which layer supplied
it (the unification invariant). The per-field strategy is:
- **scalars** (`agent.model`, `agent.permission_mode`, `run_limits.*`) and
**most lists** (`allowed_tools`, `disallowed_tools`, `plugins`, …) — **replace**
(last layer wins; a variant's `allowed_tools: ["Read"]` replaces the lower list
entirely). `run_limits` is per-field replace, so a variant setting
`run_limits.max_turns` leaves the task's `task_timeout` intact.
- **nested models** (`sandbox.docker`, `python`, `node`, `limits`) and **free-form
dicts** (`agent.sdk_options`) — **deep**-merge: a higher layer touching one
sub-key (e.g. `docker.network`) preserves siblings set below it (e.g.
`docker.image`).
- **append lists** — overlays accumulate. `sandbox.docker.env_passthrough_extra`
appends in layer order (`default → exp-defaults → task → variant`).
`sandbox.template_sources` appends **task-first** (the task's base templates,
then experiment-defaults and variant overlays after — "appended after task's
base templates").
Variants set the sandbox driver via `driver:` and add templates via
`template_sources:` (top-level fields); they don't set a full `sandbox:` block.
## What a Variant Can Override
From `ExperimentVariant` (`coder_eval/models/experiment.py`):
| Field | Type | Use |
| --------------------- | ------------------ | -------------------------------------------------------------------------------------- |
| `variant_id` | str | Unique arm identifier (required) |
| `description` | str | Human-readable label shown in reports |
| `agent` | dict | Partial `AgentConfig` overrides (model, plugins, tools, system_prompt, sdk_options, …) |
| `simulation` | dict | Partial `SimulationConfig` overrides (persona, goal, `n_trials`, … per arm) — see [Dialog Mode](https://coder-eval.com/docs/dialog-mode) |
| `repeats` | int | Replicate count for this arm (overrides experiment default) |
| `template_sources` | list | Extra templates appended after the task base (e.g. a docs overlay) |
| `prompt_mutations` | list | Ordered mutations applied to `initial_prompt` |
| `initial_prompt` | str | Full prompt replacement (mutually exclusive with the two below) |
| `initial_prompt_file` | str | Prompt replacement loaded from a file |
| `run_limits` | block | Per-key cap overrides (`max_turns`, `task_timeout`, token/USD budgets) |
| `driver` | `tempdir`/`docker` | Sandbox driver — enables tempdir-vs-docker arms |
| `checker_context` | dict | Backend/model override for the judge side (llm_judge, agent_judge) — has no bearing on the simulator; see [Checker Context](https://coder-eval.com/docs/task-definition-guide#checker-context); **not** currently `-D`-reachable |
The `agent` dict is the lever for most A/B tests. Anything on `AgentConfig` is
fair game: `model`, `permission_mode`, `allowed_tools`, `disallowed_tools`,
`plugins`, `system_prompt` / `system_prompt_file`, `setting_sources`,
`claude_settings`, `sdk_options`.
> **`system_prompt_mode` is a poor A/B lever.** A `replace` arm sends no default
> Claude Code prompt *at all*, so the delta measures the missing behavioral guidance
> (tool-call batching, conciseness), not your prompt text. To A/B prompt *content*,
> vary `system_prompt` and leave both arms on `append`.
> **Path-resolution gotcha.** Relative file paths in variant config resolve
> against _different_ base directories depending on the field:
>
> - `initial_prompt_file` (a top-level variant field) → relative to the
> **experiment YAML**.
> - `agent.system_prompt_file` (inside the `agent` dict) → relative to the
> **task YAML** (it's an `AgentConfig` field, resolved at task load).
>
> Bare experiment names passed to `-e` resolve under `experiments/.yaml`
> at the repo root, not relative to your CWD.
## Recipe: A/B a Skill
Skills are loaded **only** via the `plugins` field — the SDK's internal `skills`
option is framework-owned and can't be set from YAML. So the canonical skill A/B
is "plugin absent vs. plugin present":
```yaml
experiment_id: my-skill-impact
description: "Does the uipath-agents skill improve task completion?"
defaults:
agent:
type: claude-code
permission_mode: bypassPermissions
model: claude-sonnet-5
allowed_tools: ["Skill", "Bash", "Read", "Write", "Edit", "Glob", "Grep"]
variants:
- variant_id: bare
description: "No skill — baseline"
agent:
plugins: [] # skill unavailable
- variant_id: with-skill
description: "uipath-agents skill loaded"
agent:
plugins:
- type: "local"
path: ".." # PLUGIN ROOT holding skills/ — see note below
```
Notes:
- Keep `"Skill"` in `allowed_tools` for **both** arms — the baseline simply has no
plugin to expose, so the tool is never invokable. This keeps the only variable
the skill itself.
- Loading a plugin only **offers** the skill; the model decides whether to invoke
it. Pair the experiment with a [`skill_triggered`](https://coder-eval.com/docs/task-definition-guide#skill_triggered)
criterion to measure _whether it fired_ alongside your real success criteria
that measure _whether outcomes improved_.
- **`path` must be a plugin ROOT — a directory holding `skills/`** — so the skill
resolves at `/skills//SKILL.md`. Point one level deeper, at the
directory of skill directories, and claude-code loads **nothing**: the `with-skill`
arm then silently matches the baseline and the A/B compares two identical arms.
Codex and Antigravity accept either depth, so this fails on claude-code alone —
see [Harness parity](https://coder-eval.com/docs/agents/harness-parity#agentpluginspath-accepts-different-depths-per-harness).
- Plugin paths are environment-dependent. The shipped example expects a
`$PLUGIN_PATH` env var pointing at your plugin **root**. See
`experiments/plugin-comparison.yaml`.
Run it:
```bash
coder-eval run -e experiments/my-skill-impact.yaml tasks/agents/create/*.yaml
```
## Recipe: A/B a Model
```yaml
experiment_id: model-comparison
description: "Sonnet vs. Opus on the same tasks"
variants:
- variant_id: sonnet
agent: { model: claude-sonnet-5 }
- variant_id: opus
agent: { model: claude-opus-5 }
```
## Recipe: A/B a Prompt
Use `prompt_mutations` (transform the task prompt) or `initial_prompt` /
`initial_prompt_file` (replace it wholesale). All three are mutually exclusive
per variant — setting two raises at load.
```yaml
experiment_id: prompt-phrasing
description: "Terse vs. detailed instructions"
variants:
- variant_id: terse # uses the task's prompt unchanged
- variant_id: detailed
prompt_mutations:
- type: suffix
content: "Think step by step and validate your work before finishing."
```
### The mutation catalog
Four mutation types, applied to the base `initial_prompt` at **variant
resolution time** — before the task ever reaches the orchestrator:
| `type` | Fields | Defaults |
| ---------- | ------------------------------------------------- | --------------------- |
| `prefix` | `content` (required), `separator` | `separator: "\n\n"` |
| `suffix` | `content` (required), `separator` | `separator: "\n\n"` |
| `replace` | `pattern`, `replacement` (both required), `regex` | `regex: false` |
| `template` | `variables` (mapping, required) | — |
- **Ordered.** `prompt_mutations` is a list and each mutation operates on the
result of the one before it. A `replace` listed after a `suffix` will rewrite
the appended text too, which is occasionally what you want and more often a
surprise — keep the list short and ordered deliberately.
- **`prefix` / `suffix`** join with `separator`, default `"\n\n"` (write it
quoted in YAML so the escape is interpreted).
- **`replace`** is a literal `str.replace` by default. With `regex: true` it
becomes `re.sub`, so `pattern` is a Python regular expression and
`replacement` follows `re.sub` semantics — `\1` backreferences work, and an
unanchored pattern can match far more than you intended.
- **`template`** substitutes literal `{name}` occurrences with the mapped value
via plain string replacement — **not** `str.format`, and unrelated to the
`${row.}` syntax used by [datasets](https://coder-eval.com/docs/datasets). A `{name}` with no
matching entry in `variables` is left in the prompt verbatim rather than
raising, so a typo in a variable name fails silently at the *prompt* level.
Read the rendered prompt in the report to confirm.
Every mutation model sets `extra="forbid"`, so a misspelled field (`text:`
instead of `content:`) is a hard `ValidationError` at load — never a silently
ignored no-op.
When both `defaults.prompt_mutations` and a variant's `prompt_mutations` are set,
they **compose** — the experiment-defaults mutations apply first, then the
variant's, on the already-mutated prompt.
## Recipe: Smoke vs. e2e Flavors (Early Stop)
Run the **same** task file as both a fast `smoke` flavor and a full `e2e` flavor
with a one-line kill switch on the reference variant. Arm the criteria
that define "the interesting thing happened" with `stop_early:` blocks in the
task file;
the `smoke` variant cuts off as soon as they're decided, while `e2e` runs to
completion. Because the field merge is per-key, the variant sets only
`stop_early` (the run-level kill switch) without disturbing the task's `max_turns`.
```yaml
experiment_id: early-stop-ab
description: "Smoke vs. e2e from one file via opt-in early stop"
variants:
- variant_id: e2e
run_limits:
stop_early: false # kill switch: force-disarm the blocks (the reference flavor)
- variant_id: smoke
# no override needed: the task's stop_early: blocks arm the watcher
```
The task file supplies the arming (`stop_early:` blocks on the criteria that gate the
flavor) and a `max_turns` generous enough for `e2e`; see
[`stop_early`](https://coder-eval.com/docs/task-definition-guide#stop_early-opt-in-early-stop). This recipe
ships as `experiments/early-stop-ab.yaml`.
Expect the `smoke` variant significantly lower on turns, duration, and tokens.
Verdict parity with `e2e` is **one-sided**: an early-stopped run is gated on the
armed subset only (non-armed criteria become advisory, clearly marked in the
report), a **fail-stop** is verdict-preserving (it is deferred until every
pass-armed criterion has resolved), but a **pass-stop** cuts the run once the
positives are decided — a distractor that would only misfire on a later tool
call is never observed, so the frozen row scores as a clean pass. Authoritative
precision/recall therefore belongs on the `e2e` (`stop_early: false`) variant.
## Replicates (Statistical Power)
Agents are stochastic — a single run per arm is noise, not signal. Set `repeats`
to run each `(task, variant)` pair N times; the report aggregates per-replicate
scores so you can see variance, not just a point estimate.
```yaml
defaults:
repeats: 5 # every arm runs 5×
variants:
- variant_id: bare
- variant_id: with-skill
repeats: 10 # this arm overrides to 10×
```
CLI `--repeats N` overrides both.
## Measuring the Difference
The experiment report ranks variants by **weighted score** per task plus
cross-task aggregates (win rate, average score, average duration, tokens). That
covers "which arm did better overall."
For skill experiments specifically, add a `skill_triggered` criterion to your
task. On a **dataset-backed** task it produces suite-level classification metrics
you can gate on with `suite_thresholds`:
```yaml
success_criteria:
- type: skill_triggered
description: "uipath-agents activation"
skill_name: uipath-agents
expected_skill: "${row.expected_skill}" # "" for rows where it shouldn't fire
suite_thresholds:
recall.yes: 0.70 # fired on ≥70% of rows that needed it
precision.yes: 0.80 # ≤20% false activations
```
Available metric keys (from the classification overlay): `accuracy`, `macro_f1`,
`weighted_f1`, `micro_f1`, and per-label `precision.` / `recall.` /
`f1.` (labels are `yes` / `no`). A suite gate fails the run (non-zero exit)
if any listed metric is below its minimum.
## CLI Reference
| Flag | Effect |
| ----------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------ |
| `-e, --experiment ` | Experiment YAML. Bare name → `experiments/.yaml`. |
| `--sample N` | For dataset-backed tasks, use a fixed-seed random N-row sample (reproducible, unbiased across paths; cheap smoke test). |
| `--repeats N` | Run each `(task, variant)` N times; overrides YAML `repeats`. |
| `--driver tempdir\|docker` | Override sandbox driver for all tasks. |
| `-j, --max-parallel N` | Run up to N tasks concurrently. |
| `-t, --tags` / `--exclude-tags` | Filter which tasks run. |
| `-D path=value` / `--set` | Generic layer-5 override of any resolved task-config field, applied to **every** variant — e.g. `-D agent.model=opus -D run_limits.max_turns=30`. Repeatable; schema-validated. |
| `--model`, `--driver` | Thin aliases for `-D` (`--model` ≡ `-D agent.model`, `--driver` ≡ `-D sandbox.driver`). All other task-config knobs (permission mode, turn/timeout limits, tools, plugins, SDK options) are set via `-D`. Layer-5 overrides apply to **every** variant (use sparingly — they erase the contrast between arms). |
| `--type` | Dedicated flag for agent type, applied to every variant (re-parses the agent discriminated union). |
Layer-5 flags win over variant config, so overriding the very thing you're
A/B-testing (e.g. `--model` on a model-comparison experiment) collapses all arms
to the same value. Set the variable in the variant block, not on the CLI.
## Reading the Report
Each run writes to `runs//`. Per-task artifacts are nested
**variant-first**: `runs/////`, where `` is the
zero-padded replicate index (`00`, `01`, …). There is no ``
segment — the experiment-level report lives at the run root.
The reports (generated by `reports_experiment.py`) are:
- **`experiment.md` / `experiment.json`** (run root) — the cross-variant summary:
each task's per-variant score, the `best_variant`, the `score_spread`, and
per-variant aggregates (tasks run/succeeded/failed, average score, average
duration, total tokens, and — when `repeats > 1` — `per_replicate_scores` so you
can see variance, not just a point estimate). `experiment.html` renders the same
data for browsing.
- **`/variant.md` / `variant.json`** — per-variant rollup (plus
`variant.html`).
- **`run.md` / `run.json`** (run root) — the flat batch log across all
task × variant runs.
---
**See also:** [TASK_DEFINITION_GUIDE.md](https://coder-eval.com/docs/task-definition-guide) for task and
criterion reference, including [`skill_triggered`](https://coder-eval.com/docs/task-definition-guide#skill_triggered).
---
# Bring Your Own Dataset
A `dataset:` block turns **one** task file into **N** independent evaluation tasks — one per row.
Write the prompt and the success criteria once, parameterize them with `${row.}`, and point
the task at a list of rows. This is how Coder Eval runs benchmark-sized suites (classification sets,
skill-activation corpora, regression fixtures) without duplicating YAML.
The `dataset:` field is documented field-by-field in the
[Task Definition Guide](https://coder-eval.com/docs/task-definition-guide#dataset). This page is the how-and-why.
## How fan-out works
Expansion happens in `orchestration/task_loader.expand_dataset` at load time, **before** experiment
variant resolution. For each row:
- `task_id` becomes `/` — e.g. `sentiment-classification/r1`.
- `suite_id` is set to the original `task_id`, and `row_id` to the row's identifier. Both are set by
the expander; you never author them.
- `dataset` is cleared on the expanded task, so nothing re-expands downstream.
- Every row-task runs in its **own sandbox** and writes its **own run directory** and `task.json`,
exactly like a hand-written task.
Because expansion runs before variant resolution, **an experiment variant cannot override the
dataset** — every arm of an A/B sees the identical row set, which is what makes the comparison fair.
Rows that share a `suite_id` roll up into a per-suite `suite.json` / `suite.md` alongside the normal
run report. The [Report Schema](https://coder-eval.com/docs/report-schema) has the field-level contract in its `suite.json`
section.
## Two row sources
Exactly one of `rows` or `paths` must be set. Both, or neither, raises at load time.
### Inline rows
Best for a handful of rows that belong with the task:
```yaml
dataset:
rows:
- id: alpha
expected: "alpha"
- id: beta
expected: "beta"
```
### JSONL files
Best for real datasets. Each path is **relative to the task YAML's directory** (not your working
directory), and multiple paths are concatenated into one row stream in declared order:
```yaml
dataset:
paths:
- "datasets/sentiment.jsonl"
- "datasets/sentiment_extra.jsonl"
```
Each line is one JSON object — the same shape as an inline row:
```json
{"id": "r1", "text": "This product is fantastic, I love it.", "expected": "positive"}
```
## Substituting row values
`${row.}` placeholders are replaced with that row's value in exactly two places:
1. the task's `initial_prompt`, and
2. every **string leaf** of every `success_criteria` entry (at any nesting depth).
Nothing else is substituted — not the task-level `description`, not `pre_run`, not `sandbox`. Keep
row-varying data in the prompt and the criteria. (A *criterion's* own `description` is a string leaf
of `success_criteria`, so it **is** substituted — see the example below.)
```yaml
initial_prompt: "Classify this text: ${row.text}"
success_criteria:
- type: "classification_match"
path: "result.txt"
expected_label: "${row.expected}"
allowed_labels: [positive, negative]
description: "Predicted label matches expected for row ${row.id}"
```
Two failure modes, both raised at load time rather than producing a silently wrong prompt:
- a placeholder naming a field the row doesn't have → `KeyError: ${row.foo}: key not found
(available: [...])`;
- a placeholder resolving to a list or dict → `TypeError: ${row.foo}: value must be a scalar`.
A field whose value is `null` substitutes as the empty string. That is the shape a classification
suite wants for a negative row — "this row has no expected label" — though such rows are more often
written with an explicit `""`.
## Row identifiers
`id_field` (default `id`) names the row field used as the row's identity. That value becomes a
directory name under the run dir, so it is validated: it must match
`^[A-Za-z0-9_][A-Za-z0-9_.\-]*$` — letters, digits, underscore, hyphen, dot, not starting with a
dot or hyphen — and must be unique across the dataset.
```yaml
dataset:
id_field: "case_id" # rows carry `case_id` instead of `id`
paths: ["datasets/cases.jsonl"]
```
Load-time errors, with their message shapes:
| Situation | Message |
| --- | --- |
| No rows at all | `Dataset for task '' is empty` |
| Row lacks the id field | `Dataset row for task '' missing id_field '': ` |
| Id has illegal characters | `Dataset row id '' must match ^[A-Za-z0-9_][A-Za-z0-9_.\-]*$ (letters, digits, underscore, hyphen, dot)` |
| Two rows share an id | `Duplicate dataset row id for task '': ''` |
| Both/neither `rows` and `paths` | `Dataset must specify either 'paths' or 'rows'` / `... only one of ...` |
| `paths: []` | `Dataset.paths must be a non-empty list` |
## Sampling a subset
A full dataset is expensive. Two independent mechanisms cut it down, and **`--sample` wins whenever
both apply**:
1. **`--sample N` (CLI only)** — a flat uniform-random N rows over the whole dataset. Fixed seed, so
the same N rows come back every run: a reproducible, cheap smoke flavor of a big suite. Unlike a
first-N slice it is unbiased across concatenated `paths`. If `N` is greater than or equal to the
dataset size, the whole dataset runs — not an error.
2. **Stratified: `--sample-per-stratum N` (CLI) or `dataset.sample_per_stratum: N` (YAML)** — keep up
to N rows per stratum, where a row's stratum is the value of `stratify_field` (default
`expected_skill`). Strata with N rows or fewer are taken whole. The CLI flag overrides the YAML
value, so a runner can cap a dataset without editing the task. Rows missing `stratify_field` fall
into the `""` stratum. This is the right sampler for classification suites, where a uniform draw
would starve rare strata.
!!! warning "Stratified sampling is nondeterministic by default"
The stratified draw is seeded **only** by `dataset.sample_seed`. When `sample_seed` is unset the
sample is deliberately **re-drawn on every run** — whether the per-stratum count came from the
YAML `sample_per_stratum` or the CLI `--sample-per-stratum` flag. That is intentional: the
nightly activation suite relies on it to broaden coverage across runs rather than re-measuring
the same rows forever.
Set `sample_seed` to an integer to pin a reproducible sample — do that when you are comparing
two runs and need the row set held constant (a regression bisect, an A/B where you want the
identical rows in both arms on separate invocations). Leave it unset for recurring suites where
coverage over time matters more than run-to-run comparability. Note the contrast with
`--sample N`, which is fixed-seed and reproducible by default.
## Suite-level scoring
Per-row pass/fail is rarely the number you care about on a dataset — the suite metric is. Every
criterion's `aggregate()` emits `count / mean / median / std / min / max`, and classification-style
criteria (`classification_match`, `skill_triggered`) additionally emit accuracy, per-label
precision / recall / F1, and a confusion matrix.
Add `suite_thresholds` to a criterion to gate the whole suite on those aggregated metrics; the run
exits non-zero if any gate fails:
```yaml
success_criteria:
- type: "classification_match"
path: "result.txt"
expected_label: "${row.expected}"
allowed_labels: [positive, negative]
description: "Predicted label matches expected"
suite_thresholds:
accuracy: 0.8
macro_f1: 0.75
```
Full metric-key list and the rollup outputs:
[User Guide → Suite Thresholds](https://coder-eval.com/docs/user-guide#suite-thresholds--classification-metrics) and
[Task Definition Guide → `skill_triggered`](https://coder-eval.com/docs/task-definition-guide#skill_triggered).
## Worked example: inline rows
`tasks/dataset_example.yaml` — two rows, one criterion, expands to
`dataset-example/alpha` and `dataset-example/beta`:
```yaml
task_id: "dataset-example"
description: "Demonstrates dataset fan-out: one task file, N sub-tasks, one per row."
initial_prompt: "Write the string '${row.expected}' into out.txt. Say nothing else."
tags: [smoke, smoke-pass, dataset]
agent:
type: "claude-code"
permission_mode: "acceptEdits"
allowed_tools: ["Write"]
dataset:
rows:
- id: alpha
expected: "alpha"
- id: beta
expected: "beta"
success_criteria:
- type: "file_check"
path: "out.txt"
includes: ["${row.expected}"]
description: "out.txt contains '${row.expected}'"
```
## Worked example: JSONL plus suite thresholds
`tasks/sentiment_classification.yaml` reads its rows from a JSONL file and gates the suite on
aggregated classification metrics:
```yaml
task_id: "sentiment-classification"
description: "Binary sentiment classification over a 3-row dataset with one intentionally mislabeled ground truth, to exercise non-trivial P/R/F1."
tags: [classification]
agent:
type: "claude-code"
permission_mode: "acceptEdits"
allowed_tools: ["Write"]
# Row 3 is intentionally mislabeled (text is clearly positive but expected=negative).
# A correct model produces: accuracy 2/3, recall(positive)=1/2, recall(negative)=1/1,
# precision(positive)=1/1, precision(negative)=1/2, f1(positive)=f1(negative)=2/3.
dataset:
paths:
- "datasets/sentiment.jsonl"
initial_prompt: |
Classify the sentiment of the following text as exactly one word: 'positive' or 'negative'.
Write only that single word (lowercase, no punctuation, no other text) to a file named result.txt.
Text: "${row.text}"
success_criteria:
- type: "classification_match"
path: "result.txt"
expected_label: "${row.expected}"
allowed_labels: [positive, negative]
description: "Predicted label matches expected for row ${row.id}"
# Suite-level thresholds: evaluated against the aggregated metrics.
# With the one intentionally mislabeled row the expected numbers are
# accuracy=0.667, macro_f1=0.667, recall.positive=1.0.
suite_thresholds:
accuracy: 0.6
macro_f1: 0.5
recall.positive: 0.9
```
Its rows live in `tasks/datasets/sentiment.jsonl`:
```json
{"id": "r1", "text": "This product is fantastic, I love it.", "expected": "positive"}
{"id": "r2", "text": "Terrible service, would not recommend.", "expected": "negative"}
{"id": "r3", "text": "Amazing quality and excellent value for money.", "expected": "negative"}
```
Run it, or a cheap sample of it:
```bash
coder-eval run tasks/sentiment_classification.yaml # every row
coder-eval run tasks/sentiment_classification.yaml --sample 2 # a reproducible 2-row sample
```
## See also
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide#dataset) — the `dataset:` field reference.
- [Report Schema](https://coder-eval.com/docs/report-schema) — the `suite.json` field contract.
- [A/B Experiments](https://coder-eval.com/docs/ab-experiments) — running a dataset across multiple variants.
---
# Dialog Mode: multi-turn user simulation
Most evaluation harnesses hand an agent one perfect prompt and grade the artifact. Real users don't
write perfect prompts. They ask for something vague, answer questions, change their mind, and hold
back requirements until asked.
Dialog mode replaces the single-shot loop with a conversation between the coding agent and a
**simulated user** — a second LLM driven by a persona and a goal. It is the only way to measure the
behaviors that only exist in conversation.
## When to use it
Reach for dialog mode when the thing you want to score is conversational:
- **Does the agent ask?** A good agent asks a clarifying question instead of guessing when the
request is underspecified. Give the simulator a goal that withholds a requirement and see whether
the agent surfaces it.
- **Requirement discovery.** Score whether the agent eventually extracts everything it needs across
several turns, not whether it one-shots a fully-specified prompt.
- **Multi-turn recovery.** The agent goes down the wrong path, the user corrects it — does it
recover, or double down?
- **Prompt robustness.** A persona that is terse, impatient, or non-technical is a much harsher test
than your hand-tuned `initial_prompt`.
Stay in single-shot mode when the task is genuinely fire-and-forget. Dialog mode multiplies cost and
adds variance; don't pay for it when the extra turns measure nothing.
## How it works
Add an enabled `simulation:` block to any task and the orchestrator swaps its iteration loop for a
dialog driver:
```yaml
simulation:
enabled: true
persona: |
You are a user with one specific request. You give the request only when
asked, and then you wait for the agent to do it.
goal: |
Get the agent to echo your string back verbatim. Reveal the string only
when the agent asks what you want.
max_turns: 4
```
The mechanics:
- The task's `initial_prompt` is the user's **opening message**. The simulator takes over from turn
two, seeing the agent's last reply and producing the next user utterance.
- `initial_prompt` is **optional** in dialog mode. Omit it and the simulator writes the opener too,
from its persona and goal — closer to a cold-start user.
- Each exchange is one user message plus the agent's full response (the agent may make many tool
calls inside a single exchange).
- The simulator is a **tools-disabled Claude Code agent** with `allowed_tools: []`, an explicit
deny-list, and no plugins or settings sources. It is pure text-in / text-out, and it **cannot see
the sandbox** — no files, no terminal, no agent reasoning. Only what the agent writes in the chat.
- The simulator resolves its own `ApiRoute` independently of `checker_context.api_route` (that
override is judge-only — see [Checker Context](https://coder-eval.com/docs/task-definition-guide#checker-context)) — same
resolution as the coding agent's own route (`--backend direct` / `--backend bedrock`), including
the pin to a constant Claude backend when the agent itself runs on an open-weight LiteLLM route.
The **model** is separately
pinned by `simulation.model` (see [Simulation](https://coder-eval.com/docs/task-definition-guide#simulation)), not inherited
from the route — so an A/B varying the subject model doesn't silently vary the simulated user too.
**Agent-kind constraint.** The *subject* agent can be any registered kind — the dialog driver only
calls the agent's `communicate()`, so Codex and plugin agents work. The *simulator*, however, is
always a Claude Code agent. A dialog run therefore needs the `claude` CLI on `PATH` and working
Anthropic or Bedrock credentials **even when the agent under test is not Claude**.
**Early stop is not available here.** [Criterion-level `stop_early:` arming](https://coder-eval.com/docs/task-definition-guide#stop_early-opt-in-early-stop)
is single-shot-only; an armed criterion alongside `simulation.enabled` is a hard error at resolution
time, not a silent no-op (disarm with the `run_limits.stop_early: false` kill switch to run anyway).
Use `stop_on_criteria_pass` (below) for the dialog equivalent.
Every field's default and constraint lives in one place — the
[Task Definition Guide's simulation section](https://coder-eval.com/docs/task-definition-guide#simulation-multi-turn-user-dialog).
This page deliberately does not restate them.
## Designing the persona and goal
`persona` is *who is talking*; `goal` is *what they want*. Keep them separate — a persona that
smuggles in the requirements defeats the point.
The most useful pattern is **withholding**. State the full goal for the simulator, then instruct it
not to volunteer part of it:
```yaml
persona: |
A non-technical business analyst who knows the outcome they want but not how
automation works. Mildly impatient, answers questions directly.
goal: |
Build a flow that reads invoice PDFs from an Outlook folder, extracts
vendor/amount/date, and posts the result to Google Sheets.
Do NOT volunteer the Google Sheets requirement unless the agent asks where
the output should go.
constraints:
- "Do not paste code — you cannot read code."
- "If the agent goes silent for two turns, ask 'are you still there?'."
```
Now the task measures something a single-shot prompt cannot: whether the agent asks about the output
destination at all. Pair it with a criterion that checks the Sheets integration exists and you have a
clean signal.
`constraints` are behavioral rules, not more requirements. Good ones bound *how* the simulator
speaks ("no code", "one question at a time", "reveal X only if asked"). Resist writing constraints
that quietly hand the agent the answer.
## How a dialog ends
After each exchange the driver evaluates the stop conditions **in this order**, first match wins:
1. **`run_limits` breach** (`run_limit_exceeded`) — a subject-agent budget cap tripped. The
end-of-dialog criteria still run for partial credit, then the task **aborts**.
2. **`stop_on_criteria_pass`** (`criteria_passed`) — every success criterion passes. Requires
per-turn checking (`check_criteria: every_turn` or `both`); pairing it with the default
`end_of_dialog` is rejected at load time, since there would be nothing to check against.
3. **`max_turns`** (`max_turns`) — the hard cap on exchanges. The agent exhausting its *own* inner
`max_turns` mid-exchange ends the dialog with the same reason.
4. **`max_total_tokens`** (`budget`) — the dialog-wide budget across simulator **and** agent. The
dialog ends and the task is **still scored** — unlike
[`run_limits.max_total_tokens`](https://coder-eval.com/docs/task-definition-guide#run-limits), which covers the subject
agent only and aborts.
5. **`stop_token`** (`stop_token`) — only if none of the above fired is the simulator asked for
another message; the sentinel token in *that fresh utterance* ends the dialog. This is the
workhorse in practice — the simulator decides, in character, that it got what it wanted — but it
is evaluated **last**, so a turn that trips `max_turns` or the budget never gets the chance to
produce it.
A simulator call that raises ends the dialog with `error` (and increments
`simulation.simulator_failures`). The reason is recorded as `simulation.stop_reason` on the result,
so you can tell a conversation that finished from one that merely ran out of turns.
> **`check_criteria: every_turn` multiplies criterion cost.** Criteria are re-evaluated after every
> exchange, so an `llm_judge` or `agent_judge` criterion in a 12-turn dialog runs twelve times.
> That is often more expensive than the dialog itself. Use `end_of_dialog` (the default) unless you
> genuinely need early stop or a per-turn record; `both` gives you the per-turn trace *and* an
> authoritative final check.
## Trials and variance
A single dialog is one sample from a stochastic process — the simulator improvises as much as the
agent does. `n_trials` runs the conversation N independent times per (task, variant):
```yaml
simulation:
enabled: true
n_trials: 5
```
Each trial is fanned out as its own unit of work with its own sandbox, its own run directory
(`runs/////`, zero-padded index), and its own `task.json`. On the result,
`simulation.replicate_index` and `simulation.n_trials` identify the trial, and reports render a
"Trial *k* of *N*" row. Trials reuse the replicate machinery, so when a simulation task sets
`n_trials > 1` it takes precedence over experiment-level `repeats`.
Trials are ordinary batch units: they run concurrently exactly as far as `--max-parallel` allows —
there is no per-task trial-concurrency switch; scheduling is entirely `--max-parallel`'s job.
## Grading a dialog
Set `include_dialog: true` on every `llm_judge` / `agent_judge` criterion in a simulated task. This
is not optional polish — without it the judge sees only the agent's outputs and no user side, so a
requirement the user stated in turn 3 looks like something the agent invented. Judges routinely
score that as a hallucination.
```yaml
success_criteria:
- type: llm_judge
description: "Agent satisfied the requirement the user gave mid-conversation"
prompt: |
Read the DIALOG block. Grade the agent on whether it satisfied the
requirement the user actually stated — not what you assume the task is.
include_dialog: true
pass_threshold: 0.9
```
The rendered dialog is wrapped as `UNTRUSTED DATA` with a rubric guard telling the judge that claims
made only by the *simulated user* may be invented, and not to penalize the agent for going along
with them. That guard is what keeps a chatty simulator from poisoning the grade.
## What it costs
Budget roughly `max_turns × n_trials` agent turns per (task, variant) — the worst case, since the
dialog usually stops on the stop token first. On top of that:
- **Simulator tokens**, one generation per turn. Small next to the agent's, but not free, and they
are reported separately as `simulation.simulator_input_tokens` / `simulator_output_tokens`.
- **Criterion cost**, multiplied by turn count under `check_criteria: every_turn` or `both`.
Cap it with [`run_limits`](https://coder-eval.com/docs/task-definition-guide#run-limits) — but note the accounting boundary:
`run_limits` budgets count the **subject agent only**, so simulator spend is invisible to
`max_total_tokens` and `max_usd`. To bound the conversation as a whole, use
`simulation.max_total_tokens`, which counts both sides.
## Dialog mode as an experiment axis
Everything on the `simulation:` block is overridable per variant, which makes the conversation itself
the thing under test. A variant sets a partial `simulation:` block that shallow-merges onto the
task's:
```yaml
variants:
- variant_id: patient-user
simulation:
persona: "A patient engineer who answers questions precisely."
- variant_id: terse-user
simulation:
persona: "A terse, impatient user who gives one-line answers."
```
Productive axes: persona (terse vs. chatty, technical vs. not), how much the goal withholds, and
`n_trials` as a cost/confidence trade. See [A/B Experiments](https://coder-eval.com/docs/ab-experiments) for the full
experiment layer.
## Security posture
The task's `reference` solution is **never** passed to the simulator, exactly as it is never passed
to the coding agent. A simulator that could read the reference would leak it into the dialog and the
agent would be graded against an answer it was handed.
What the simulator *does* see, all inlined into its system prompt: `persona`, `goal`, `constraints`,
the task's **`description`**, and the pinned `initial_prompt` when there is one. The `description` is
easy to forget — it reads like evaluator-private metadata, but the simulator gets it verbatim. If
your persona withholds a requirement, don't spell that requirement out in `description`, or the
simulator may volunteer what you meant it to keep back.
The simulator also runs with no tools, no plugins, and no settings sources, so it cannot read or
write the sandbox even if its persona instructs it to.
## See also
- [Task Definition Guide → Simulation](https://coder-eval.com/docs/task-definition-guide#simulation-multi-turn-user-dialog) —
every field, default, and constraint.
- [A/B Experiments](https://coder-eval.com/docs/ab-experiments) — running personas as variants.
- [Run Limits](https://coder-eval.com/docs/task-definition-guide#run-limits) — the caps that bound a dialog's cost.
---
# Docker Isolation
Run each evaluation task inside its own fresh container. Strong host isolation and a pinned, reproducible agent runtime.
## When to use
Set `sandbox.driver: docker` on a task (or pass `--driver docker` on the CLI —
a thin alias for `-D sandbox.driver=docker`) when you want:
- **Isolation from the host filesystem/network** — agent-generated code can't reach files outside the sandbox.
- **A pinned toolchain** — the image bakes in Python 3.13, Node 22 LTS, `@anthropic-ai/claude-code`, `uv`, and the matching `coder_eval` version, so results don't drift with host upgrades.
Aggregation (P/R/F1, suite thresholds, reports) always stays on the host. Each container is a sealed "run one task → emit one `task.json`" worker.
## One-time setup
```bash
make docker-image # core + both built-in agents (default; no credentials)
# opt in to the UiPath extra (resolves from public PyPI; no credentials):
make docker-image-full
```
Both build `coder-eval-agent:` and tag it `:latest`.
- **`make docker-image`** installs the core package plus **both built-in agents** — claude-code (baked above) and Codex (`--extra codex`, public PyPI). It needs **no credentials** and covers the common case: claude-code or Codex tasks scored with `run_command` / `file_contains` (incl. converted skillsbench tasks). `llm_judge` / `agent_judge` work here too (they route through the run's Anthropic/Bedrock backend).
- **`make docker-image-full`** additionally installs the `uipath` extra. The `uipath` SDK resolves from **public PyPI** (per `uv.lock`), so the build needs **no credentials**. Use this only for tasks that shell out to the in-host `uipath` CLI. (Codex is already in the default image — no extra needed.)
> **Codex sandbox under Docker.** Codex's Landlock-backed `read-only` / `workspace-write` sandboxes can't initialize inside the eval container — their writes/execs fail silently and the agent produces no artifacts (a `score=0` FAILURE with no loud error). The docker runner sets `CODER_EVAL_IN_CONTAINER=1`, and the Codex agent honors it by falling back to `full-access`: the container itself is the trust boundary. Host runs (tempdir) are unaffected — Landlock works there and the marker is unset. So Codex tasks run under `--driver docker` with their natural `acceptEdits` permission mode; no need to set `bypassPermissions` by hand.
## Running a task in Docker
```bash
# Single task
coder-eval run path/to/task.yaml --driver docker
# All tasks
coder-eval run --driver docker
# Or in the task YAML
sandbox:
driver: docker
docker:
network: bridge # or "none" for sealed runs
image: my-custom:tag # override the default image
```
## Using a pre-built custom image
When your tasks need extra tools or dependencies, extend the framework image once and point tasks at
the result — no per-task build. The custom image must extend `coder-eval-agent:` so it
inherits the coder-eval runtime, the entrypoint script, and the `org.coder-eval.version` label the
host's preflight check reads. (For a task whose Dockerfile can't be rebased onto Debian, use
[the runtime kit](#tasks-that-bring-their-own-base-image-the-runtime-kit-coder-eval-runtime)
instead. To have coder-eval build the image per task rather than pre-building it, see
[Building the image from a task Dockerfile](#building-the-image-from-a-task-dockerfile).)
```dockerfile
FROM coder-eval-agent: # match the version your host runs
RUN apt-get update && apt-get install -y --no-install-recommends custom-tool \
&& rm -rf /var/lib/apt/lists/*
```
```bash
docker build -t my-team/image:latest .
```
Select it either in the task YAML:
```yaml
sandbox:
driver: docker
docker:
image: my-team/image:latest
```
…or from the CLI, which overrides whatever the YAML says:
```bash
coder-eval run task.yaml -D sandbox.docker.image=my-team/image:latest
```
The default when you set nothing is `coder-eval-agent:`.
A worked example ships in-tree: `tasks/byod_smoke_test.yaml` runs against
`templates/byod_smoke_test/Dockerfile`, which extends the framework image and drops a marker file
that the task's success criterion then asserts — proving the custom image was actually used. (The
`byod_*` names here mean "Bring Your Own **Docker**"; they are unrelated to the
[Bring Your Own Dataset](https://coder-eval.com/docs/datasets) guide, which is about fanning one task out over data rows.)
```bash
make docker-image # base image first
docker build -t byod-custom-image:0.1.0 templates/byod_smoke_test/ # then the derived one
coder-eval run tasks/byod_smoke_test.yaml
```
### Troubleshooting custom images
| Symptom | Cause and fix |
| --- | --- |
| `docker: Error response from daemon: pull access denied` | The image isn't built locally and isn't pullable. Check `docker images`, then rebuild it. Docker treats an unknown local tag as a remote reference, which is why the error mentions a pull. |
| `Image coder_eval != host ` | The custom image carries an `org.coder-eval.version` label inherited from a stale framework base. Rebuild the base with `make docker-image`, then rebuild your derived image with `docker build --no-cache`. |
| `Image has no org.coder-eval.version label` | The image doesn't descend from `coder-eval-agent` (or predates the label). Rebase it on the framework image, or use the runtime kit. |
## Building the image from a task Dockerfile
Instead of pointing at a pre-built `image`, a task can ship its own `Dockerfile`
and have coder-eval build it before the run:
```yaml
sandbox:
driver: docker
docker:
dockerfile_path: ./environment/Dockerfile # relative to the task YAML
```
> **⚠️ Contract: a task Dockerfile MUST either start with `FROM coder-eval-agent:` or use the runtime kit (see below).**
> The container runs the coder-eval orchestrator (`coder-eval _run-task-internal`)
> via the framework image's `ENTRYPOINT`. A task Dockerfile extends that image and
> adds only task-specific layers — extra `apt` packages, `COPY`-ed inputs, etc.
>
> Build the framework base first — `make docker-image` (tags both
> `coder-eval-agent:` and `coder-eval-agent:latest`).
### Tasks that bring their own base image: the runtime kit (`coder-eval-runtime`)
The `FROM coder-eval-agent` contract above means a task is **rebased** onto the
Debian framework image. That breaks tasks whose Dockerfile was written for a
different base image (e.g. a Fedora recipe using `dnf`, which doesn't exist on Debian). To keep the task's own base image and build successfully, coder-eval's runtime need to be copied into the task's image. Use `make coder-eval-runtime` first to make the runtime available for copying.
```dockerfile
FROM fedora:41 # the task's own base, kept verbatim
RUN dnf -y install ... # the task's native recipe, runs on its own OS
# --- copy coder-eval runtime into a task image ---
COPY --from=coder-eval-runtime:latest /opt/coder-eval /opt/coder-eval
COPY --from=coder-eval-runtime:latest /usr/local/bin/coder_eval_entrypoint.sh /usr/local/bin/coder_eval_entrypoint.sh
LABEL org.coder-eval.version=""
```
`make coder-eval-runtime` builds the kit (`docker/Dockerfile.runtime`): a
standalone CPython + Node + the `coder-eval` CLI + Claude Code, all under
`/opt/coder-eval`, plus the entrypoint at the **same** `/usr/local/bin/...` path
the host pins. The kit is **glibc-only** — it runs on debian/ubuntu/fedora/rhel/…
but not musl/Alpine.
Both base images are independent and persistent — build each once and run any mix of rebase
and inject tasks without rebuilding. To build both in one shot (no credentials needed), use
**`make docker-images`** (= `make docker-image` + `make coder-eval-runtime`); reach for the
individual targets when you only need one.
> The kit installs the **no-credential** set only (core + codex), like `make docker-image` —
> it never installs the `[uipath]` extra, so there is no `make docker-images-full`. An
> inject-mode task that needs the LLMGW/`uipath` judge isn't supported by the kit as built.
```dockerfile
# environment/Dockerfile
FROM coder-eval-agent:latest # inherit runtime + entrypoint
RUN apt-get update && apt-get install -y --no-install-recommends poppler-utils
RUN pip install --no-cache-dir PyMuPDF==1.24.10
COPY input/ /root/input/
```
Behavior:
- **Path resolution** — `dockerfile_path` is resolved relative to the task YAML's
directory at load time (with `$VAR` / `${VAR}` expansion). A missing file fails
fast at load, not mid-run.
- **Entrypoint check** — after building, coder-eval inspects the image's
`ENTRYPOINT` and aborts with a `FROM coder-eval-agent` hint if the runtime
wasn't inherited.
- **Overrides `image`** — when `dockerfile_path` is set, it takes precedence over
any `image` value.
- **Build context** — the build context is the **Dockerfile's parent directory**,
so relative `COPY ./input/... ` instructions resolve naturally. In the layout
above, `environment/` is the context.
- **Caching** — the image is tagged deterministically as
`coder-eval-task-:built`, so repeat runs of the same task reuse
Docker's layer cache. Edit the Dockerfile and the next run rebuilds the
changed layers only.
- **Version-label check skipped** — the `org.coder-eval.version` preflight only
applies to the framework image; task-built images don't carry it and won't
warn.
A build failure aborts the task with a `DockerBuildError` (a `DockerRunError`
subclass) carrying `docker build`'s output. Because the build runs before the
run dir, `docker.log`, or `task.json` exist, the runner explicitly records the
failure so it is never a silent empty result dir: it creates the run dir, writes
the full build log to **`docker.log`**, and writes a synthetic **`task.json` with
`final_status: BUILD_FAILED`** (an `error`-category status) before re-raising. So
a failed build shows up per-task on the dashboard with its build log, exactly
where you'd look for container output.
### Customizing the build (`docker.build`)
The `docker build` invocation is configurable via `sandbox.docker.build`:
```yaml
sandbox:
driver: docker
docker:
dockerfile_path: ./environment/Dockerfile
build:
args: # -> --build-arg KEY=VALUE
PKG_VERSION: "1.2.3"
TOKEN: "${HOST_TOKEN}" # values are $VAR / ${VAR} expanded from the host env
secrets: # -> --secret (requires BuildKit)
- id=mytoken,env=MY_TOKEN # forward a host env var as a build secret
- id=npmrc,src=~/.npmrc # or a file
extra_args: ["--target", "runtime"] # escape hatch for any other docker build flag
buildkit: true # optional: force DOCKER_BUILDKIT (see below)
```
- **`args`** → `--build-arg KEY=VALUE`. Values are environment-expanded against
the host. Prefer `secrets` for credentials — build-args are recorded in the
image history.
- **`secrets`** → `--secret `. Use `id=NAME,env=VAR` to forward a host env
var or `id=NAME,src=PATH` for a file; reference it in the Dockerfile via
`RUN --mount=type=secret,id=NAME ...`. Secrets are exposed only to the mounting
RUN step and never baked into layers. **Secrets require BuildKit.**
- **`extra_args`** → raw flags inserted before the build context (e.g.
`--target`, `--network`, `--platform`). Escape hatch for options without a
dedicated field.
- **`buildkit`** → controls the `DOCKER_BUILDKIT` env var. Omitted (default),
coder-eval **inherits the invoker's environment** — set `DOCKER_BUILDKIT=1`
before running coder-eval to enable it globally. Set `buildkit: true` / `false`
to force it per task. If `secrets` are configured but BuildKit isn't enabled,
coder-eval logs a warning (the build would otherwise fail).
The build context is always appended last, so `extra_args` can't displace it.
## Authentication
> **macOS users — read this first.** Claude Code's OAuth tokens live in the macOS Keychain. The container has no path to the Keychain, so the bundled CLI inside will return `Not logged in · Please run /login` and every task will fail at iteration 1. Before running `--driver docker`, set one of these on the host:
>
> - `ANTHROPIC_API_KEY=...` (direct Anthropic), or
> - `CLAUDE_CODE_USE_BEDROCK=1` + `AWS_BEARER_TOKEN_BEDROCK=...` + `AWS_REGION=...` (Bedrock).
>
> Linux hosts where Claude Code stores creds under `~/.claude` already work because that directory is bind-mounted into the container.
Credentials are forwarded via `--env VAR` (name-only, never embedded in argv) for these vars when set on the host: `ANTHROPIC_API_KEY`, `API_BACKEND`, `UIPATH_*`, `AWS_BEARER_TOKEN_BEDROCK`, `AWS_REGION`, `CLAUDE_CODE_USE_BEDROCK`, `ANTHROPIC_MODEL`.
**To add one or two custom vars to the defaults (recommended)**, use `env_passthrough_extra`:
```yaml
sandbox:
driver: docker
docker:
env_passthrough_extra: ["MY_CUSTOM_TOKEN", "DEBUG_FLAG"] # Keeps all defaults + these
```
**To completely replace the list**, use `env_passthrough`:
```yaml
sandbox:
driver: docker
docker:
env_passthrough: ["MY_CUSTOM_TOKEN", "ANTHROPIC_API_KEY"]
```
### `HOME` is forwarded by default
The default `env_passthrough` includes `HOME` so the in-container `~/.claude` lookup resolves at the same path as on the host (the mount lands at `$HOME/.claude` symmetrically). Practical contract:
- `Path.home()` inside the container returns the host's `HOME` value (e.g. `/Users/you` on macOS). The directory exists in the container because Docker auto-creates it as the mount parent for `~/.claude`.
- `~/.claude` is **not** the host's real dir — the runner makes a throwaway *lean copy* in a tmp dir per task and mounts that copy **read-write** at `$HOME/.claude`. The copy keeps the small set the container needs (auth via `.credentials.json`, `settings.json`, `plugins/`) and **drops heavy or transient per-session state** — `security/` (often hundreds of MB), `projects/`, `cache/`, `file-history/`, `backups/`, `downloads/`, `sessions/`, `telemetry/`, `shell-snapshots/`, `todos/`, `session-env/`, plus the volatile churn dirs the live CLI rewrites. The skip set is a denylist; the authoritative list is `CLAUDE_COPY_IGNORE` in `src/coder_eval/isolation/docker_runner.py` (a test asserts this doc and that constant agree, so the list never silently drifts). The container may write anywhere under `~/.claude`; those writes hit the copy and are discarded when the task ends — the host's real `~/.claude` is never modified. Note the copy includes the OAuth token (`.credentials.json`) and is mounted read-**write**, so the in-container agent can read and tamper with the token *copy* — contained, since the copy is discarded at task end and the host's real dir is untouched. Opt out entirely with `CODER_EVAL_NO_CLAUDE_MOUNT=1`.
- Writes under `$HOME` outside the `~/.claude` mount land in the container's ephemeral rootfs overlay. Don't expect them to persist or to be visible to the host.
- If a tool *detects platform* from `HOME` (e.g. "starts with `/Users/` → macOS"), it will draw the wrong conclusion. Vanishingly rare in practice.
Remove `HOME` from `env_passthrough` if you don't want this behavior — the container's image-default `HOME=/root` will win, but then the host's OAuth dir is no longer reachable.
## Run directory safety (`--run-dir`)
The host's run dir is bind-mounted **read-write** into the container at the same absolute path (so `task.json` and artifacts land directly on the host filesystem). This makes `--run-dir` load-bearing for isolation:
- **Do not** point `--run-dir` at a symlink. Docker resolves the source of a bind mount; following a symlink would silently grant the container RW access to a different host location.
- **Do not** point `--run-dir` at a sensitive parent (e.g. `$HOME` directly, `/etc`, a repo root). Use a dedicated `runs/` subtree.
- The default (`runs//`) is safe.
## Boundary
| Layer | Location |
|---|---|
| Agent process (Claude Code SDK) | inside container |
| Sandbox + per-row criterion checking | inside container |
| **`task.json` serialization** | **container → host bind mount** |
| Per-criterion `aggregate()` (P/R/F1, suite thresholds) | host |
| Reports, run summary, experiment rollups | host |
`task.json` is the only artifact crossing the boundary. Aggregation reads it via the existing host pipeline unchanged.
## Limitations
- **Relative template paths**: `template_sources[].path` is resolved to a host absolute path *before* staging, so it won't exist inside the container unless you also forward the parent dir via `sandbox.docker.extra_mounts`.
- **No container reuse across tasks**: each task = one fresh container. Adds ~1–3 s startup overhead per task; negligible vs. LLM latency.
- **macOS Keychain auth**: not reachable from the container; set `ANTHROPIC_API_KEY` (direct) or Bedrock credentials instead.
## Architecture
The host's `DockerRunner` (`coder_eval/isolation/docker_runner.py`) renders the `docker run` argv, bind-mounts task inputs at `/work/input`, allocates an output dir at `/work/output`, and tails container stdout into `docker.log` in the task's run dir.
If the task declares a `reference:` block, a throwaway **copy** of its directory is bind-mounted **read-write** at `/work/references`, and an empty tmpfs is layered over its original location inside the task-directory mount so the agent cannot reach the solution through `$TASK_DIR`. The mount is read-write on purpose — a `:ro` bind mount cannot be chmod'd (EROFS), and the orchestrator holds this path at mode `000` for the duration of each agent turn. The container also runs with `--cap-drop DAC_OVERRIDE --cap-drop DAC_READ_SEARCH` (see the caveat below for why `FOWNER`/`CHOWN` are deliberately kept).
> **What this does and does not guarantee.** The mode-000 window stops an agent
> that *passively reads* the reference — `ls`, `cat`, `grep` all fail. Two
> things it does **not** stop:
>
> 1. **A deliberate re-chmod.** `chmod(2)` is gated on *owner-or-`CAP_FOWNER`*,
> and the container runs as root, which owns the bind-mounted copy. Verified:
> `chmod 755 /work/references` succeeds from inside the container and the
> solution is then readable. Dropping `FOWNER`/`CHOWN` does **not** fix this
> and is deliberately not done — the in-container orchestrator that *applies*
> the window is the same root process with the same capabilities, so dropping
> `FOWNER` breaks the harness's own `chmod` wherever the bind mount preserves
> a non-root owner (native Linux). Verified: container root, uid-1000-owned
> directory, `FOWNER` dropped → `chmod: Operation not permitted`. The drop
> only bites on the hosts where it also disables the control.
> 2. **Waiting the window out.** The window spans `agent.communicate`, so
> between turns and after the final one the reference is back at its normal
> mode, and nothing reaps the agent's child processes at turn end — a
> backgrounded read loop started during a turn succeeds once the window
> closes.
>
> The *write* half of (2) IS closed: the reference tree is hashed at staging
> time and re-verified before grading, and a mismatch fails the run with
> `ReferenceTamperedError` rather than scoring `reference_comparison` against a
> file the agent wrote. **Closing the read half fully requires running the agent
> as a non-root uid that does not own the reference, and holding the window for
> the agent's whole lifetime** — tracked as follow-up. Treat the current control
> as raising the cost of accidental leakage, not as a boundary against an
> adversarial agent.
See [Reference Solutions](https://coder-eval.com/docs/task-definition-guide#reference-solutions).
Inside the container, the entrypoint invokes `coder-eval _run-task-internal` (hidden subcommand), which loads the staged YAML + context, runs the standard in-process Orchestrator (driver auto-coerced back to `tempdir`), and writes `task.json` to the output mount. Host reads it and feeds the existing aggregation pipeline.
A `result_kind` discriminator on `CriterionResult` ensures `ClassificationCriterionResult` subclasses survive the JSON round-trip — without it, host-side aggregation would silently lose `observed_label`/`expected_label`.
---
# CI Gate: GitHub Action & JUnit reports
Coder Eval ships a **packaged CI gate**: a composite GitHub Action — on the
Actions Marketplace as
[**coder_eval**](https://github.com/marketplace/actions/coder_eval) — that
installs the CLI, runs your tasks, emits a JUnit XML report, appends the run
summary to the job summary, and fails the build on any task/gate failure. This
page is the reference for the Action and the JUnit output. For a walkthrough
(including a hand-rolled workflow), see
[Tutorial 02 — Running Coder Eval in CI](https://coder-eval.com/docs/tutorials/02-ci-pipeline).
## The GitHub Action
The action is published on the GitHub Actions Marketplace as
[**coder_eval**](https://github.com/marketplace/actions/coder_eval). It is a
composite action living at the repo root (`action.yml`), so you reference it by
repo path — there is no Marketplace install step:
```yaml
- uses: actions/setup-node@v4 # the claude-code agent needs the Claude CLI…
with: { node-version: '20' }
- run: npm install -g @anthropic-ai/claude-code
- uses: UiPath/coder_eval@v0 # …then run the gate (@v1 once 1.0.0 ships; @vX.Y.Z pins exactly)
with:
tasks: tests/tasks/*.yaml tests/tasks/*/*.yaml
model: claude-sonnet-5
env: |
ANTHROPIC_API_KEY=${{ secrets.ANTHROPIC_API_KEY }}
```
The first two steps are there because the action is **agent-agnostic** — it
installs `coder-eval` but *not* any coding-agent runtime. Tasks using the default
`claude-code` agent need the `claude` CLI on `PATH` (Node +
`@anthropic-ai/claude-code`), provided by your job *before* the action runs; swap
those steps for your own agent's runtime as needed.
### Inputs
| Input | Default | Purpose |
| --- | --- | --- |
| `tasks` | — | Task YAML path(s)/glob(s) passed to `coder-eval run`. Effectively required — see below. |
| `tags` | — | Only run tasks matching these comma-separated tags (`--tags`). |
| `model` | — | Override agent model for all tasks (`--model`). |
| `extra-args` | — | Extra args appended verbatim to `coder-eval run` (`--experiment`, `-D …`, `--exclude-tags`, …). Trusted caller input. |
| `version` | pinned release | `coder-eval` version to install from PyPI, or `local` to install from the action checkout. |
| `run-dir` | `runs/ci` | Run directory (`--run-dir`). |
| `junit-path` | `coder-eval-junit.xml` | Where to write the JUnit XML report. |
| `step-summary` | `true` | Append `run.md` to the GitHub job summary. |
| `env` | — | Credential/backend passthrough (see below). |
| `minimum-task-score` | *(off)* | Optional strict per-task score floor (see below). |
#### Writing the `tasks` glob
Always pass `tasks` explicitly, and spell out each depth you actually have:
```yaml
tasks: tests/tasks/*.yaml tests/tasks/*/*.yaml
```
Three sharp edges make that worth the words:
- **Omitting `tasks` does not run everything.** The value is shell-expanded into the
`coder-eval run` argument list, so an empty one invokes the CLI with no paths — and
zero-argument discovery resolves against the *installed package's* location, not your
checkout. It finds nothing and exits 1.
- **Do not use `**`.** The expansion happens with `globstar` off, so
`tests/tasks/**/*.yaml` collapses to `tests/tasks/*/*.yaml` and **silently drops every
top-level task** — the gate goes green having never run them.
- **Only list depths that match.** `nullglob` is off too, so a pattern matching nothing
reaches the CLI verbatim and fails the run with
`Error: Task file not found: tests/tasks/*/*/*.yaml`.
An explicit file list is always safe, and is the better choice for a small suite.
### Outputs
| Output | Description |
| --- | --- |
| `run-dir` | The run directory containing `run.json` / `run.md`. |
| `junit-path` | Path to the written JUnit XML report. |
### Credentials via `env`
**`env` is the sole channel for credentials and backend config.** It takes
newline-separated `NAME=VALUE` pairs, exported for the `coder-eval` process
**only** — scoped to the run step, never written to `$GITHUB_ENV`, so a forwarded
secret can't bleed into later job steps. Names must match
`^[A-Za-z_][A-Za-z0-9_]*$`; blank lines and `#` comments are ignored. Always wire
values from repository secrets — never inline a secret literal.
```yaml
- uses: UiPath/coder_eval@v0
with:
tasks: tests/tasks/*.yaml tests/tasks/*/*.yaml
env: |
ANTHROPIC_API_KEY=${{ secrets.ANTHROPIC_API_KEY }}
API_BACKEND=direct
```
Set whatever the run needs — `ANTHROPIC_API_KEY`, `API_BACKEND`, Bedrock/model
vars, `GEMINI_API_KEY` for Antigravity, `EVALBOARD_*`, plugin paths, etc. See the
[User Guide → Environment Variables](https://coder-eval.com/docs/user-guide#environment-variables) and the
per-agent guides ([Claude Code](https://coder-eval.com/docs/agents/claude-code) · [Codex](https://coder-eval.com/docs/agents/codex) ·
[Antigravity](https://coder-eval.com/docs/agents/antigravity)) for what each backend needs.
### The score floor (`minimum-task-score`)
An **additional** gate on top of `coder-eval`'s own exit code. Set a float in
`[0.0, 1.0]` and the step fails if **any** scored task, in any variant, has a
`weighted_score` below it — *or* if `coder-eval` itself exits non-zero (both
verdicts surface). It reads the always-written `run.json` spine
(`task_results[*].weighted_score`), so it works for plain and experiment runs
alike. Errored tasks (null score) are left to `coder-eval`'s exit code; a
malformed/`NaN` score fails closed. Empty (the default) disables the floor.
### Security
Evaluated tasks execute agent-generated code. **Do not** run this action under
`pull_request_target` with secrets exposed to untrusted fork PRs. For untrusted
tasks, use the [Docker driver](https://coder-eval.com/docs/docker-isolation) — the `tempdir` driver is not
a security boundary.
> The README's [Use as a GitHub Action](https://github.com/UiPath/coder_eval#use-as-a-github-action)
> section carries the same reference alongside a copy-paste workflow.
## JUnit XML output
Any run can emit a JUnit XML report — the lingua franca CI platforms understand for
per-test annotations, history, and flake tracking. Two entry points, one code path
(so they can't drift):
```bash
# During a run
coder-eval run tasks/*.yaml --junit-xml coder-eval-junit.xml
# After the fact, from a finished run dir
coder-eval report runs/latest -f junit # writes runs/latest/junit.xml
coder-eval report runs/latest -f junit -o out.xml # custom path
```
The report is built **from the finalized run directory on disk** — the `run.json`
spine (required), any `suite.json` gates (optional), and per-failed-row `task.json`
for failure detail (best-effort). Each task result maps to a JUnit `testcase`;
failures/errors carry a (capped) detail body, and statuses map through
`FinalStatus.category` (`succeeded` / `failed` / `error`). See the
[Report Schema](https://coder-eval.com/docs/report-schema) for the underlying fields.
### Ingesting the report
**GitHub Actions** — [`mikepenz/action-junit-report`](https://github.com/mikepenz/action-junit-report):
```yaml
- uses: mikepenz/action-junit-report@v5
if: always()
with:
report_paths: coder-eval-junit.xml
```
**Azure DevOps** — `PublishTestResults@2`:
```yaml
- task: PublishTestResults@2
inputs:
testResultsFormat: 'JUnit'
testResultsFiles: 'coder-eval-junit.xml'
```
## See also
- [Tutorial 02 — Running Coder Eval in CI](https://coder-eval.com/docs/tutorials/02-ci-pipeline) — the walkthrough
- [Report Schema](https://coder-eval.com/docs/report-schema) — the JSON the JUnit report is built from
- [User Guide](https://coder-eval.com/docs/user-guide) — the `run` / `report` commands and environment variables
---
# Claude Code plugin
Coder Eval ships as a **Claude Code plugin**, so the whole loop — scaffold a
suite, author a task, check whether a skill triggers, read the results, wire it
into CI — happens inside the agent instead of in a separate terminal.
The `UiPath/coder_eval` repository is itself the plugin marketplace:
```
/plugin marketplace add UiPath/coder_eval
/plugin install coder-eval@coder-eval
```
The first command registers the repository as a marketplace; the second installs
the one plugin it hosts. Marketplace and plugin share the name `coder-eval`,
which is why the install target reads `coder-eval@coder-eval`.
## Prerequisite
**Installing the plugin does not install the CLI.** A plugin ships skills and
references, not packages, so the `coder-eval` binary is a separate step:
```bash
uv tool install coder-eval # or: pip install coder-eval
```
You do not have to do it in advance. `init`, `task` and `check-skill` — the three
skills that shell out to the CLI — check `coder-eval --version` before doing any
work and, if it is missing, **offer to install it and ask first**. They never
install unprompted: that writes outside your repository, so it is your call, and
they verify the install worked before continuing. `analyze` and `ci` do not invoke
the CLI, and `lint-tasks` needs neither the CLI nor credentials — it only reads
files, though the report it produces ends by suggesting you run `coder-eval plan`
yourself.
Running a suite additionally needs credentials for whichever agent the tasks use —
`ANTHROPIC_API_KEY` for the default `claude-code` agent.
## The six skills
| Command | What it does |
| --- | --- |
| `/coder-eval:init` | Scans the repository for what is worth evaluating (Claude Code skills, an MCP server, a CLI), reports the findings, then scaffolds a task directory with one real task. |
| `/coder-eval:check-skill` | Builds and runs an activation suite for one of your skills — does the agent engage it when it should, and leave it alone when it shouldn't? |
| `/coder-eval:task` | Turns a natural-language description into task YAML with criteria that check output *content*, validated through `coder-eval plan`. |
| `/coder-eval:lint-tasks` | Reviews task YAML that already exists and reports, per task, criteria that cannot fail, prompts that leak the answer, fixtures with no cleanup and near-duplicates — each with a severity and a fix. Read-only. |
| `/coder-eval:analyze` | Reads a finished run directory and writes `analysis.md`: systemic failure patterns, per-task findings, and concrete fixes. |
| `/coder-eval:ci` | Emits a GitHub Actions workflow that runs the suite as a gate, or on a schedule to catch skill drift. |
`init` and `ci` are explicit-invocation only — scaffolding a directory or writing
a workflow is never something to do unprompted. The other four can also be
reached by the agent on its own when a request clearly calls for them.
`task` and `lint-tasks` are two halves of the same concern and share one bundled
rubric: `task` applies it to work it is writing, `lint-tasks` applies it to files
you already have. They are separate skills because authoring needs `Write` and a
review pass should not have it, and frontmatter declares tool policy per skill —
so one skill cannot hold both stances.
`lint-tasks` expresses read-only three ways, and it is worth being precise about
what each buys, because only the last one spans a whole review: its
`allowed-tools` lists just `Read`, `Glob` and `Grep`; its `disallowed-tools` names
every write tool, which removes them from the pool **for the invoking turn only** —
the restriction clears when you send your next message, and the skill asks you one
before linting a whole directory; and its own instructions carry a standing
prohibition on modifying a file, which is what actually holds for the rest of the
review.
## Worked example: does my skill actually trigger?
A skill is selected almost entirely from its frontmatter `description`. Whether
that description wins the requests it should — and loses the ones it shouldn't —
is invisible until a user complains. `check-skill` turns it into a number.
Point it at a skill:
```
/coder-eval:check-skill .claude/skills/pdf-forms
```
It then:
1. reads the skill's frontmatter `description` — the string the model actually
matches on;
2. designs **positive** rows (requests the description claims to cover,
paraphrased — never lifted from the description, which would test string
overlap rather than activation) and **distractor** rows (adjacent requests the
skill should decline, especially ones sharing its vocabulary);
3. copies the bundled activation template into your task directory as a
[dataset-backed task](https://coder-eval.com/docs/datasets) — one row per request, each scored by the
[`skill_triggered`](https://coder-eval.com/docs/task-definition-guide) criterion;
4. validates with `coder-eval plan`, tells you the row count and the cost
implication, and asks before running;
5. reports recall, precision, F1 and the confusion matrix — then interprets them:
low precision means the description over-claims and is stealing adjacent
requests; low recall means it under-claims **once truncation and listing
eviction are ruled out** (see below).
One prerequisite the suite cannot infer: the evaluated agent runs in a fresh
sandbox holding none of your files, so it is offered no skills unless the task
says where they live. The template reads that location from an environment
variable — point it at a **plugin root**: a directory holding a `skills/`
subdirectory, so the skill sits at `/skills//SKILL.md`. For
`.claude/skills/pdf-forms/SKILL.md` that root is `.claude`, not `.claude/skills`:
```bash
export SKILL_SOURCE_PATH="$(pwd)/.claude"
```
Leave it unset and the skill is simply absent, every positive row scores 0, and
the result is indistinguishable from a skill that never fires. It stays an
environment variable rather than a path baked into the YAML so the suite is
portable — it is committed and re-run on other machines, and in CI.
### A low-recall result has three causes, not one
Two of them are budgets rather than wording, and both produce a number that looks
exactly like a badly written description:
- **Per-skill truncation.** `description` and `when_to_use` are concatenated and
cut at 1,536 characters (configurable via `skillListingMaxDescChars`). Trigger
text past the cutoff cannot affect activation at all.
- **Whole-listing eviction.** The skill listing's character budget scales at about
1% of the model's context window and is shared with *every* skill you have
installed. On overflow, descriptions are dropped **starting with the skills you
invoke least** — so a newly authored skill, which is by definition rarely
invoked, is the likeliest casualty. That is a systematic bias against exactly
the skill you are testing.
Check both before rewriting anything: `/doctor` estimates the listing's context
cost and its biggest contributors, and the Skills row in `/context` reports the
listing size *after* the budget is applied — what the model actually received.
Only once the description is demonstrably in the listing is the wording the
culprit.
The suite is a normal task file, so it stays in your repository and can be re-run
after every description edit — which is the point. Editing skill wording without
a suite is guesswork; with one, the change either moves recall or it doesn't.
Because the suite is gated on `suite_thresholds` (`recall.yes`, `precision.yes`),
it also works as a CI gate: run it on a schedule and a skill that quietly stops
triggering — because the model changed, or someone reworded the description —
fails a build instead of surprising a user.
## Adopting this where coder-eval already exists
The skills are written for a repository that already has a suite, not only for an empty
one. Three things follow from that, and they are worth knowing before you install:
- **They discover; they do not assume.** Nothing looks for `tasks/` or `runs/latest` by
name. A skill globs for YAML carrying a `task_id:` key and for `run.json`, reports the
tree it resolved, and asks when a monorepo offers more than one. Call your eval tree
`evals/`, or nest the whole thing under `tests/`, and the skills follow it.
- **They will not scaffold over what you have.** `init` run against a configured
repository reports the inventory and stops, pointing at `lint-tasks` and `analyze`
instead. `check-skill` looks for a suite that already covers the skill and offers to
extend it rather than writing a second one. And where your repository pins a
coder-eval version, the CLI-driving skills resolve that pin first and stop on a
mismatch rather than validating with the wrong binary — a schema error from a
mismatched CLI is indistinguishable from a real one.
- **Your own tooling stays authoritative.** If you already have slash commands or a CI
workflow covering the same ground, these skills are additive. The naming keeps them
apart: plugin skills are always namespaced `/coder-eval:`, while a repo-local
command in your own `.claude/commands/` keeps whatever name you gave it. Where both
exist, prefer yours — it knows things the plugin cannot.
`task` applies the same rule to authoring: it reads whatever your repository declares
about writing tasks and follows it, and reports which conventions it adopted. The bundled
rubric is a check of last resort, for what no local rule covers.
## What ships with the plugin
An installed plugin is copied to `~/.claude/plugins/cache/` without its parent
directories, so every file a skill reads travels with it under `reference/`:
- `criteria.md` — every criterion type and its fields, **generated** from Coder
Eval's own `SuccessCriterion` model union (`make plugin-reference`), so it
cannot drift from the schema the CLI validates against.
- `task-rubric.md` — the adversarial task-quality checklist `task` applies to work it
writes and `lint-tasks` applies to task files already on disk: could this task pass for
the wrong reason, does it grade behavior or a self-report, do its fixtures reset and
clean up.
- `cli-setup.md` — how the CLI-driving skills handle a missing `coder-eval`
binary: offer the install, ask first, verify it worked.
- `run-layout.md` — the on-disk run-directory contract `analyze` reads: what is *inside*
a run directory.
- `repo-layout.md` — how a skill finds *where* your eval tree is, by globbing for
`task_id:` files and `run.json` rather than assuming `tasks/` and `runs/`. All six
skills read it, which is what lets them work in a repository that names or nests the
tree differently.
- `templates/` — the canonical activation suite `check-skill` copies.
## Related
- The plugin's own README lives at
[`plugins/coder-eval/README.md`](https://github.com/UiPath/coder_eval/blob/main/plugins/coder-eval/README.md).
- For the GitHub Action the `ci` skill emits — its inputs, JUnit output and score
floor — see [CI Gate & GitHub Action](https://coder-eval.com/docs/ci-gate).
- For the criterion vocabulary in full, see the
[Task Definition Guide](https://coder-eval.com/docs/task-definition-guide).
---
# Extending Coder Eval
Coder Eval is extensible along three seams, all designed so a third party can add
capability **without editing the base package**:
1. **Agents** — register a new `agent.type` via the plugin SPI.
2. **Criteria** — add a new success-criterion type via a decorator + auto-discovery.
3. **Pricing** — contribute USD rates for models your plugin runs.
This guide covers all three. For the internal architecture notes see
[CLAUDE.md](https://github.com/UiPath/coder_eval/blob/main/CLAUDE.md).
---
## 1. Custom agents (the plugin SPI)
Agents register through the **`coder_eval.plugins` entry-point group** — there is no
closed enum or dispatch to edit. `agent.type` is an open string validated against
the `AgentRegistry`; built-in and third-party agents travel the exact same path.
### Wire up the entry point
In your plugin package's `pyproject.toml`:
```toml
[project.entry-points."coder_eval.plugins"]
my_plugin = "my_plugin:register"
```
At CLI init, `load_plugins()` imports each entry point and calls it with the
`AgentRegistry` **class** (not an instance). A third-party hook that raises is logged
and skipped; only a failing *built-in* registration is fatal.
### The `register` hook
```python
from coder_eval.agents.registry import AgentRegistry
def register(registry: type[AgentRegistry]) -> None:
# Bind type string → config class → agent class.
registry.register("my-agent", MyAgentConfig)(MyAgent)
# Optionally contribute pricing here too (see §3):
# register_pricing(MY_RATES)
```
`AgentRegistry.register(agent_kind, config_class)` returns a decorator, so the
decorator form works too:
```python
@AgentRegistry.register("my-agent", MyAgentConfig)
class MyAgent(Agent[MyAgentConfig]):
...
```
Registration is **anti-shadow**: re-registering the same `(agent_class,
config_class)` pair is a no-op, but claiming an existing `agent.type` with a
*different* implementation raises `ValueError`. Two plugins can never silently fight
over one type.
### The config class
Subclass `BaseAgentConfig` with your own `type` discriminator:
```python
from typing import Literal
from coder_eval.models import BaseAgentConfig # importable from coder_eval.models
class MyAgentConfig(BaseAgentConfig):
type: Literal["my-agent"] = "my-agent"
my_option: str = "default"
```
The factory `create_agent(kind, config, …)` raises `TypeError` if the passed config
isn't an instance of the registered `config_class`, so keep them paired.
### The `Agent` ABC — implementation checklist
Implement these three abstract methods:
- [ ] `async def start(self, working_directory, *, env_path_prepend=None, plugin_tools_dir=None) -> None`
- [ ] `async def communicate(self, user_input, *, stream_callback=None, timeout=None, max_turns=None, should_stop=None) -> TurnRecord`
- [ ] `async def stop(self) -> None`
Optional overrides (sensible defaults exist): `kill()`, `kill_sync()` (called from a
non-asyncio watchdog thread — must **not** await), `discard_pending_turn()`.
Follow the shared turn lifecycle (do **not** hand-assemble a `TurnRecord`):
- [ ] Call `self._begin_turn()` at the top of `communicate()`.
- [ ] Call `self._end_turn_ok()` on the success path.
- [ ] Call `self._mark_stopped()` in `stop()` after your own teardown.
- [ ] Before raising on a mid-turn failure, set `self.pending_turn` to a
`crashed=True` `TurnRecord` (built from an `EventCollector`), then raise
`AgentCrashError` / `TurnTimeoutError` (bare — no payload). The orchestrator
drains it and calls `discard_pending_turn()`.
Emit the standardized event protocol (you are the **sole emitter**): one
`AgentStartEvent` at the top of `communicate()` and one matching `AgentEndEvent` on
**every** exit path (emit from `finally`), a `TurnStart`/`TurnEnd` pair per inner
turn, and `ToolStart`/`ToolEnd` per tool call (close orphaned tools with
`status=unresolved`). Fan events through an internal `EventCollector` — it builds the
returned `TurnRecord`, the single agent-agnostic capture path.
Set `supports_cooperative_stop: ClassVar[bool] = True` only if your `communicate()`
actually honors `should_stop` (needed for criterion-level `stop_early:` arming). Leaving it
`False` means early stop is rejected at resolution for your agent — which is correct
if you can't stop cooperatively.
### Worked example
The in-tree worked example is the BYOA test fixture at
[`tests/fixtures/byoa_demo_plugin/`](https://github.com/UiPath/coder_eval/tree/main/tests/fixtures/byoa_demo_plugin)
— a minimal package with a `register` hook and the `coder_eval.plugins` entry point.
(It subclasses `ClaudeCodeAgent` for brevity; a real third-party agent implements the
`Agent` ABC from scratch.)
---
## 2. Custom success criteria
Criteria are discovered automatically by `pkgutil` scan of the `coder_eval.criteria`
package — a new checker just needs the `@register_criterion` decorator. Adding one is
two steps: a Pydantic **model** (the YAML schema) and a **checker** (the logic).
### Step 1 — the model
In `models/criteria.py`, subclass `BaseSuccessCriterion` and set the discriminator as
a `Literal` default, then add it to the `SuccessCriterion` union:
```python
class MyCriterion(BaseSuccessCriterion):
type: Literal["my_criterion"] = "my_criterion"
target: str
# Set requires_agent = True (ClassVar) if you read turn_records.
# ...and add `| MyCriterion` to the SuccessCriterion discriminated union.
```
Union membership is required — a run validates that every union member's `type` has a
registered checker, and rejects unknown `type` tags in YAML. `BaseSuccessCriterion`
gives you `description`, `weight` (default 1.0; `0` = informational/non-gating),
`pass_threshold` (default 0.9) and `suite_thresholds` for free, with
`extra="forbid"` so YAML typos are caught.
### Step 2 — the checker
Drop a file in `coder_eval/criteria/` with a `@register_criterion` class:
```python
from coder_eval.criteria.base import BaseCriterion, register_criterion
from coder_eval.models import CriterionResult
@register_criterion
class MyChecker(BaseCriterion[MyCriterion]):
criterion_type = "my_criterion" # must match the model discriminator
def _check_impl(self, criterion, sandbox, *,
turn_records=None, context=None) -> CriterionResult:
# `context` carries the live run state: `context.route` (for criteria
# that call a model) and `context.reference_dir` (the staged reference
# copy, for criteria that grade against a reference solution).
ok = ... # your logic
return CriterionResult(
criterion_type=self.criterion_type,
description=criterion.description,
score=1.0 if ok else 0.0,
details="...",
)
```
Notes:
- **Do not override `check()` / `check_async()`** — both are `@final` and wrap
`_check_impl` / `_check_impl_async` with error handling (an exception becomes
a score-0.0 result with the error captured; a `JudgeInfrastructureError`
escalates instead).
- Implement exactly ONE of `_check_impl` (plain sync — the common case, shown
above) or `_check_impl_async` (genuine async I/O — an async HTTP client or
subprocess bridge; see `llm_judge`/`agent_judge`). Whichever you implement,
`BaseCriterion` derives the other for free (`asyncio.to_thread` / `asyncio.run`),
so there is no need to hand-maintain both. Overriding neither, or overriding
BOTH, raises `TypeError` immediately at class-definition time (a shared
abstract base for a family of checkers that intentionally implements neither
can opt out with the `abstract=True` class keyword — every one of ITS
subclasses is still checked normally). `SuccessChecker.check_all_async`
— the orchestrator's entry point — awaits every `_check_impl_async`-native
checker directly on the event loop instead of pinning a thread, and offloads
everything else to `asyncio.to_thread`. Criteria currently run SEQUENTIALLY
(strictly in declaration order, matching the sync `check_all`); running
multiple judge criteria concurrently is a follow-up.
- If your checker overrides `_check_impl_async`, it MUST NOT do blocking work
(file I/O, subprocess calls) directly on the event loop — that would stall
the orchestrator's own loop for the duration of the call. Offload blocking
calls with `await asyncio.to_thread(...)` (see `llm_judge`/`agent_judge`,
which do this for their sandbox/reference file reads).
- The derived sync bridge (`_check_impl`'s default `asyncio.run(...)` call) can
only run when no event loop is already running — calling the public sync
`check()`/`check_all()` on an async-only checker from inside a running loop
raises `CheckerMisuseError` (escalates, like `JudgeInfrastructureError`)
rather than returning a wrong score. Always reach for `check_async()` /
`check_all_async()` from async code.
- Return `score` in `[0.0, 1.0]` — binary criteria use `0.0`/`1.0`; fractional ones
anything in between.
- For **suite-level metrics** on dataset-backed tasks, override
`aggregate(criterion, per_row_results)`; the base emits
`count/mean/median/std/min/max`, so your criterion is suite-thresholdable for free.
Classification-style criteria return a `ClassificationCriterionResult` and layer
accuracy / precision / recall / F1 / confusion on top.
- For **early stop**, make your criterion model subclass `LiveSuccessCriterion`
(`models/criteria.py`) instead of `BaseSuccessCriterion`, implement its
abstract `live_decidable_polarities()` (a pure function of the criterion's
own fields — no `turn_records`, no checker instance), and override the
checker's `live_verdict(...)`. `LiveSuccessCriterion` subclassing is the
single source of truth for "is this criterion type live-observable" —
`validate_early_stop`/`EarlyStopWatcher` check `isinstance(c,
LiveSuccessCriterion)` directly, no separate checker-side flag. A lint rule
(`tests/test_custom_lint.py::TestCE025LiveVerdictConsistency`) keeps the
model subclassing and the checker's `live_verdict` override paired.
- Your `live_verdict` must be **deterministic** (a pure function of the
`turn_records` prefix — no wall-clock, randomness, or hidden instance state)
and **monotonic** (once it returns `"pass"`/`"fail"` for some prefix, every
longer prefix returns that same verdict) — `EarlyStopWatcher`'s verdict
latching and deferred stops silently depend on both. Lint rule CE036
(`tests/lint/live_verdict_contract.py`) enforces this by replaying each live
criterion against every prefix of recorded trajectories, and **fails until
you add `ContractCase` fixtures** for the new type in the same change,
reaching every polarity its instances claim via
`live_decidable_polarities()`. An out-of-tree plugin criterion is invisible
to CE036's union walk — and the module lives under `tests/`, which is not
shipped in the PyPI wheel — so copy the replay pattern (a `ContractCase`-style
fixture plus the prefix-by-prefix determinism/monotonicity walk) into your
plugin's own test suite, using `tests/lint/live_verdict_contract.py` in this
repo as the reference implementation.
> A duplicate `criterion_type` **overwrites** the earlier checker with a warning (not
> a hard error, unlike agents) — keep type strings unique.
---
## 3. Model pricing
Plugins that run their own models contribute USD rates through `register_pricing` —
there is **no** separate entry-point group; call it from the same `register()` hook.
```python
from coder_eval.pricing import ModelPricing, register_pricing
# Rates are per MILLION tokens: (input, output, cache_write, cache_read)
MY_RATES = {
"my-model-v1": ModelPricing(3.0, 15.0, 3.75, 0.30),
"my-free-model": ModelPricing(0.0, 0.0, 0.0, 0.0), # a valid free-model entry
}
def register(registry):
registry.register("my-agent", MyAgentConfig)(MyAgent)
register_pricing(MY_RATES)
```
Behavior:
- **Keys** are the bare model id as it appears in `agent.model` (vendor/Bedrock
region prefixes like `eu.` / `anthropic.` are normalized off at lookup).
- **Idempotent** for identical rates; **raises `ValueError`** on a *conflicting* rate
for an existing key (built-in or another plugin). Registration is all-or-nothing —
a late conflict leaves nothing half-applied.
- **Zero rates are valid** (a genuinely free model) — the lookup uses "is a rate
present", not truthiness, so an all-zero entry prices to `0.0` rather than falling
through to the built-in table.
- The plugin overlay is consulted **before** the built-in table, so every consumer
(agents, reports, the cost simulator) prices your model transparently via
`calculate_cost(model, uncached_input, output, cache_creation=0, cache_read=0)`.
(Pass `uncached_input`, not the total input.)
The base package ships **no** plugin rates; only the built-in table.
---
## See also
- [Claude Code](https://coder-eval.com/docs/agents/claude-code) · [Codex](https://coder-eval.com/docs/agents/codex) ·
[Antigravity](https://coder-eval.com/docs/agents/antigravity) · [OpenCode](https://coder-eval.com/docs/agents/opencode) — the
built-in agents, each registered via this same SPI
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide) — the criterion catalogue
- [CLAUDE.md](https://github.com/UiPath/coder_eval/blob/main/CLAUDE.md) — architecture
and extension points in depth
---
# Report Schema
Coder Eval writes machine-readable JSON alongside every markdown/HTML report. This
page is the field-level reference for consumers (dashboards, CI parsers, evalboard
forks). For the on-disk directory tree see
[User Guide → Output Structure](https://coder-eval.com/docs/user-guide#output-structure); for how to
re-generate these files see [`coder-eval report` / `aggregate`](https://coder-eval.com/docs/user-guide#cli-commands).
All JSON is Pydantic `model_dump_json` output — keys are the model field names
verbatim (no aliases, except `iterations` also accepts the legacy key `turns` on
read). Times are ISO-8601.
## Who writes what
| File | Model | When |
| --- | --- | --- |
| `run.json` / `run.md` | `RunSummary` | Every run (and rebuildable via `coder-eval aggregate`) |
| `///task.json` | `EvaluationResult` | One per replicate |
| `//suite.json` / `.md` | `SuiteRollup` | Dataset-backed suites only |
| `experiment.json` / `.md` | `ExperimentResult` | Every run (experiment layer) |
| `/variant.json` / `.md` | `VariantAggregate` | Per variant |
`` is the zero-padded replicate index. Judge transcripts spill to sibling files
(`judge-N.yaml`, or `post-failure-judge-N.yaml` for diagnostic records) referenced
by a `transcript_path`.
---
## `run.json` — `RunSummary`
**`run.json` is flat, not a `run → variant → task → replicate` tree.** It is the
run-level summary; full per-replicate detail lives in each `task.json`.
| Key | Type | Meaning |
| --- | --- | --- |
| `run_id` | `str` | Timestamp id, e.g. `"2025-10-09_15-30-45"`. |
| `start_time` / `end_time` | `datetime` | Run window. |
| `total_duration_seconds` | `float` | Wall-clock. |
| `tasks_run` | `int` | Total replicates executed. |
| `tasks_succeeded` / `tasks_failed` / `tasks_error` | `int` | Category counts. **Invariant:** the three sum to `tasks_run`. |
| `tasks_token_budget_exceeded` / `tasks_cost_budget_exceeded` | `int` | Sub-counters of `tasks_failed` (not part of the invariant). |
| `skipped_tasks` | `list[{path, reason}]` | Load failures / `skip: true` opt-outs. |
| `max_parallel` | `int` | Concurrency used. |
| `task_results` | `list[dict]` | Flat per-replicate rows — see below. |
| `framework_version` | `str` | Coder Eval version chip. |
| `environment_info` | `dict` | Version/dependency info (may nest, e.g. `tool_plugins`). |
These are **computed**, not stored — derived from the counts and rows above on every
serialization, so they cannot drift from what they summarize. Read them rather than
re-deriving your own; independent re-derivations are how two consumers end up
publishing different numbers for the same run.
| Key | Type | Meaning |
| --- | --- | --- |
| `pass_rate` | `float \| None` | `tasks_succeeded / tasks_run` — errors are in the denominator, counted as misses. `None` on an empty run (0/0 is unknown, not 0%). |
| `error_share` | `float \| None` | `tasks_error / tasks_run`. Diagnostic only; never adjusts the rate. |
| `total_cost_usd` | `float \| None` | **The bill**: agent + judge + simulator, summed over the rows. `None` when nothing could be priced. |
| `agent_cost_usd` | `float \| None` | Subject-agent spend alone. The harness-vs-harness comparison figure — judge spend is a property of the suite's criteria and identical across harnesses, so leaving it in would make two harnesses look closer than they are. |
| `eval_overhead_cost_usd` | `float \| None` | Judge + simulator spend. The other half of `total_cost_usd`. |
| `tasks_cost_incomplete` | `int` | Rows whose recorded spend is missing money (unpriced model, or a hard kill that lost an in-flight turn). |
| `cost_complete` | `bool` | `tasks_cost_incomplete == 0`. When false, every cost figure above is a **floor**, not the bill. A run is never failed for this — see [Missing cost is never fatal](#missing-cost-is-never-fatal). |
### `task_results[]` — the flat per-task row
Each entry is an **untyped dict** (a denormalization, not a Pydantic model) with keys
including: `task_id`, `replicate_index`, `variant_id`, `status`
([`FinalStatus`](#finalstatus)), `weighted_score`, `duration`, `iteration_count`,
`tags`, `task_path`, `model_used`, `reference_similarity`, the token buckets
(`input_tokens` = uncached input, `output_tokens`, `cache_creation_input_tokens`,
`cache_read_input_tokens`, `total_tokens`), the cost fields
(`total_cost_usd` = agent + judge + simulator, plus the `agent_cost_usd` /
`judge_cost_usd` / `simulator_cost_usd` slices and the `cost_complete` flag),
`expected_commands`,
`actual_commands`, `commands_efficiency`, `agent_config`, `sdk_options`,
`installed_tools`, turn accounting (`total_turns`, `visible_turns`, `expected_turns`,
`max_turns_exhausted`, `has_final_reply`), and early-stop fields (`stopped_early`,
`early_stop_reason`, `turns_remaining_at_stop`). `iterations` here is a **reduced**
turn digest (`{iteration, duration_seconds, command_count, assistant_turn_count,
crashed, crash_reason}`) — the full transcript is in `task.json`.
### Missing cost is never fatal
Pricing degrades; the evaluation does not. A model absent from the rate card, a turn
the backend never priced, a hard-killed task that lost its in-flight spend: each one
lowers a total and sets `cost_complete: false`. None of them raises, none of them
books a zero, and none of them changes a run's exit code.
The reasoning is that the two failure modes are not symmetric. A missing cost is
recoverable after the fact — the token counts are on the record, so a corrected rate
card reprices the run from its artifacts. A failed run is not: the tokens are already
spent and the only way back is to run it again. So the framework warns loudly and
keeps going.
The warning fires up front. `check_pricing_coverage` walks every model the run pins
(subject agents and judge criteria) before the first task dispatches, and logs the
ones the card cannot price — early enough to fix the card and restart while it is
still cheap. After that the run is on its own: totals become floors, and
`tasks_cost_incomplete` says how many rows are behind that floor.
Consumers should treat any cost field as a lower bound whenever `cost_complete` is
false, and must not read `None` as `0.0` — "nothing could be priced" and "it was
free" are different facts.
---
## `task.json` — `EvaluationResult`
The authoritative per-replicate record.
**Identity/metadata:** `task_id`, `task_description`, `variant_id` (default
`"default"`), `agent_type`, `model_used`, `started_at`, `completed_at`,
`duration_seconds`.
**Results:**
| Key | Type | Meaning |
| --- | --- | --- |
| `final_status` | [`FinalStatus`](#finalstatus) | Terminal status. |
| `weighted_score` | `float \| null` | Weighted average of criterion scores, 0.0–1.0. |
| `max_turns_exhausted` | `bool` | Ran out of turns. |
| `iteration_count` | `int` | Number of turns. |
| `success_criteria_results` | `list[CriterionResult]` | Per-criterion results — see [below](#criterionresult). |
| `post_failure_criteria_results` | `list[CriterionResult]` | Diagnostic artifact evidence collected after a terminal agent failure. It does not affect `final_status`, `weighted_score`, gating, or suite aggregation. |
**Transcript:** `iterations: list[TurnRecord]` (accepts legacy alias `turns`) — see
[TurnRecord](#turnrecord).
**Errors** (populated on failure): `error_message`, `error_details`,
`error_log_tail` (carries the Docker build-log tail for `BUILD_FAILED`).
**Config/environment:** `environment_info`, `agent_config`, `sdk_options` (raw
`ClaudeAgentOptions` dump), `sandbox_path`, `task_config`
(`{resolved, source_yaml, source_file, lineage}` — `lineage` maps each field to
`{value, source, source_detail}` so you can trace which config layer set it).
`environment_info.system_prompt_semantics` (`"append"` / `"replace"` /
`"unknown"`) records the system-prompt regime the agent ran with. Every agent
emits it — the base `Agent` supplies `"unknown"` for an agent that has not
declared its regime (including out-of-tree plugin agents), so an absent key
means one thing only: a run predating the marker. Those runs used
replace-on-set / empty-on-unset semantics on Claude Code and are not
score-comparable, so consumers should segment on it (absent ⇒ pre-append
regime; `"unknown"` ⇒ current run, undeclared agent). Codex runs before the
marker dropped `system_prompt` entirely and Antigravity always appended, so for
those two the boundary is a reporting change, not a behavioral one.
`sdk_options.system_prompt` is a `SystemPromptPreset` dict
(`{type: "preset", preset: "claude_code", exclude_dynamic_sections: true, append?: str}`)
on append-mode Claude Code runs and a plain string only in replace mode — it is
no longer `str | null`, so consumers must not string-handle it unconditionally.
**Telemetry/totals:** `total_token_usage` ([TokenUsage](#tokenusage)),
`command_stats` (`CommandStatistics`), `total_assistant_turns`, `expected_commands` /
`actual_commands` / `commands_efficiency`, `pre_run_results` / `post_run_results`
(`{command, exit_code, stdout, stderr, duration_seconds, error}`), `simulation`
(dialog-mode telemetry, `null` in single-shot), and `early_stop`
([EarlyStopInfo](#earlystopinfo)).
### CriterionResult
A discriminated union on `result_kind` (`basic` / `judge` / `classification`); legacy
files without `result_kind` are inferred from `criterion_type`. Base fields
(`result_kind="basic"`):
`criterion_type`, `description`, `score` (0.0–1.0), `details`, `error`,
`evaluation_status` (`evaluated` by default; `not_evaluated` means the check did
not run and is distinct from an evaluated 0.0),
`pass_threshold` (default 0.9), `gating` (default `true`; `false` = informational /
weight-0, excluded from the score and the pass/fail gate). The base allows extra
fields so subclass keys round-trip.
- **`classification`** adds `observed_label`, `expected_label` (sentinels like
`(none)` / `(other)` allowed). Emitted by `classification_match`, `skill_triggered`.
- **`judge`** adds `findings`, `token_usage` (kept distinct from the agent total), and
`transcript_path` (a sibling `judge-N.yaml`, or `post-failure-judge-N.yaml` for
diagnostic records). The full `transcript` is **stripped
from `task.json`** — read it from the referenced file. Emitted by `llm_judge`,
`agent_judge`.
### Post-failure criterion evidence
When an agent crashes or its turn times out, coder-eval runs only deterministic,
read-only artifact criteria while the sandbox is still live: `file_exists`,
`file_contains`, `file_matches_regex`, `file_check`, `json_check`,
`reference_comparison`, and `classification_match`. Judges, trajectory checks,
`run_command`, and `uipath_eval` are recorded with
`evaluation_status="not_evaluated"`; they are not invoked on this recovery path.
The diagnostic list is additive evidence. An `ERROR` run remains `ERROR`, and its
canonical score remains 0.0.
### TurnRecord
`iteration`, `user_input`, `agent_output`, `commands` (`list[CommandTelemetry]`),
`timestamp`, `duration_seconds`, `token_usage`, `model_used`, `assistant_turn_count`,
`messages` (`list[TranscriptMessage]`, discriminated on `role`:
`user`/`assistant`/`reconciliation`), `provider_call_costs`
(`list[ProviderCallCost]` — one row per real upstream call with its ACTUAL cost +
cache buckets, captured proxy-side on the LiteLLM open-weight backend and rendered
by the evalboard as a per-call table; empty on every other
backend), `num_turns`, `max_turns_exhausted`,
`result_summary` (`{is_error, subtype, stop_reason, result}`), `crashed`,
`crash_reason`.
> **Token invariant.** Summing the four token buckets across `messages`
> (assistant + the synthetic `reconciliation` entry) equals `token_usage` exactly.
> The `reconciliation` message carries the residual the per-message stream
> under-reports; it has no cost and is excluded from turn/generation counts. The
> LiteLLM actual-cost join writes cost at the TURN level only (`token_usage.total_cost_usd`
> = the real bill) plus the per-call `provider_call_costs` audit record — it does
> NOT touch the message token buckets, so this invariant holds on every backend.
> See the [Claude Code guide](https://coder-eval.com/docs/agents/claude-code#telemetry).
### EarlyStopInfo
Present (non-`null`) iff the run stopped early — there is no separate boolean.
Fields: `reason` (`criterion_passed` / `criterion_failed` /
`decision_budget_exceeded` — the last marks a fail-stop whose deciding
criterion timed out undecided past its `stop_early.decide_within`; it gates through
the same weighted armed gate as a native fail),
`deciding_criterion_type`, `deciding_criterion_description`, `armed_criteria`,
`sdk_turn_index`, `tool_call_index` (1-based, includes the in-flight call),
`elapsed_seconds`, `turns_remaining_at_stop`, `gate_threshold` (the
`run_limits.stop_early_gate_threshold` in effect for this stop; default `1.0`).
---
## `variant.json` — `VariantAggregate`
A single aggregate (not wrapped): `variant_id`, `tasks_run`, `tasks_succeeded`,
`tasks_failed`, `tasks_error` (same sum-to-`tasks_run` invariant), `average_score`,
`average_duration`, `total_tokens`, `replicate_count`, `tasks_token_budget_exceeded`,
`tasks_cost_budget_exceeded`.
## `experiment.json` — `ExperimentResult`
The cross-variant summary:
- `experiment_id`, `description`, `variant_ids`.
- `task_summaries: list[TaskExperimentSummary]` — each
`{task_id, variant_results, best_variant, is_tie, score_spread, replicate_count}`,
where each `VariantResult` carries `{variant_id, task_id, weighted_score,
final_status, duration_seconds, total_tokens, iteration_count,
total_assistant_turns, reference_similarity, replicate_index, replicate_count}`.
- `variant_aggregates: dict[str, VariantAggregate]` — keyed by variant id.
- `total_duration_seconds`.
- `per_replicate_scores: dict[variant_id -> dict[task_id -> list[float]]]`.
> **Statistics are render-time only.** Bootstrap/Wilson confidence intervals and the
> Welch/paired mean-difference tests appear in `experiment.md` / HTML but are **not**
> serialized into `experiment.json`. A consumer that wants CIs must recompute them
> from `per_replicate_scores`.
## `suite.json` — `SuiteRollup`
Written for dataset-backed suites; its `passed` flag drives the CI exit code.
| Key | Type | Meaning |
| --- | --- | --- |
| `suite_id` / `variant_id` | `str` | Identity. |
| `rows_total` / `rows_passed` / `rows_failed` / `rows_error` | `int` | Row counts. |
| `pass_rate` | `float` | `rows_passed / rows_total`. |
| `average_weighted_score` | `float \| null` | Mean row score. |
| `criterion_stats` | `list[{criterion_type, rows_evaluated, average_score, error_count}]` | Per-criterion summary. |
| `failed_samples` | `list[FailedRowSummary]` | Capped at 20 (`{row_id, task_id, final_status, weighted_score, failure_reasons, error_message, task_json_relpath, replicate_index}`). |
| `criterion_aggregates` | `list[CriterionAggregate]` | The thresholdable metrics — see below. |
| `passed` | `bool` | All aggregates met their thresholds. |
### CriterionAggregate & ThresholdCheck
`CriterionAggregate`: `criterion_type`, `description`, `rows_total`, `rows_excluded`,
`metrics` (a **flat** `dict[str, float]`, e.g. `accuracy`, `macro_f1`,
`precision.yes`, `recall.yes`, `f1.yes`), `threshold_checks`, `passed`, `details`
(untyped render extras — for classification: `labels`, `per_label`, `confusion`),
`error`.
`ThresholdCheck`: `metric`, `min_value`, `actual_value` (`null` if the aggregator
didn't emit that metric), `passed` (`actual_value >= min_value`). These correspond to
the `suite_thresholds` you set on a criterion — see
[User Guide → Suite Thresholds](https://coder-eval.com/docs/user-guide#suite-thresholds--classification-metrics).
---
## TokenUsage
Serialized fields: `uncached_input_tokens`, `output_tokens`,
`cache_creation_input_tokens`, `cache_read_input_tokens`, `total_cost_usd`, plus a
computed **`input_tokens`** (= sum of the three input buckets). Note: `total_tokens`
is a plain property and is **not** serialized. Cost bills `uncached_input_tokens`,
not `input_tokens`. Legacy files that only have `input_tokens` are adopted as
`uncached_input_tokens` on read.
## FinalStatus
String enum values and their reporting category:
| Value | Category | Icon |
| --- | --- | --- |
| `SUCCESS` | succeeded | `+` |
| `FAILURE` | failed | `-` |
| `TIMEOUT` | failed | `T` |
| `MAX_TURNS_EXHAUSTED` | failed | `M` |
| `TOKEN_BUDGET_EXCEEDED` | failed | `#` |
| `COST_BUDGET_EXCEEDED` | failed | `$` |
| `ERROR` | error | `!` |
| `BUILD_FAILED` | error | `B` |
> **Gotcha:** `BUILD_FAILED` (a failed Docker image build) categorizes as **error**,
> not failed — easy to miscount downstream.
`TOKEN_BUDGET_EXCEEDED` and `COST_BUDGET_EXCEEDED` are produced by the cumulative budget caps under
`run_limits:` (`max_input_tokens` / `max_output_tokens` / `max_total_tokens`, and `max_usd`
respectively), checked after each completed agent turn — see
[Task Definition Guide → Run Limits](https://coder-eval.com/docs/task-definition-guide#run-limits).
---
## Consumer gotchas at a glance
- `run.json.task_results` is a flat, untyped denormalization — the typed source of
truth is each `task.json`.
- Experiment CIs / significance tests are **not** in `experiment.json` (render-time
only); recompute from `per_replicate_scores`.
- Judge `transcript` is stripped from `task.json`; follow `transcript_path`.
- `TokenUsage.total_tokens` is not serialized; sum the buckets (or use the computed
`input_tokens` + `output_tokens` + cache buckets).
- `EarlyStopInfo` presence is itself the "stopped early" signal.
- `total_cost_usd` is the whole bill (agent + judge + simulator) at both row and run
level; `agent_cost_usd` is the agent-only slice. `TokenUsage.total_cost_usd` is a
different thing: the cost of those tokens, so always agent-only. `run_limits.max_usd`
gates on that one, since judge and simulator spend is not known mid-run.
- A cost of `None` means unpriced, not free, and any total is a floor while
`cost_complete` is false — see [Missing cost is never fatal](#missing-cost-is-never-fatal).
## See also
- [User Guide → Output Structure](https://coder-eval.com/docs/user-guide#output-structure) and the
[`aggregate`](https://coder-eval.com/docs/user-guide#cli-commands) command
- [A/B Experiments → Reading the Report](https://coder-eval.com/docs/ab-experiments#reading-the-report)
- [Task Definition Guide](https://coder-eval.com/docs/task-definition-guide)
---
# How Coder Eval compares
**Coder Eval** is a framework for evaluating AI coding agents and their skills. It
runs an agent (Claude Code, Codex, Gemini) in a sandbox against declarative YAML
tasks and scores the files and commands it produces on a weighted 0.0–1.0 scale,
with cost/token telemetry, an A/B experiment layer, skill-activation checks, and CI
pass/fail gates.
The tools below overlap with parts of that scope. This page describes what each is
designed for and when to choose it. Every claim about another project is grounded
in its own documentation; see [Sources](#sources).
## At a glance
| | Coder Eval | SWE-bench | SkillsBench | Harbor | OpenAI Evals | Hand-rolled |
| --- | --- | --- | --- | --- | --- | --- |
| **What it grades** | Files + commands the agent produced | Whether a patch passes the repo's tests | Skill value on a fixed task set | Agent task success in sandboxes | Model text output | Whatever you wire up |
| **Task source** | Your own (YAML) | Fixed benchmark (+ collection script) | Fixed (87 tasks / 8 domains) | Your own (framework) + Terminal-Bench 2.0 | Your own (YAML/JSON) + registry | Manual |
| **Runs a real agent + tools** | ✅ Claude Code, Codex, Gemini | Runs your patch/scaffold | ✅ multi-harness | ✅ Claude Code, OpenHands, Codex | ❌ grades model output | ❌ |
| **Sandboxed & reproducible** | ✅ tempdir / Docker | ✅ Docker | ✅ deterministic verifiers | ✅ Docker + cloud (Daytona/Modal) | — (grades text) | ❌ |
| **Scoring** | Weighted 0.0–1.0 + thresholds | Pass/fail (tests) | Pass/fail (verifiers) | Task-level | Match / model-graded | ❌ |
| **A/B experiments (model / tool / prompt)** | ✅ built-in | ❌ | Skills on/off only | — | Compare model versions | ❌ |
| **Cost / token telemetry** | ✅ per tool call | ❌ | ❌ | — | limited | ❌ |
| **Skill-activation testing** | ✅ `skill_triggered` | ❌ | Measures effect, not trigger | ❌ | ❌ | ❌ |
| **CI pass/fail gate** | ✅ built-in | ❌ | ❌ | ❌ | ❌ | ❌ |
| **Results dashboard** | ✅ evalboard | ❌ | ❌ | ❌ | ❌ | ❌ |
| **Primary interface** | Python + YAML | Python harness + HF dataset | Research benchmark | Python CLI | Python + YAML/JSON | Your choice |
## vs. SWE-bench and fixed benchmarks
[SWE-bench](https://www.swebench.com/) is a fixed benchmark of real GitHub issues.
A model generates a patch, which is graded by running the repository's tests in
Docker; SWE-bench Verified is a human-validated subset of 500 problems, and there
are additional variants (Lite, Multimodal, Multilingual). It includes a
data-collection procedure for building tasks from other repositories, but its
primary use is a shared leaderboard on a canonical dataset.
Coder Eval is a framework for authoring tasks in YAML, with continuous 0.0–1.0
scoring and cost telemetry rather than a single pass/fail. A fixed dataset can be
wrapped as tasks via [Bring Your Own Dataset](https://coder-eval.com/docs/datasets).
**Choose SWE-bench** for a standardized model leaderboard on patch-and-test tasks.
**Choose Coder Eval** to evaluate your own tasks, agents, and skills and to gate CI
on them.
## vs. SkillsBench and skill benchmarks
[SkillsBench](https://arxiv.org/abs/2602.12670) is a fixed research benchmark for
agent skills: 87 tasks across 8 domains, each paired with curated skills and
deterministic verifiers. It compares agents with and without the curated skills
across 18 model-harness configurations and reports a 33.9% → 50.5% average
pass-rate change. It measures whether skills improve performance on that task set.
Coder Eval addresses a related but distinct question about a specific set of skills:
- **Activation vs. effectiveness.** Coder Eval's `skill_triggered` criterion checks
whether the agent engaged the skill (Claude's `Skill` tool call, or Codex reading
the skill's files). SkillsBench measures the downstream effect on task success.
The two are different signals: a skill that does not activate cannot contribute.
- **Reusable in CI.** A skill-on/off comparison can be built with the
[experiment layer](https://coder-eval.com/docs/ab-experiments), gated on each change, and scheduled to
detect regressions over time.
**Choose SkillsBench** for a standardized measure of skill value across domains.
**Choose Coder Eval** to author, activation-test, and regression-check your own
skills.
## vs. Harbor
[Harbor](https://www.harborframework.com/) is a Python framework from the
Terminal-Bench team for evaluating and optimizing agents and language models. It
runs agents (Claude Code, OpenHands, Codex CLI) in sandboxes using Docker and cloud
providers (Daytona, Modal, LangSmith), is the official harness for Terminal-Bench
2.0, can run across large numbers of environments in parallel, and can generate
rollouts for RL optimization. Its emphasis is scale and optimization.
Coder Eval focuses on scoring and workflow for coding-agent and skill suites:
- 14 weighted criterion types (file/regex/JSON checks, `run_command`, AST/token
similarity, LLM- and agent-judges) on a 0.0–1.0 scale with per-criterion
thresholds.
- An [experiment layer](https://coder-eval.com/docs/ab-experiments) for model/tool/prompt A/Bs,
`skill_triggered` activation checks, per-tool cost/token telemetry, CI pass/fail
gates, and the evalboard dashboard.
**Choose Harbor** for large-scale agent evaluation and RL-optimization rollouts,
particularly around Terminal-Bench. **Choose Coder Eval** for weighted, skill-aware
task suites gated in CI.
## vs. OpenAI Evals
[OpenAI Evals](https://github.com/openai/evals) is a framework and registry for
evaluating model output. Data is provided in JSON and parameters in YAML, and
grading uses exact/pattern match or model-graded templates. It evaluates model
output rather than running an autonomous coding agent with tool use in a sandbox,
and contributions of custom-code evals are restricted (model-graded YAML evals are
the accepted path).
Coder Eval runs the full agent and scores the files and commands it produces, with
per-tool cost/token telemetry and skill-activation checks.
**Choose OpenAI Evals** to grade model output and compare model versions. **Choose
Coder Eval** to evaluate agent behavior — the tools it calls, the files it writes,
the commands it runs, and the skills it triggers.
## vs. hand-rolled scripts
A `claude -p` loop is quick to start, but a durable harness requires implementing
sandboxing, weighted criteria, retries, cost/token accounting, A/B configuration, a
results view, and CI reporting. Coder Eval provides these components, so work can
focus on tasks and criteria rather than harness infrastructure.
## When to choose Coder Eval
- Evaluating how well agents use a CLI or Claude Code skills.
- A/B-testing models, tools, or prompts on the same tasks (Claude Code vs. Codex vs. Gemini).
- Detecting skill regressions when a model or prompt changes.
- Gating CI on coding-agent quality.
- Producing reproducible, sandboxed runs scored per file and per command, with a dashboard for review.
## Next steps
- [Tutorial 01 — Your First Evaluation](https://coder-eval.com/docs/tutorials/01-first-evaluation)
- [Tutorial 02 — Running Coder Eval in CI](https://coder-eval.com/docs/tutorials/02-ci-pipeline)
- [A/B Experiments](https://coder-eval.com/docs/ab-experiments)
- [Bring Your Own Dataset](https://coder-eval.com/docs/datasets)
## Sources
Claims about other projects are grounded in their own documentation, retrieved
July 2026:
- SWE-bench — [swebench.com](https://www.swebench.com/) and the
[SWE-bench repository](https://github.com/SWE-bench/SWE-bench) (real GitHub
issues, Docker-reproducible test-based evaluation, Verified = 500 problems).
- SkillsBench — [*Benchmarking How Well Agent Skills Work Across Diverse Tasks*](https://arxiv.org/abs/2602.12670)
(87 tasks / 8 domains, deterministic verifiers, 18 model-harness configs,
33.9% → 50.5% pass-rate lift).
- Harbor — [harborframework.com](https://www.harborframework.com/) and the
[harbor-framework/harbor repository](https://github.com/harbor-framework/harbor)
(Python framework from the Terminal-Bench creators; Docker + multi-cloud sandboxes;
official Terminal-Bench 2.0 harness; parallel across thousands of environments;
RL-optimization rollouts).
- OpenAI Evals — [openai/evals](https://github.com/openai/evals) (framework +
registry; JSON data + YAML params; match and model-graded evals).